<?xml version="1.0" encoding="utf-8"?>
<feed xmlns="http://www.w3.org/2005/Atom">

  <title><![CDATA[Big Data Genomics]]></title>
  <link href="http://bigdatagenomics.github.io/atom.xml" rel="self"/>
  <link href="http://bigdatagenomics.github.io/"/>
  <updated>2018-12-07T10:22:47-08:00</updated>
  <id>http://bigdatagenomics.github.io/</id>
  <author>
    <name><![CDATA[Big Data Genomics]]></name>
    
  </author>
  <generator uri="http://octopress.org/">Octopress</generator>

  
  <entry>
    <title type="html"><![CDATA[ADAM 0.25.0 and Cannoli 0.3.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2018/12/01/adam-0-dot-25-dot-0-cannoli-0-dot-3-dot-0-releases/"/>
    <updated>2018-12-01T00:00:00-08:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2018/12/01/adam-0-dot-25-dot-0-cannoli-0-dot-3-dot-0-releases</id>
    <content type="html"><![CDATA[<p>ADAM <a href="https://github.com/bigdatagenomics/adam/releases">version 0.25.0</a> and
Cannoli <a href="https://github.com/bigdatagenomics/cannoli/releases">version 0.3.0</a> have been released!</p>

<p>Since the 0.24.0 release of ADAM, more then 40 issues have been closed, including bug fixes around
indexed reads and attributes in VCF. New features include additional filter by methods and multi-sample
coverage. The ADAM Python APIs now support Python 3.</p>

<p>Based on feedback from the <a href="https://www.open-bio.org/wiki/BOSC_2018">2018 GCCBOSC bioinformatics community conference</a>,
at <a href="https://galaxyproject.org/events/gccbosc2018/collaboration/">2018 GCCBOSC CollaborationFest</a> the Cannoli API
was refactored to greatly improve interactive use in <code>cannoli-shell</code> (a Scala REPL based on Spark Shell, similar
to <code>adam-shell</code>) and notebooks such as <a href="https://jupyter.org/">Jupyter</a>, <a href="https://zeppelin.apache.org/">Zeppelin</a>,
and <a href="http://spark-notebook.io/">Spark Notebook</a>.</p>

<p>For example, here is an entire variant calling pipeline, based on bwa, ADAM, and Freebayes</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
<span class='line-number'>9</span>
<span class='line-number'>10</span>
<span class='line-number'>11</span>
<span class='line-number'>12</span>
<span class='line-number'>13</span>
<span class='line-number'>14</span>
<span class='line-number'>15</span>
<span class='line-number'>16</span>
<span class='line-number'>17</span>
<span class='line-number'>18</span>
<span class='line-number'>19</span>
<span class='line-number'>20</span>
<span class='line-number'>21</span>
<span class='line-number'>22</span>
<span class='line-number'>23</span>
</pre></td><td class='code'><pre><code class=''><span class='line'>import org.bdgenomics.adam.rdd.ADAMContext._
</span><span class='line'>import org.bdgenomics.cannoli.cli._
</span><span class='line'>import org.bdgenomics.cannoli.cli.Cannoli._
</span><span class='line'>
</span><span class='line'>val sample = "sample"
</span><span class='line'>val reference = "ref.fa"
</span><span class='line'>
</span><span class='line'>val reads = sc.loadPairedFastqAsFragments(sample + "_1.fq", sample + "_2.fq")
</span><span class='line'>
</span><span class='line'>val bwaArgs = new BwaArgs()
</span><span class='line'>bwaArgs.sample = sample
</span><span class='line'>bwaArgs.indexPath = reference
</span><span class='line'>
</span><span class='line'>val alignments = reads.alignWithBwa(bwaArgs)
</span><span class='line'>val sorted = alignments.sortReadsByReferencePositionAndIndex()
</span><span class='line'>val markdup = sorted.markDuplicates()
</span><span class='line'>
</span><span class='line'>val freebayesArgs = new FreebayesArgs()
</span><span class='line'>freebayesArgs.referencePath = reference
</span><span class='line'>
</span><span class='line'>val variantContexts = markdup.callVariantsWithFreebayes(freebayesArgs)
</span><span class='line'>
</span><span class='line'>variantContexts.saveAsVcf(sample + ".freebayes.vcf.bgzf")</span></code></pre></td></tr></table></div></figure>


<h1>Changes since Previous Releases</h1>

<p>The full list of changes to ADAM since version 0.24.0 and Cannoli since version 0.2.0 are below.</p>

<!-- more -->


<h3>ADAM version 0.25.0</h3>

<p><strong>Closed issues:</strong></p>

<ul>
<li>Expand illumina metadata regex to include &ldquo;N&rdquo; character  <a href="https://github.com/bigdatagenomics/adam/issues/2079">#2079</a></li>
<li>Remove support for Hadoop 2.6 <a href="https://github.com/bigdatagenomics/adam/issues/2073">#2073</a></li>
<li>NumberFormatException: For input string: &ldquo;nan&rdquo; in VCF <a href="https://github.com/bigdatagenomics/adam/issues/2068">#2068</a></li>
<li>Support Spark 2.3.2 <a href="https://github.com/bigdatagenomics/adam/issues/2062">#2062</a></li>
<li>Arrays should be passed to HTSJDK in the JVM primitive type <a href="https://github.com/bigdatagenomics/adam/issues/2059">#2059</a></li>
<li>toCoverage() function for alignments does not distinguish samples <a href="https://github.com/bigdatagenomics/adam/issues/2049">#2049</a></li>
<li>Building from adam-core module directory fails to generate Scala code for sql package <a href="https://github.com/bigdatagenomics/adam/issues/2047">#2047</a></li>
<li>Data Sets <a href="https://github.com/bigdatagenomics/adam/issues/2043">#2043</a></li>
<li>saveAsBed writes missing score values as &lsquo;.&rsquo; instead of &lsquo;0&rsquo; <a href="https://github.com/bigdatagenomics/adam/issues/2039">#2039</a></li>
<li>Fix GFF3 parser to handle trailing FASTA <a href="https://github.com/bigdatagenomics/adam/issues/2037">#2037</a></li>
<li>Add StorageLevel as an optional parameter to loadPairedFastq <a href="https://github.com/bigdatagenomics/adam/issues/2032">#2032</a></li>
<li>Error: File name too long when building on encrypted file system <a href="https://github.com/bigdatagenomics/adam/issues/2031">#2031</a></li>
<li>Fail to transform a VCF  file containing multiple genome data (Muliple sample) <a href="https://github.com/bigdatagenomics/adam/issues/2029">#2029</a></li>
<li>Dataset and RDD constructors are missing from CoverageRDD <a href="https://github.com/bigdatagenomics/adam/issues/2027">#2027</a></li>
<li>How to create a single RDD[Genotype] object out of multiple VCF files? <a href="https://github.com/bigdatagenomics/adam/issues/2025">#2025</a></li>
<li>ReadTheDocs github banner is broken <a href="https://github.com/bigdatagenomics/adam/issues/2020">#2020</a></li>
<li>-realign_indels throws serialization error with instrumentation enabled <a href="https://github.com/bigdatagenomics/adam/issues/2007">#2007</a></li>
<li>Support 0 length FASTQ reads <a href="https://github.com/bigdatagenomics/adam/issues/2006">#2006</a></li>
<li>Speed of Reading into ADAM RDDs from S3 <a href="https://github.com/bigdatagenomics/adam/issues/2003">#2003</a></li>
<li>Support Python 3 <a href="https://github.com/bigdatagenomics/adam/issues/1999">#1999</a></li>
<li>Unordered list of region join types in doc is missing nested levels <a href="https://github.com/bigdatagenomics/adam/issues/1997">#1997</a></li>
<li>Add VariantContextRDD.saveAsPartitionedParquet, ADAMContext.loadPartitionedParquetVariantContexts <a href="https://github.com/bigdatagenomics/adam/issues/1996">#1996</a></li>
<li>VCF annotation question <a href="https://github.com/bigdatagenomics/adam/issues/1994">#1994</a></li>
<li>Fastq reader clips long reads at 10,000 bp <a href="https://github.com/bigdatagenomics/adam/issues/1992">#1992</a></li>
<li>adam-submit Error: Number of executors must be a positive number on EMR 5.13.0/Spark 2.3.0 <a href="https://github.com/bigdatagenomics/adam/issues/1991">#1991</a></li>
<li>Test against Spark 2.3.1, Parquet 1.8.3 <a href="https://github.com/bigdatagenomics/adam/issues/1989">#1989</a></li>
<li>END does not get set when writing a gVCF <a href="https://github.com/bigdatagenomics/adam/issues/1988">#1988</a></li>
<li>Support saving single files to filesystems that don&rsquo;t implement getScheme <a href="https://github.com/bigdatagenomics/adam/issues/1984">#1984</a></li>
<li>Add additional filter by convenience methods <a href="https://github.com/bigdatagenomics/adam/issues/1978">#1978</a></li>
<li>Limiting FragmentRDD pipe paralellism <a href="https://github.com/bigdatagenomics/adam/issues/1977">#1977</a></li>
<li>Consider javadoc.io for API documentation linking <a href="https://github.com/bigdatagenomics/adam/issues/1976">#1976</a></li>
<li>FASTQ Reader leaks connections <a href="https://github.com/bigdatagenomics/adam/issues/1974">#1974</a></li>
<li>Update bioconda recipe for version 0.24.0 <a href="https://github.com/bigdatagenomics/adam/issues/1971">#1971</a></li>
<li>Update homebrew formula at brewsci/homebrew-bio for version 0.24.0 <a href="https://github.com/bigdatagenomics/adam/issues/1970">#1970</a></li>
<li>loadPartitionedParquetAlignments fails with Reference.all <a href="https://github.com/bigdatagenomics/adam/issues/1967">#1967</a></li>
<li>Caused by: java.lang.VerifyError: class com.fasterxml.jackson.module.scala.ser.ScalaIteratorSerializer overrides final method withResolved <a href="https://github.com/bigdatagenomics/adam/issues/1953">#1953</a></li>
<li>FASTQ input format needs to support index sequences <a href="https://github.com/bigdatagenomics/adam/issues/1697">#1697</a></li>
<li>Changelog must be edited and committed manually during release process <a href="https://github.com/bigdatagenomics/adam/issues/936">#936</a></li>
</ul>


<p><strong>Merged and closed pull requests:</strong></p>

<ul>
<li>added pyspark mock modules for API documentation <a href="https://github.com/bigdatagenomics/adam/pull/2084">#2084</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Added mock python modules for API python documentation <a href="https://github.com/bigdatagenomics/adam/pull/2082">#2082</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-2079] Expand illumina metadata regex to include &ldquo;N&rdquo; character <a href="https://github.com/bigdatagenomics/adam/pull/2081">#2081</a> (<a href="https://github.com/pauldwolfe">pauldwolfe</a>)</li>
<li>ADAM-2079 Added &ldquo;N&rdquo; to regexs for illumina metadata <a href="https://github.com/bigdatagenomics/adam/pull/2080">#2080</a> (<a href="https://github.com/pauldwolfe">pauldwolfe</a>)</li>
<li>Update docs with new template and documentation <a href="https://github.com/bigdatagenomics/adam/pull/2078">#2078</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1992] Make maximum FASTQ read length configurable. <a href="https://github.com/bigdatagenomics/adam/pull/2077">#2077</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-2059] Properly pass back primitive typed arrays to HTSJDK. <a href="https://github.com/bigdatagenomics/adam/pull/2075">#2075</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Update dependency versions, including htsjdk to 2.16.1 and guava to 27.0-jre <a href="https://github.com/bigdatagenomics/adam/pull/2072">#2072</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1999] Support Python 3 <a href="https://github.com/bigdatagenomics/adam/pull/2070">#2070</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-2068] Prevent NumberFormatException for nan vs NaN in VCF files. <a href="https://github.com/bigdatagenomics/adam/pull/2069">#2069</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Update python MAKE file <a href="https://github.com/bigdatagenomics/adam/pull/2067">#2067</a> (<a href="https://github.com/Georgehe4">Georgehe4</a>)</li>
<li>Update python MAKE file <a href="https://github.com/bigdatagenomics/adam/pull/2066">#2066</a> (<a href="https://github.com/Georgehe4">Georgehe4</a>)</li>
<li>Update jenkins script to test python 3.6 <a href="https://github.com/bigdatagenomics/adam/pull/2060">#2060</a> (<a href="https://github.com/Georgehe4">Georgehe4</a>)</li>
<li>[ADAM-2062] Update Spark version to 2.3.2 <a href="https://github.com/bigdatagenomics/adam/pull/2055">#2055</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Clean up fields and doc in fragment. <a href="https://github.com/bigdatagenomics/adam/pull/2054">#2054</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-2037] Support GFF3 files containing FASTA formatted sequences. <a href="https://github.com/bigdatagenomics/adam/pull/2053">#2053</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>modified CoverageRDD and FeatureRDD to extend MultisampleGenomicDataset <a href="https://github.com/bigdatagenomics/adam/pull/2051">#2051</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Multi-sample coverage <a href="https://github.com/bigdatagenomics/adam/pull/2050">#2050</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-2047] Use source directory relative to project.basedir for adam codegen. <a href="https://github.com/bigdatagenomics/adam/pull/2048">#2048</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-2039] Adding support for writing BED format per UCSC definition <a href="https://github.com/bigdatagenomics/adam/pull/2042">#2042</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Update Jenkins Spark version to 2.2.2 <a href="https://github.com/bigdatagenomics/adam/pull/2035">#2035</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-2032] Add StorageLevel as an optional parameter to loadPairedFastq <a href="https://github.com/bigdatagenomics/adam/pull/2033">#2033</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-2027] Add RDD and Dataset constructors to CoverageRDD. <a href="https://github.com/bigdatagenomics/adam/pull/2028">#2028</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Allow for export of query name sorted SAM files <a href="https://github.com/bigdatagenomics/adam/pull/2026">#2026</a> (<a href="https://github.com/karenfeng">karenfeng</a>)</li>
<li>[ADAM-2020] Fix ReadTheDocs Github banner. <a href="https://github.com/bigdatagenomics/adam/pull/2021">#2021</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1988] Add copyVariantEndToAttribute method to support gVCF END attribute … <a href="https://github.com/bigdatagenomics/adam/pull/2017">#2017</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-936] Use github-changes-maven-plugin to update CHANGES.md. <a href="https://github.com/bigdatagenomics/adam/pull/2014">#2014</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1992] Make maximum FASTQ read length configurable. <a href="https://github.com/bigdatagenomics/adam/pull/2011">#2011</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1697] Expand Illumina metadata regex to cover interleaved index sequences. <a href="https://github.com/bigdatagenomics/adam/pull/2010">#2010</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-2007] Make IndelRealignmentTarget implement Serializable. <a href="https://github.com/bigdatagenomics/adam/pull/2009">#2009</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-2006] Support loading 0-length reads as FASTQ. <a href="https://github.com/bigdatagenomics/adam/pull/2008">#2008</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1697] Expand Illumina metadata regex to cover index sequences <a href="https://github.com/bigdatagenomics/adam/pull/2004">#2004</a> (<a href="https://github.com/pauldwolfe">pauldwolfe</a>)</li>
<li>[ADAM-1996] Load and save VariantContexts as partitioned Parquet. <a href="https://github.com/bigdatagenomics/adam/pull/2001">#2001</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1997] Nest list of region join types in joins doc. <a href="https://github.com/bigdatagenomics/adam/pull/1998">#1998</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1877] Add filterToReferenceName(s) to SequenceDictionary. <a href="https://github.com/bigdatagenomics/adam/pull/1995">#1995</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1984] Support file systems that don&rsquo;t set the scheme. <a href="https://github.com/bigdatagenomics/adam/pull/1985">#1985</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1978] Add additional filter by convenience methods. <a href="https://github.com/bigdatagenomics/adam/pull/1983">#1983</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Adding printAttribute methods for alignment records, features, and samples. <a href="https://github.com/bigdatagenomics/adam/pull/1982">#1982</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Fix partitioning code to use Long instead of Int <a href="https://github.com/bigdatagenomics/adam/pull/1980">#1980</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1976] Adding core API documentation link and badge. <a href="https://github.com/bigdatagenomics/adam/pull/1979">#1979</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1974] Close unclosed stream in FastqInputFormat. <a href="https://github.com/bigdatagenomics/adam/pull/1975">#1975</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Set defaults to schemas <a href="https://github.com/bigdatagenomics/adam/pull/1972">#1972</a> (<a href="https://github.com/ffinfo">ffinfo</a>)</li>
<li>Add loadPairedFastqAsFragments method. <a href="https://github.com/bigdatagenomics/adam/pull/1866">#1866</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Adding loadPairedFastqAsFragments method <a href="https://github.com/bigdatagenomics/adam/pull/1828">#1828</a> (<a href="https://github.com/ffinfo">ffinfo</a>)</li>
</ul>


<h3>Cannoli Version 0.3.0</h3>

<p><strong>Closed issues:</strong></p>

<ul>
<li>Add implicit methods that attach to source RDD <a href="https://github.com/bigdatagenomics/cannoli/issues/131">#131</a></li>
<li>Flip function and command line class names around <a href="https://github.com/bigdatagenomics/cannoli/issues/130">#130</a></li>
<li>Add API documentation link and badge <a href="https://github.com/bigdatagenomics/cannoli/issues/128">#128</a></li>
<li>Add homebrew formula at brewsci/homebrew-bio <a href="https://github.com/bigdatagenomics/cannoli/issues/124">#124</a></li>
<li>Add bioconda recipe <a href="https://github.com/bigdatagenomics/cannoli/issues/123">#123</a></li>
<li>Support validation stringency in out formatters <a href="https://github.com/bigdatagenomics/cannoli/issues/122">#122</a></li>
<li>Add Ensembl Variant Effect Predictor (VEP) for variant annotation <a href="https://github.com/bigdatagenomics/cannoli/issues/112">#112</a></li>
<li>Add Minimap2 for alignment <a href="https://github.com/bigdatagenomics/cannoli/issues/111">#111</a></li>
</ul>


<p><strong>Merged and closed pull requests:</strong></p>

<ul>
<li>Update release script for changelog. <a href="https://github.com/bigdatagenomics/cannoli/pull/143">#143</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-141] Update ADAM dependency to 0.25.0. <a href="https://github.com/bigdatagenomics/cannoli/pull/142">#142</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Update default docker image for bowtie2. <a href="https://github.com/bigdatagenomics/cannoli/pull/140">#140</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-138] Update Cannoli per latest ADAM snapshot changes. <a href="https://github.com/bigdatagenomics/cannoli/pull/139">#139</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-131] Add implicits on Cannoli function source data sets. <a href="https://github.com/bigdatagenomics/cannoli/pull/133">#133</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-130] Extract function classes to core package. <a href="https://github.com/bigdatagenomics/cannoli/pull/132">#132</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-128] Adding API documentation link and badge. <a href="https://github.com/bigdatagenomics/cannoli/pull/129">#129</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-112]  Adding Ensembl Variant Effect Predictor (VEP) for variant annotation <a href="https://github.com/bigdatagenomics/cannoli/pull/127">#127</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-122] Support validation stringency in out formatters. <a href="https://github.com/bigdatagenomics/cannoli/pull/126">#126</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-111] Adding Minimap2 for alignment. <a href="https://github.com/bigdatagenomics/cannoli/pull/119">#119</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.24.0 and Cannoli 0.2.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2018/03/28/adam-0-dot-24-dot-0-cannoli-0-dot-2-dot-0-releases/"/>
    <updated>2018-03-28T00:00:00-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2018/03/28/adam-0-dot-24-dot-0-cannoli-0-dot-2-dot-0-releases</id>
    <content type="html"><![CDATA[<p>ADAM <a href="https://github.com/bigdatagenomics/adam/releases">version 0.24.0</a> and
Cannoli <a href="https://github.com/bigdatagenomics/cannoli/releases">version 0.2.0</a> have been released!</p>

<p>As of version 0.24.0, support for Spark version 1.x and Scala 2.10.x has been dropped. ADAM and
Cannoli currently build against Spark version 2.3.0 and Scala version 2.11.12.</p>

<p>Major new features in ADAM version 0.24.0 include Spark SQL support across all genomic data
types and access to the ADAM region join API through Python and R. The ADAM Python and R APIs are
now feature complete relative to ADAM&rsquo;s Java API. ADAM version 0.24.0 also introduces
Hive-style partitioning by genomic range for Parquet-backed Datasets. This greatly improves
performance for genomic range based queries.</p>

<p>With version 0.2.0, Cannoli now provides a functional API for interactive use in
<code>cannoli-shell</code> (a Scala REPL based on Spark Shell, similar to <code>adam-shell</code>) and
notebooks such as <a href="https://jupyter.org/">Jupyter</a>, <a href="https://zeppelin.apache.org/">Zeppelin</a>,
and <a href="http://spark-notebook.io/">Spark Notebook</a>. This API allows for multiple
Cannoli-wrapped bioinformatics tools as processes in a larger Spark-based workflow
without having to write out to disk intermediately.</p>

<h1>Changes since Previous Releases</h1>

<p>The full list of changes to ADAM since version 0.23.0 and Cannoli since version 0.1.0 are below.</p>

<!-- more -->


<h3>ADAM Version 0.24.0</h3>

<p><strong>Closed issues:</strong></p>

<ul>
<li>Phred values from 156–254 do not round trip properly between log space <a href="https://github.com/bigdatagenomics/adam/issues/1964">#1964</a></li>
<li>Support VCF lines with positions at 0 <a href="https://github.com/bigdatagenomics/adam/issues/1959">#1959</a></li>
<li>Don&rsquo;t initialize non-ref values to Int.MinValue <a href="https://github.com/bigdatagenomics/adam/issues/1957">#1957</a></li>
<li>Support downsampling in recalibration <a href="https://github.com/bigdatagenomics/adam/issues/1955">#1955</a></li>
<li>Cannot waive validation stringency for INFO Number=.,Type=Flag fields <a href="https://github.com/bigdatagenomics/adam/issues/1939">#1939</a></li>
<li>Clip phred scores below Int.MaxValue <a href="https://github.com/bigdatagenomics/adam/issues/1934">#1934</a></li>
<li>ADAMContext.getFsAndFilesWithFilter should throw exception if paths null or empty <a href="https://github.com/bigdatagenomics/adam/issues/1932">#1932</a></li>
<li>Bump to Spark 2.3.0 <a href="https://github.com/bigdatagenomics/adam/issues/1931">#1931</a></li>
<li>util.FileExtensions should be public for use downstream in Cannoli <a href="https://github.com/bigdatagenomics/adam/issues/1927">#1927</a></li>
<li>Reduce logging level for ADAMKryoRegistrator <a href="https://github.com/bigdatagenomics/adam/issues/1925">#1925</a></li>
<li>Revisit performance implications of commit 1eed8e8 <a href="https://github.com/bigdatagenomics/adam/issues/1923">#1923</a></li>
<li>add akmorrow13 to PyPl for bdgenomics.adam <a href="https://github.com/bigdatagenomics/adam/issues/1919">#1919</a></li>
<li>Read the Docs build failing with TypeError: super() argument 1 must be type, not None <a href="https://github.com/bigdatagenomics/adam/issues/1917">#1917</a></li>
<li>Bump Hadoop-BAM dependency to 7.9.2. <a href="https://github.com/bigdatagenomics/adam/issues/1915">#1915</a></li>
<li>cannot run pyadam from adam distribution 0.23.0 <a href="https://github.com/bigdatagenomics/adam/issues/1914">#1914</a></li>
<li>adam2fasta/q are missing asSingleFile, disableFastConcat <a href="https://github.com/bigdatagenomics/adam/issues/1912">#1912</a></li>
<li>Pipe API doesn&rsquo;t properly handle multiple arguments and spaces <a href="https://github.com/bigdatagenomics/adam/issues/1909">#1909</a></li>
<li>Bump to HTSJDK 2.13.2 <a href="https://github.com/bigdatagenomics/adam/issues/1907">#1907</a></li>
<li>S3A error: HTTP request: Timeout waiting for connection from pool <a href="https://github.com/bigdatagenomics/adam/issues/1906">#1906</a></li>
<li>InputStream passed to VCFHeaderReader does not get closed <a href="https://github.com/bigdatagenomics/adam/issues/1900">#1900</a></li>
<li>Support INFO fields set to missing <a href="https://github.com/bigdatagenomics/adam/issues/1898">#1898</a></li>
<li>CLI to transfer between cloud storage and HDFS <a href="https://github.com/bigdatagenomics/adam/issues/1896">#1896</a></li>
<li>Jenkins does not run python or R tests <a href="https://github.com/bigdatagenomics/adam/issues/1889">#1889</a></li>
<li>pyadam throws application option error <a href="https://github.com/bigdatagenomics/adam/issues/1886">#1886</a></li>
<li>ReferenceRegion in python does not exist <a href="https://github.com/bigdatagenomics/adam/issues/1884">#1884</a></li>
<li>Caching GenomicRDD in pyspark <a href="https://github.com/bigdatagenomics/adam/issues/1883">#1883</a></li>
<li>adam-submit aborts if ADAM_HOME is set <a href="https://github.com/bigdatagenomics/adam/issues/1882">#1882</a></li>
<li>Allow piped commands to timeout <a href="https://github.com/bigdatagenomics/adam/issues/1875">#1875</a></li>
<li>loadVcf does not dedupe sample ID <a href="https://github.com/bigdatagenomics/adam/issues/1874">#1874</a></li>
<li>Add coverage command for reporting read coverage <a href="https://github.com/bigdatagenomics/adam/issues/1873">#1873</a></li>
<li>Only python 2?  <a href="https://github.com/bigdatagenomics/adam/issues/1871">#1871</a></li>
<li>Support VariantContextRDD from SQL <a href="https://github.com/bigdatagenomics/adam/issues/1867">#1867</a></li>
<li>Cannot find <code>find-adam-assembly.sh</code> in bioconda build <a href="https://github.com/bigdatagenomics/adam/issues/1862">#1862</a></li>
<li><code>_jvm.java.lang.Class.forName</code> does not work for certain configurations <a href="https://github.com/bigdatagenomics/adam/issues/1858">#1858</a></li>
<li>Formatting error in CHANGES.md <a href="https://github.com/bigdatagenomics/adam/issues/1857">#1857</a></li>
<li>Various improvements to readthedocs documentation <a href="https://github.com/bigdatagenomics/adam/issues/1853">#1853</a></li>
<li>add filterByOverlappingRegion(query: ReferenceRegion) to R and python APIs <a href="https://github.com/bigdatagenomics/adam/issues/1852">#1852</a></li>
<li>Support adding VCF header lines from Python <a href="https://github.com/bigdatagenomics/adam/issues/1840">#1840</a></li>
<li>Support loadIndexedBam from Python <a href="https://github.com/bigdatagenomics/adam/issues/1836">#1836</a></li>
<li>Add link to awesome list of applications that extend ADAM <a href="https://github.com/bigdatagenomics/adam/issues/1832">#1832</a></li>
<li>loadIndexed bam lazily throws Exception if index does not exist <a href="https://github.com/bigdatagenomics/adam/issues/1830">#1830</a></li>
<li>OAuth credentials for Github in Coveralls configuration are no longer valid <a href="https://github.com/bigdatagenomics/adam/issues/1829">#1829</a></li>
<li>base counts per position <a href="https://github.com/bigdatagenomics/adam/issues/1825">#1825</a></li>
<li>Issues loading BAM files in Google FS <a href="https://github.com/bigdatagenomics/adam/issues/1816">#1816</a></li>
<li>Error when writing a vcf file to Parquet <a href="https://github.com/bigdatagenomics/adam/issues/1810">#1810</a></li>
<li>transformAlignments cannot repartition files <a href="https://github.com/bigdatagenomics/adam/issues/1808">#1808</a></li>
<li>GenotypeRDD should support <code>toVariants</code> method <a href="https://github.com/bigdatagenomics/adam/issues/1806">#1806</a></li>
<li>Add support for python and R in Homebrew formula <a href="https://github.com/bigdatagenomics/adam/issues/1796">#1796</a></li>
<li>Add <code>transformVariantContexts</code> or similar to cli <a href="https://github.com/bigdatagenomics/adam/issues/1793">#1793</a></li>
<li>Issue while using Sorting option <a href="https://github.com/bigdatagenomics/adam/issues/1791">#1791</a></li>
<li>Issue with adam2vcf <a href="https://github.com/bigdatagenomics/adam/issues/1787">#1787</a></li>
<li>Remove explicit <code>&lt;compile&gt;</code> scopes from submodule POMs <a href="https://github.com/bigdatagenomics/adam/issues/1786">#1786</a></li>
<li>java.nio.file.ProviderNotFoundException (Provider &ldquo;s3&rdquo; not found) <a href="https://github.com/bigdatagenomics/adam/issues/1732">#1732</a></li>
<li>Accessing GenomicRDD join functions in python <a href="https://github.com/bigdatagenomics/adam/issues/1728">#1728</a></li>
<li>ArrayIndexOutOfBoundsException in PhredUtils$.phredToSuccessProbability <a href="https://github.com/bigdatagenomics/adam/issues/1714">#1714</a></li>
<li>Add ability to specify region bounds to pipe command <a href="https://github.com/bigdatagenomics/adam/issues/1707">#1707</a></li>
<li>Unable to run pyadam, SQLException: Failed to start database &lsquo;metastore_db&rsquo; <a href="https://github.com/bigdatagenomics/adam/issues/1666">#1666</a></li>
<li>SAMFormatException: Unrecognized tag type: ^@ <a href="https://github.com/bigdatagenomics/adam/issues/1657">#1657</a></li>
<li>IndexOutOfBoundsException in BAMInputFormat.getSplits <a href="https://github.com/bigdatagenomics/adam/issues/1656">#1656</a></li>
<li>overlaps considers that Strand.FORWARD cannot overlap with Strand.INDEPENDENT <a href="https://github.com/bigdatagenomics/adam/issues/1650">#1650</a></li>
<li>migration converters <a href="https://github.com/bigdatagenomics/adam/issues/1629">#1629</a></li>
<li>RFC: Removing Spark 1.x, Scala 2.10 support in 0.24.0 release <a href="https://github.com/bigdatagenomics/adam/issues/1597">#1597</a></li>
<li>Eliminate unused ConcreteADAMRDDFunctions class <a href="https://github.com/bigdatagenomics/adam/issues/1580">#1580</a></li>
<li>Add set theory/statistics packages to ADAM <a href="https://github.com/bigdatagenomics/adam/issues/1533">#1533</a></li>
<li>Evaluate Apache Carbondata INDEXED column store file format for genomics <a href="https://github.com/bigdatagenomics/adam/issues/1527">#1527</a></li>
<li>Stranded vs unstranded in getReferenceRegions() for features <a href="https://github.com/bigdatagenomics/adam/issues/1513">#1513</a></li>
<li>Question:How to tranform a line of sam to AlignmentRecord? <a href="https://github.com/bigdatagenomics/adam/issues/1425">#1425</a></li>
<li>Excessive compilation warnings about multiple scala libraries <a href="https://github.com/bigdatagenomics/adam/issues/695">#695</a></li>
<li>Support Hive-style partitioning <a href="https://github.com/bigdatagenomics/adam/issues/651">#651</a></li>
</ul>


<p><strong>Merged and closed pull requests:</strong></p>

<ul>
<li>[ADAM-1964] Lower point where phred conversions are done using log code. <a href="https://github.com/bigdatagenomics/adam/pull/1965">#1965</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add utility methods for adam-shell. <a href="https://github.com/bigdatagenomics/adam/pull/1958">#1958</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1955] Add support for downsampling during recalibration table generation <a href="https://github.com/bigdatagenomics/adam/pull/1963">#1963</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1957] Don&rsquo;t initialize missing likelihoods to MinValue. <a href="https://github.com/bigdatagenomics/adam/pull/1961">#1961</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1959] Support VCF rows at position 0. <a href="https://github.com/bigdatagenomics/adam/pull/1960">#1960</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-651] Implement Hive-style partitioning by genomic range of Parquet backed datasets <a href="https://github.com/bigdatagenomics/adam/pull/1948">#1948</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1914] Python profile needs to be specified for egg to be in distribution. <a href="https://github.com/bigdatagenomics/adam/pull/1946">#1946</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1917] Delete dependency on fulltoc. <a href="https://github.com/bigdatagenomics/adam/pull/1944">#1944</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1917] Try 3: fix Sphinx fulltoc. <a href="https://github.com/bigdatagenomics/adam/pull/1943">#1943</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1917] Set Sphinx version in requirements.txt. <a href="https://github.com/bigdatagenomics/adam/pull/1942">#1942</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1917] Set minimal Sphinx version for Readthedocs build. <a href="https://github.com/bigdatagenomics/adam/pull/1941">#1941</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1939] Allow validation stringency to waive off FLAG arrays. <a href="https://github.com/bigdatagenomics/adam/pull/1940">#1940</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1915] Bump to Hadoop-BAM 7.9.2. <a href="https://github.com/bigdatagenomics/adam/pull/1938">#1938</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1934] Clip phred values to 3233, instead of Int.MaxValue. <a href="https://github.com/bigdatagenomics/adam/pull/1936">#1936</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Ignore VCF INFO fields with number=G when stringency=LENIENT <a href="https://github.com/bigdatagenomics/adam/pull/1935">#1935</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>[ADAM-1931] Bump to Spark 2.3.0. <a href="https://github.com/bigdatagenomics/adam/pull/1933">#1933</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1840] Support adding VCF header lines from Python. <a href="https://github.com/bigdatagenomics/adam/pull/1930">#1930</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1927] Increase visibility for util.FileExtensions for use downstream. <a href="https://github.com/bigdatagenomics/adam/pull/1929">#1929</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1925] Reduce logging level for ADAMKryoRegistrator. <a href="https://github.com/bigdatagenomics/adam/pull/1928">#1928</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1923] Revert 1eed8e8 <a href="https://github.com/bigdatagenomics/adam/pull/1926">#1926</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Use SparkFiles.getRootDirectory in local mode. <a href="https://github.com/bigdatagenomics/adam/pull/1924">#1924</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-651] Implement Hive-style partitioning by genomic range of Parquet backed datasets <a href="https://github.com/bigdatagenomics/adam/pull/1922">#1922</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>Make Spark SQL APIs supported across all types <a href="https://github.com/bigdatagenomics/adam/pull/1921">#1921</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1909] Refactor pipe cmd parameter from String to Seq[String]. <a href="https://github.com/bigdatagenomics/adam/pull/1920">#1920</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Add Google Cloud documentation <a href="https://github.com/bigdatagenomics/adam/pull/1918">#1918</a> (<a href="https://github.com/Georgehe4">Georgehe4</a>)</li>
<li>[ADAM-1917] Load sphinxcontrib.fulltoc with imp.load_sources. <a href="https://github.com/bigdatagenomics/adam/pull/1916">#1916</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1912] Add asSingleFile, disableFastConcat to adam2fasta/q. <a href="https://github.com/bigdatagenomics/adam/pull/1913">#1913</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-651] Hive-style partitioning of parquet files by genomic position <a href="https://github.com/bigdatagenomics/adam/pull/1911">#1911</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>Minor unit test/style fixes. <a href="https://github.com/bigdatagenomics/adam/pull/1910">#1910</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1907] Bump to HTSJDK 2.13.2. <a href="https://github.com/bigdatagenomics/adam/pull/1908">#1908</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1882] Don&rsquo;t abort adam-submit if ADAM_HOME is set. <a href="https://github.com/bigdatagenomics/adam/pull/1905">#1905</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1806] Add toVariants conversion from GenotypeRDD. <a href="https://github.com/bigdatagenomics/adam/pull/1904">#1904</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1882] Return true if ADAM_HOME is set, not exit 0. <a href="https://github.com/bigdatagenomics/adam/pull/1903">#1903</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1900] Close stream after reading VCF header. <a href="https://github.com/bigdatagenomics/adam/pull/1901">#1901</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1898] Support converting INFO fields set to empty (&lsquo;.&rsquo;). <a href="https://github.com/bigdatagenomics/adam/pull/1899">#1899</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add Kryo registration for two classes required for Spark 2.3.0. <a href="https://github.com/bigdatagenomics/adam/pull/1897">#1897</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>[ADAM-1853] Various improvements to readthedocs documentation. <a href="https://github.com/bigdatagenomics/adam/pull/1893">#1893</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1889][ADAM-1884] updated ReferenceRegion in python <a href="https://github.com/bigdatagenomics/adam/pull/1892">#1892</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1889] Run R/Python tests. <a href="https://github.com/bigdatagenomics/adam/pull/1890">#1890</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1886] fix for pyadam to recognize >1 egg file <a href="https://github.com/bigdatagenomics/adam/pull/1887">#1887</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1883] Python and R caching <a href="https://github.com/bigdatagenomics/adam/pull/1885">#1885</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1875] Add ability to timeout a piped command. <a href="https://github.com/bigdatagenomics/adam/pull/1881">#1881</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1871] Fix print call that broke python 3 support. <a href="https://github.com/bigdatagenomics/adam/pull/1880">#1880</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1832] Use awesome list style and link to bigdatagenomics/awesome-adam. <a href="https://github.com/bigdatagenomics/adam/pull/1879">#1879</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-651] Hive-style partitioning of parquet files by genomic position <a href="https://github.com/bigdatagenomics/adam/pull/1878">#1878</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>[ADAM-1874] Dedupe samples when loading VCFs. <a href="https://github.com/bigdatagenomics/adam/pull/1876">#1876</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Fixes Coverage python API and adds tests <a href="https://github.com/bigdatagenomics/adam/pull/1870">#1870</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>added filterByOverlappingRegion for python <a href="https://github.com/bigdatagenomics/adam/pull/1869">#1869</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Add command line option for populating nested variant.annotation field in Genotype records. <a href="https://github.com/bigdatagenomics/adam/pull/1865">#1865</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Hive partitioned(v4) rebased <a href="https://github.com/bigdatagenomics/adam/pull/1864">#1864</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>[ADAM-1597] Move to Scala 2.11 and Spark 2.x. <a href="https://github.com/bigdatagenomics/adam/pull/1861">#1861</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1857] Fix formatting error due to forward slashes. <a href="https://github.com/bigdatagenomics/adam/pull/1860">#1860</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1858] Use getattr instead of Class.forName from python API. <a href="https://github.com/bigdatagenomics/adam/pull/1859">#1859</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1836] Adds loadIndexedBam API to Python and Java. <a href="https://github.com/bigdatagenomics/adam/pull/1837">#1837</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Added check for bam index files in loadIndexedBam <a href="https://github.com/bigdatagenomics/adam/pull/1831">#1831</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1793] Adding vcf2adam and adam2vcf that handle separate variant and genotype data. <a href="https://github.com/bigdatagenomics/adam/pull/1794">#1794</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>added adam notebook <a href="https://github.com/bigdatagenomics/adam/pull/1778">#1778</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1666] SQLContext creation fix for Spark 2.x <a href="https://github.com/bigdatagenomics/adam/pull/1777">#1777</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Add optional accumulator for VCF header lines to VCFOutFormatter. <a href="https://github.com/bigdatagenomics/adam/pull/1727">#1727</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>add hive style partitioning for contigName <a href="https://github.com/bigdatagenomics/adam/pull/1620">#1620</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>Add loadReadsFromSamString function into ADAMContext <a href="https://github.com/bigdatagenomics/adam/pull/1434">#1434</a> (<a href="https://github.com/xubo245">xubo245</a>)</li>
</ul>


<h3>Cannoli Version 0.2.0</h3>

<p><strong>Closed issues:</strong></p>

<ul>
<li>Update ADAM dependency version to 0.24.0. <a href="https://github.com/bigdatagenomics/cannoli/issues/118">#118</a></li>
<li>Javadoc error and warnings <a href="https://github.com/bigdatagenomics/cannoli/issues/115">#115</a></li>
<li>Update pipe method calls due to latest ADAM 0.24.0 snapshot <a href="https://github.com/bigdatagenomics/cannoli/issues/114">#114</a></li>
<li>Split commands with subcommands into separate Cannoli CLI classes <a href="https://github.com/bigdatagenomics/cannoli/issues/110">#110</a></li>
<li>Jenkins build failing due to upstream changes. <a href="https://github.com/bigdatagenomics/cannoli/issues/108">#108</a></li>
<li>Provide functions for use in cannoli-shell or notebooks. <a href="https://github.com/bigdatagenomics/cannoli/issues/104">#104</a></li>
<li>Error running BWA with Docker <a href="https://github.com/bigdatagenomics/cannoli/issues/103">#103</a></li>
<li>Allow use of Singularity instead of Docker <a href="https://github.com/bigdatagenomics/cannoli/issues/98">#98</a></li>
<li>Bump ADAM dependency version to 0.24.0-SNAPSHOT. <a href="https://github.com/bigdatagenomics/cannoli/issues/95">#95</a></li>
<li>Drop support for Scala 2.10 and Spark 1.x. <a href="https://github.com/bigdatagenomics/cannoli/issues/94">#94</a></li>
<li>Tidy up FreeBayes <a href="https://github.com/bigdatagenomics/cannoli/issues/67">#67</a></li>
<li>Support loading reference files from HDFS/other file system <a href="https://github.com/bigdatagenomics/cannoli/issues/50">#50</a></li>
<li>Attributes from freebayes header missing from variants and genotypes <a href="https://github.com/bigdatagenomics/cannoli/issues/43">#43</a></li>
<li>Factor out docker/mapping code <a href="https://github.com/bigdatagenomics/cannoli/issues/34">#34</a></li>
<li>Add wrappers for GMAP and GSNAP aligners <a href="https://github.com/bigdatagenomics/cannoli/issues/29">#29</a></li>
<li>Jenkins failures due to missing publish_scaladoc.sh <a href="https://github.com/bigdatagenomics/cannoli/issues/21">#21</a></li>
</ul>


<p><strong>Merged and closed pull requests:</strong></p>

<ul>
<li>[CANNOLI-118] Update ADAM dependency version to 0.24.0. <a href="https://github.com/bigdatagenomics/cannoli/pull/121">#121</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-110] Split commands with subcommands into separate Cannoli CLI classes. <a href="https://github.com/bigdatagenomics/cannoli/pull/117">#117</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-115] Fix javadoc error and warnings. <a href="https://github.com/bigdatagenomics/cannoli/pull/116">#116</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-108] Command argument to pipe is now Seq[String]. <a href="https://github.com/bigdatagenomics/cannoli/pull/109">#109</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-98] Adding container builder. <a href="https://github.com/bigdatagenomics/cannoli/pull/107">#107</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Allow Singularity to run containers <a href="https://github.com/bigdatagenomics/cannoli/pull/106">#106</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>[CANNOLI-95] Bump ADAM dependency version to 0.24.0-SNAPSHOT <a href="https://github.com/bigdatagenomics/cannoli/pull/102">#102</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-94] Dropping support for Scala 2.10 and Spark 1.x. <a href="https://github.com/bigdatagenomics/cannoli/pull/101">#101</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-94][CANNOLI-95] Drop support for Scala 2.10 and Spark 1.x. <a href="https://github.com/bigdatagenomics/cannoli/pull/100">#100</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-43] Use accumulator for VCF header lines. <a href="https://github.com/bigdatagenomics/cannoli/pull/72">#72</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-104] Provide functions for use in cannoli-shell or notebooks. <a href="https://github.com/bigdatagenomics/cannoli/pull/69">#69</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Add CannoliCommand and CannoliAlignerCommand. <a href="https://github.com/bigdatagenomics/cannoli/pull/54">#54</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[CANNOLI-29] Add minimal GMAP and GSNAP wrappers. <a href="https://github.com/bigdatagenomics/cannoli/pull/32">#32</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.23.0 Released (+ Avocado and DECA releases)]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2018/01/04/adam-0-dot-23-dot-0-released-plus-avocado-cannoli-and-deca-releases/"/>
    <updated>2018-01-04T09:47:53-08:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2018/01/04/adam-0-dot-23-dot-0-released-plus-avocado-cannoli-and-deca-releases</id>
    <content type="html"><![CDATA[<p>We are excited to announce the availability of the ADAM 0.23.0 release, along
with releases of Avocado germline variant caller (release 0.1.0) and the DECA
copy number variant caller (release 0.2.0). These releases contain an extensive
number of feature additions, performance improvements, and bug patches, with
over 375 issues closed and pull requests merged or closed since the last ADAM
release.</p>

<p>Some of the highlights include:</p>

<ul>
<li>A validated, high-performance end-to-end alignment/variant calling pipeline
using ADAM, Cannoli, and Avocado.</li>
<li>Support for manipulating data using Spark SQL.</li>
<li>R and Python APIs for ADAM, including the ability to get a working deployment
of ADAM simply by running <code>pip install bdgenomics.adam</code>.</li>
</ul>


<p>With this release, we have also moved our documentation to Read The Docs:</p>

<ul>
<li><a href="http://adam.readthedocs.io/en/latest/">Read the Docs for ADAM</a></li>
<li><a href="http://bdg-avocado.readthedocs.io/en/latest/">Read the Docs for Avocado</a></li>
<li><a href="http://bdg-deca.readthedocs.io/en/latest/">Read the Docs for DECA</a></li>
</ul>


<p>This documentation describes how to deploy our tools on a variety of platforms,
including a local cluster, cloud computing, and through the
<a href="https://github.com/bd2kgenomics/toil">Toil</a> workflow manager. We already have
a <code>pip</code> installable Toil workflow for calling copy number variants with DECA,
which is packaged as part of the
<a href="http://bdg-workflows.readthedocs.io/en/latest/">bdgenomics.workflows</a> library.</p>

<p>This release is the last release of ADAM that supports Spark 1.x and Scala 2.10.
The upcoming release of ADAM will only support Spark 2.x and Scala 2.11. Avocado
and DECA have already dropped support for Spark 1.x.</p>

<p>Over the upcoming few weeks, we are working on a release of
<a href="https://github.com/bigdatagenomics/cannoli">Cannoli</a>, as well as Toil workflows
for running the ADAM/Avocado/Cannoli variant calling pipeline, and a preprint
describing the pipeline in more depth. We also are working on a release of the
<a href="https://github.com/bigdatagenomics/mango">Mango</a> visualization tool, which uses
ADAM as a backend for interactively visualizing large genomics datasets. Stay
tuned for more info!</p>

<h1>Variant Calling with Cannoli, ADAM, Avocado, and DECA</h1>

<p>With the collection of tools we have released, you can run highly rapid and
accurate variant calling entirely in Apache Spark. While we have introduced
Avocado and DECA earlier in this post, we haven&rsquo;t talked about Cannoli yet.
Cannoli&mdash;-Italian for &ldquo;a little pipe&rdquo;&mdash;-uses ADAM&rsquo;s <a href="http://adam.readthedocs.io/en/adam-parent_2.11-0.23.0/api/pipes/">pipe API</a>
to parallelize commonly used genomics tools. Currently, Cannoli supports
aligning reads with Bowtie, Bowtie2, and BWA; calling variants with FreeBayes;
and annotating variant effects with SnpEff. We are working on support for many
more tools, as you can see in our <a href="https://github.com/bigdatagenomics/cannoli/issues">issue tracker</a>.
Please let us know if you are interested in any specific tool&mdash;-or even
better&mdash;-in helping us add support for a specific tool. ADAM&rsquo;s pipe API makes
it extremely easy to parallelize an existing single node genomic analysis tool,
and most tools can be implemented on top of the pipe API in less than 10 lines
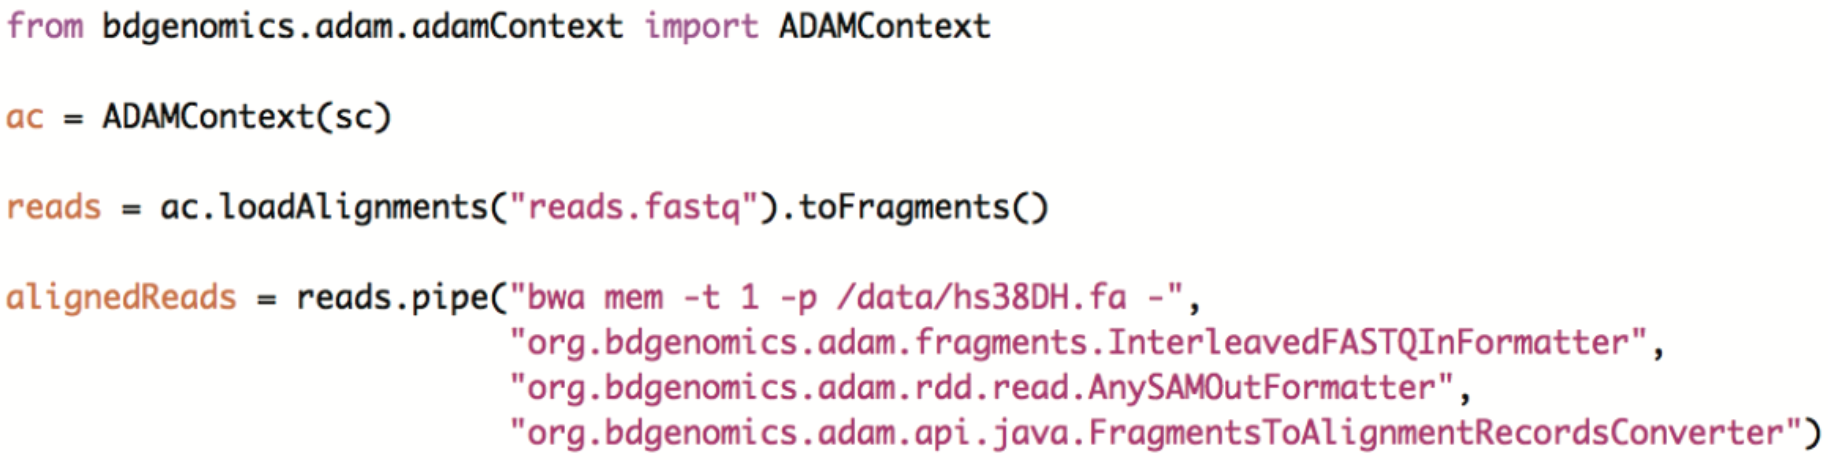
of code. For example, here&rsquo;s how you could launch BWA using ADAM&rsquo;s Pipe API in
Python:</p>

<p><img class="center" src="http://bigdatagenomics.github.io/images/pipe.png" width="750"></p>

<p>By using Cannoli, we can accelerate alignment with BWA to take approximately
10&mdash;15 minutes when running on a 1,024 core cluster.</p>

<p>We can couple this rapid alignment pipeline with the fast preprocessing stages in
ADAM and the variant calling stages in Avocado to call variants on a 60x coverage WGS
dataset in approximately 45 minutes on a 1,024 core cluster. Avocado can be used to
call variants on a single sample, or to jointly call variants using a <a href="http://bdg-avocado.readthedocs.io/en/latest/workflows/joint.html">gVCF-based
workflow</a>. When
running on 1,024 cores, we were able to jointly genotype more than 10TB of gVCFs
within approximately 6 hours. Avocado has >99% accuracy when genotyping SNPs,
and >96% accuracy when genotyping INDELs. Detailed benchmarking results can be
found in <a href="https://www2.eecs.berkeley.edu/Pubs/TechRpts/2017/EECS-2017-204.pdf">Chapter 8 of this thesis</a>.
Avocado is two times faster than the GATK4&rsquo;s Spark-based implementation of the
HaplotypeCaller, although it is worth pointing out that this is an unfair
comparison, as the HaplotypeCaller performs local reassembly, while Avocado does
not.</p>

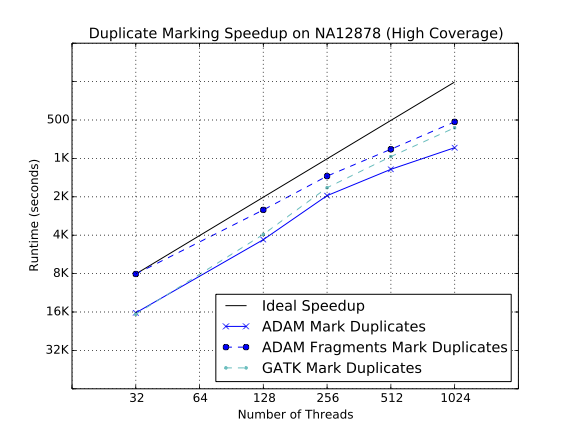
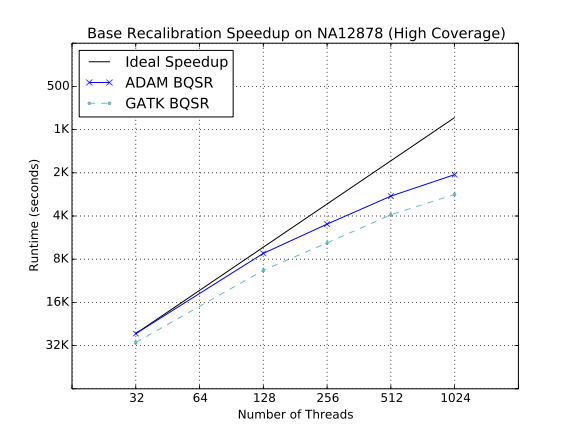
<p>One interesting comparison is between the duplicate marking and BQSR tools in
ADAM and in the GATK4. In both cases, ADAM&rsquo;s implementation is faster than the
GATK4&rsquo;s equivalent implementation.</p>

<p><img class="center" src="http://bigdatagenomics.github.io/images/speedup-md.png"></p>

<p><img class="center" src="http://bigdatagenomics.github.io/images/speedup-bqsr.png"></p>

<p>We have work-in-progress towards a Spark SQL-based implementation of duplicate
marking, which will provide an additional >20% performance improvement. We hope to
introduce this new duplicate marker in the 0.24.0 release of ADAM.</p>

<h1>Manipulating Data using Spark SQL</h1>

<p>Since Apache Spark 1.6, there has been a major push in the Spark project to
rearchitect Spark around the Catalyst query optimizer and the Tungsten code
execution engine. These two engines are hidden behind Spark SQL&rsquo;s DataFrame
and Dataset APIs, which provide a SQL-like interface for manipulating data
using Spark. Unlike Spark&rsquo;s Resilient Distributed Dataset (RDD) API, the
DataFrame API allows the Catalyst query optimizer to examine the function that
the user is running. Catalyst can then rewrite the query so that it runs in a
more efficient manner, and can implement the query using the Tungsten engine
with performance that approaches native performance. This can provide
order-of-magnitude performance improvements for some queries, and it also
provides users with uniform query performance across Scala, Java, SQL, Python,
and R.</p>

<p>Although Spark SQL was introduced in 2015, we were not able to take advantage
of Spark SQL in ADAM until recently. While ADAM has always described genomics
data using a set of schemas, the library we used to represent these schemas
(<a href="https://avro.apache.org">Apache Avro</a>) was not compatible with Spark SQL. To
resolve this, we updated our core <a href="http://adam.readthedocs.io/en/adam-parent_2.11-0.23.0/api/genomicRdd/"><code>GenomicRDD</code> interfaces</a>
to transparently convert between Spark&rsquo;s RDD and DataFrame/Dataset APIs. We
describe the architecture we use for converting between these two representations
<a href="http://adam.readthedocs.io/en/adam-parent_2.11-0.23.0/api/genomicRdd/#transforming-genomicrdds-via-spark-sql">here</a>.
With the Spark SQL query interfaces built into <code>GenomicRDD</code>s, you can begin
running SQL queries on genomic data in fewer than 5 lines of code:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
<span class='line-number'>9</span>
<span class='line-number'>10</span>
<span class='line-number'>11</span>
<span class='line-number'>12</span>
<span class='line-number'>13</span>
<span class='line-number'>14</span>
<span class='line-number'>15</span>
<span class='line-number'>16</span>
<span class='line-number'>17</span>
<span class='line-number'>18</span>
<span class='line-number'>19</span>
<span class='line-number'>20</span>
<span class='line-number'>21</span>
<span class='line-number'>22</span>
<span class='line-number'>23</span>
<span class='line-number'>24</span>
<span class='line-number'>25</span>
<span class='line-number'>26</span>
<span class='line-number'>27</span>
<span class='line-number'>28</span>
<span class='line-number'>29</span>
<span class='line-number'>30</span>
<span class='line-number'>31</span>
<span class='line-number'>32</span>
<span class='line-number'>33</span>
<span class='line-number'>34</span>
<span class='line-number'>35</span>
<span class='line-number'>36</span>
<span class='line-number'>37</span>
<span class='line-number'>38</span>
<span class='line-number'>39</span>
<span class='line-number'>40</span>
<span class='line-number'>41</span>
<span class='line-number'>42</span>
</pre></td><td class='code'><pre><code class=''><span class='line'>$ adam-shell 
</span><span class='line'>
</span><span class='line'>Welcome to
</span><span class='line'>      ____              __
</span><span class='line'>     / __/__  ___ _____/ /__
</span><span class='line'>    _\ \/ _ \/ _ `/ __/  '_/
</span><span class='line'>   /___/ .__/\_,_/_/ /_/\_\   version 2.2.1
</span><span class='line'>      /_/
</span><span class='line'>         
</span><span class='line'>Using Scala version 2.11.8 (Java HotSpot(TM) 64-Bit Server VM, Java 1.8.0_152)
</span><span class='line'>
</span><span class='line'>scala> import org.bdgenomics.adam.rdd.ADAMContext._
</span><span class='line'>import org.bdgenomics.adam.rdd.ADAMContext._
</span><span class='line'>
</span><span class='line'>scala> val reads = sc.loadAlignments("adam-core/src/test/resources/small.sam")
</span><span class='line'>reads: org.bdgenomics.adam.rdd.read.AlignmentRecordRDD = RDDBoundAlignmentRecordRDD with 2 reference sequences, 0 read groups, and 2 processing steps
</span><span class='line'>
</span><span class='line'>scala> reads.transformDataset(_.filter("readMapped=true")).dataset.show
</span><span class='line'>+--------------+----------+---------+-----------+---------+----+--------------------+--------------------+----+-----+--------+---------------------+-------------------+----------+----------+----------+----------+-------------------------+-------------+------------------+------------------+----------------+------------------+----------------------+--------------------+--------+--------------------+---------------+-----------------+------------------+--------------+------------------+
</span><span class='line'>|readInFragment|contigName|    start|oldPosition|      end|mapq|            readName|            sequence|qual|cigar|oldCigar|basesTrimmedFromStart|basesTrimmedFromEnd|readPaired|properPair|readMapped|mateMapped|failedVendorQualityChecks|duplicateRead|readNegativeStrand|mateNegativeStrand|primaryAlignment|secondaryAlignment|supplementaryAlignment|mismatchingPositions|origQual|          attributes|recordGroupName|recordGroupSample|mateAlignmentStart|mateContigName|inferredInsertSize|
</span><span class='line'>+--------------+----------+---------+-----------+---------+----+--------------------+--------------------+----+-----+--------+---------------------+-------------------+----------+----------+----------+----------+-------------------------+-------------+------------------+------------------+----------------+------------------+----------------------+--------------------+--------+--------------------+---------------+-----------------+------------------+--------------+------------------+
</span><span class='line'>|             0|         1| 26472783|       null| 26472858|  60|simread:1:2647278...|GTATAAGAGCAGCCTTA...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|              true|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|240997787|       null|240997862|  60|simread:1:2409977...|CTTTATTTTTATTTTTA...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|             false|             false|            true|             false|                 false|                null|    null|XS:i:39    AS:i:75 N...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|189606653|       null|189606728|  60|simread:1:1896066...|TGTATCTTCCTCCCCTG...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|             false|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|207027738|       null|207027813|  60|simread:1:2070277...|TTTAATAAATGTTGATT...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|             false|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1| 14397233|       null| 14397308|  60|simread:1:1439723...|TAAAATGCCCCCATCTT...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|              true|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|240344442|       null|240344517|  24|simread:1:2403444...|TACAGGCACCCACCATC...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|             false|             false|            true|             false|                 false|                null|    null|XS:i:61    AS:i:75 N...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|153978724|       null|153978799|  60|simread:1:1539787...|GCTCACTGCAGCCTCAA...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|              true|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|237728409|       null|237728484|  28|simread:1:2377284...|TTTCTTTTTCTTTCTTT...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|             false|             false|            true|             false|                 false|                null|    null|XS:i:59    AS:i:75 N...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|231911906|       null|231911981|  60|simread:1:2319119...|TCATGTAGCATGCATAT...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|              true|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1| 50683371|       null| 50683446|  60|simread:1:5068337...|GCTCAGGCCTTGCAAGA...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|              true|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1| 37577445|       null| 37577520|  60|simread:1:3757744...|CCTAGAGAAGCTCCCAC...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|              true|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|195211965|       null|195212040|  60|simread:1:1952119...|AAATAAAGTTTGGCTTT...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|              true|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|163841413|       null|163841488|  60|simread:1:1638414...|TGTGTAACTAACATAAT...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|              true|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|101556378|       null|101556453|  60|simread:1:1015563...|TTTATTTTTTGAGCATG...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|              true|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1| 20101800|       null| 20101875|  35|simread:1:2010180...|CTCAGGTGATCCACCCG...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|             false|             false|            true|             false|                 false|                null|    null|XS:i:55    AS:i:75 N...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|186794283|       null|186794358|  60|simread:1:1867942...|GACAAGATAGTACTTGA...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|             false|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|165341382|       null|165341457|  60|simread:1:1653413...|CTACTCTCATTGACTGT...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|             false|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|  5469106|       null|  5469181|  60|simread:1:5469106...|CTCATTCTCTCTCCTGC...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|             false|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1| 89554252|       null| 89554327|  60|simread:1:8955425...|AAATTAAACAGCTCGTT...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|              true|             false|            true|             false|                 false|                null|    null|XS:i:0 AS:i:75 NM...|           null|             null|              null|          null|              null|
</span><span class='line'>|             0|         1|169801933|       null|169802008|  40|simread:1:1698019...|AGACTGGGTCTCACTAT...|null|  75M|    null|                    0|                  0|     false|     false|      true|     false|                    false|        false|             false|             false|            true|             false|                 false|                null|    null|XS:i:52    AS:i:75 N...|           null|             null|              null|          null|              null|
</span><span class='line'>+--------------+----------+---------+-----------+---------+----+--------------------+--------------------+----+-----+--------+---------------------+-------------------+----------+----------+----------+----------+-------------------------+-------------+------------------+------------------+----------------+------------------+----------------------+--------------------+--------+--------------------+---------------+-----------------+------------------+--------------+------------------+</span></code></pre></td></tr></table></div></figure>


<p>While Spark SQL has specific optimizations for loading data from Apache Parquet
files, ADAM can be used to run Spark SQL queries against data stored in most
common genomics file formats, including SAM/BAM/CRAM, FASTQ, VCF/BCF, BED,
GTF/GFF3, IntervalList, NarrowPeak, FASTA and more.</p>

<h1>Using ADAM through Python and R</h1>

<p>As mentioned above, one of the major advantages of Spark SQL is that it provides
uniform query performance across Scala, Java, Python, and R. While ADAM is
mostly written in Scala, we have maintained Java APIs for a long time. However,
we have previously been unable to support Python or R APIs. Adding support
for Spark SQL eliminated the major issues that prevented us from adding Python
and R APIs. This release of ADAM introduces the <code>bdgenomics.adam</code> packages for
Python and R. Our Python API can be installed using <code>pip install
bdgenomics.adam</code>, and our R API is available from
<a href="https://github.com/bigdatagenomics/adam/releases/download/adam-parent-spark2_2.11-0.23.0/bdgenomics.adam_0.23.0.tar.gz">GitHub</a>.
We hope to make our R API available through CRAN in the 0.24.0 release of ADAM;
we are blocked on an issue upstream in Apache Spark and are tracking progress on
this issue at <a href="https://github.com/bigdatagenomics/adam/issues/1851">ADAM-1851</a>.</p>

<p>In addition to installing the <code>bdgenomics.adam</code> libraries, running <code>pip install
bdgenomics.adam</code> installs all of the ADAM command line tools:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
<span class='line-number'>9</span>
<span class='line-number'>10</span>
<span class='line-number'>11</span>
<span class='line-number'>12</span>
<span class='line-number'>13</span>
<span class='line-number'>14</span>
<span class='line-number'>15</span>
<span class='line-number'>16</span>
<span class='line-number'>17</span>
<span class='line-number'>18</span>
<span class='line-number'>19</span>
<span class='line-number'>20</span>
<span class='line-number'>21</span>
<span class='line-number'>22</span>
<span class='line-number'>23</span>
<span class='line-number'>24</span>
<span class='line-number'>25</span>
<span class='line-number'>26</span>
<span class='line-number'>27</span>
<span class='line-number'>28</span>
<span class='line-number'>29</span>
<span class='line-number'>30</span>
<span class='line-number'>31</span>
<span class='line-number'>32</span>
<span class='line-number'>33</span>
<span class='line-number'>34</span>
<span class='line-number'>35</span>
<span class='line-number'>36</span>
<span class='line-number'>37</span>
<span class='line-number'>38</span>
<span class='line-number'>39</span>
<span class='line-number'>40</span>
<span class='line-number'>41</span>
<span class='line-number'>42</span>
<span class='line-number'>43</span>
<span class='line-number'>44</span>
<span class='line-number'>45</span>
<span class='line-number'>46</span>
<span class='line-number'>47</span>
<span class='line-number'>48</span>
<span class='line-number'>49</span>
<span class='line-number'>50</span>
<span class='line-number'>51</span>
<span class='line-number'>52</span>
<span class='line-number'>53</span>
<span class='line-number'>54</span>
</pre></td><td class='code'><pre><code class=''><span class='line'>$ pip install bdgenomics.adam
</span><span class='line'>...
</span><span class='line'>Successfully installed bdgenomics.adam-0.23.0 py4j-0.10.4 pyspark-2.2.1
</span><span class='line'>
</span><span class='line'>$ adam-submit
</span><span class='line'>
</span><span class='line'>       e        888~-_         e            e    e
</span><span class='line'>      d8b       888   \       d8b          d8b  d8b
</span><span class='line'>     /Y88b      888    |     /Y88b        d888bdY88b
</span><span class='line'>    /  Y88b     888    |    /  Y88b      / Y88Y Y888b
</span><span class='line'>   /____Y88b    888   /    /____Y88b    /   YY   Y888b
</span><span class='line'>  /      Y88b   888_-~    /      Y88b  /          Y888b
</span><span class='line'>
</span><span class='line'>Usage: adam-submit [&lt;spark-args> --] &lt;adam-args>
</span><span class='line'>
</span><span class='line'>Choose one of the following commands:
</span><span class='line'>
</span><span class='line'>ADAM ACTIONS
</span><span class='line'>          countKmers : Counts the k-mers/q-mers from a read dataset.
</span><span class='line'>    countContigKmers : Counts the k-mers/q-mers from a read dataset.
</span><span class='line'> transformAlignments : Convert SAM/BAM to ADAM format and optionally perform read pre-processing transformations
</span><span class='line'>   transformFeatures : Convert a file with sequence features into corresponding ADAM format and vice versa
</span><span class='line'>  transformGenotypes : Convert a file with genotypes into corresponding ADAM format and vice versa
</span><span class='line'>   transformVariants : Convert a file with variants into corresponding ADAM format and vice versa
</span><span class='line'>         mergeShards : Merges the shards of a file
</span><span class='line'>      reads2coverage : Calculate the coverage from a given ADAM file
</span><span class='line'>
</span><span class='line'>CONVERSION OPERATIONS
</span><span class='line'>          fasta2adam : Converts a text FASTA sequence file into an ADAMNucleotideContig Parquet file which represents assembled sequences.
</span><span class='line'>          adam2fasta : Convert ADAM nucleotide contig fragments to FASTA files
</span><span class='line'>          adam2fastq : Convert BAM to FASTQ files
</span><span class='line'>  transformFragments : Convert alignment records into fragment records.
</span><span class='line'>
</span><span class='line'>PRINT
</span><span class='line'>               print : Print an ADAM formatted file
</span><span class='line'>            flagstat : Print statistics on reads in an ADAM file (similar to samtools flagstat)
</span><span class='line'>                view : View certain reads from an alignment-record file.
</span><span class='line'>
</span><span class='line'>$ adam-shell 
</span><span class='line'>
</span><span class='line'>Welcome to
</span><span class='line'>      ____              __
</span><span class='line'>     / __/__  ___ _____/ /__
</span><span class='line'>    _\ \/ _ \/ _ `/ __/  '_/
</span><span class='line'>   /___/ .__/\_,_/_/ /_/\_\   version 2.2.1
</span><span class='line'>      /_/
</span><span class='line'>         
</span><span class='line'>Using Scala version 2.11.8 (Java HotSpot(TM) 64-Bit Server VM, Java 1.8.0_152)
</span><span class='line'>
</span><span class='line'>scala> import org.bdgenomics.adam.rdd.ADAMContext._
</span><span class='line'>import org.bdgenomics.adam.rdd.ADAMContext._
</span><span class='line'>
</span><span class='line'>scala> :quit</span></code></pre></td></tr></table></div></figure>


<p>Most of the major APIs in ADAM can be used through our Python and R bindings,
with the exception of the region join API. We plan to enable the use of the
region join API in Python and R in the 0.24.0 release of ADAM, along with other
API compatibility improvements.</p>

<h1>Changes since Previous Release</h1>

<p>The full list of changes since version 0.22.0 is below.</p>

<!-- more -->


<p><strong>Closed issues:</strong></p>

<ul>
<li>Readthedocs build error <a href="https://github.com/bigdatagenomics/adam/issues/1854">#1854</a></li>
<li>Add pip release to release scripts <a href="https://github.com/bigdatagenomics/adam/issues/1847">#1847</a></li>
<li>Publish scaladoc script still attempts to build markdown docs <a href="https://github.com/bigdatagenomics/adam/issues/1845">#1845</a></li>
<li>Allow variant annotations to be loaded into genotypes <a href="https://github.com/bigdatagenomics/adam/issues/1838">#1838</a></li>
<li>Specify correct extensions for SAM/BAM output <a href="https://github.com/bigdatagenomics/adam/issues/1834">#1834</a></li>
<li>Fix link anchors and other issues in readthedocs <a href="https://github.com/bigdatagenomics/adam/issues/1822">#1822</a></li>
<li>Sphinx fulltoc is not included <a href="https://github.com/bigdatagenomics/adam/issues/1821">#1821</a></li>
<li>Readme link to bigdatagenomics/lime 404s <a href="https://github.com/bigdatagenomics/adam/issues/1819">#1819</a></li>
<li>Bump to Hadoop-BAM 7.9.1 <a href="https://github.com/bigdatagenomics/adam/issues/1817">#1817</a></li>
<li>LoadVariants Header Format <a href="https://github.com/bigdatagenomics/adam/issues/1815">#1815</a></li>
<li>Right and Left Outer Shuffle Region Join don&rsquo;t match <a href="https://github.com/bigdatagenomics/adam/issues/1813">#1813</a></li>
<li>Pipe command can fail with empty partitions <a href="https://github.com/bigdatagenomics/adam/issues/1807">#1807</a></li>
<li>adam files with outdated formats throw FileNotFoundException <a href="https://github.com/bigdatagenomics/adam/issues/1804">#1804</a></li>
<li>Move GenomicRDD.writeTextRDD outside of GenomicRDD <a href="https://github.com/bigdatagenomics/adam/issues/1803">#1803</a></li>
<li>find-adam-assembly fails to recognize more than 1 jar <a href="https://github.com/bigdatagenomics/adam/issues/1801">#1801</a></li>
<li>tests/testthat.R failed on git head <a href="https://github.com/bigdatagenomics/adam/issues/1799">#1799</a></li>
<li>Run python and R tests conditionally in build <a href="https://github.com/bigdatagenomics/adam/issues/1795">#1795</a></li>
<li>scala-lang should be a provided dependency <a href="https://github.com/bigdatagenomics/adam/issues/1789">#1789</a></li>
<li>loadIndexedBam does an unnecessary union <a href="https://github.com/bigdatagenomics/adam/issues/1784">#1784</a></li>
<li>Release bdgenomics.adam R package on CRAN <a href="https://github.com/bigdatagenomics/adam/issues/1783">#1783</a></li>
<li>Issue with transformVariant // Adam to vcf <a href="https://github.com/bigdatagenomics/adam/issues/1782">#1782</a></li>
<li>Add code of conduct <a href="https://github.com/bigdatagenomics/adam/issues/1779">#1779</a></li>
<li>Reinstantiation of SQLContext in pyadam ADAMContext <a href="https://github.com/bigdatagenomics/adam/issues/1774">#1774</a></li>
<li>Genotypes should only contain the core variant fields <a href="https://github.com/bigdatagenomics/adam/issues/1770">#1770</a></li>
<li>Add SingleFASTQInFormatter <a href="https://github.com/bigdatagenomics/adam/issues/1768">#1768</a></li>
<li>INDEL realigner can emit negative partition IDs <a href="https://github.com/bigdatagenomics/adam/issues/1763">#1763</a></li>
<li>Request for a new release <a href="https://github.com/bigdatagenomics/adam/issues/1762">#1762</a></li>
<li>INDEL realigner generates targets for reads with more than 1 INDEL <a href="https://github.com/bigdatagenomics/adam/issues/1753">#1753</a></li>
<li>Fragment Issue <a href="https://github.com/bigdatagenomics/adam/issues/1752">#1752</a></li>
<li>Variant Caller!!! <a href="https://github.com/bigdatagenomics/adam/issues/1751">#1751</a></li>
<li>Spark Version!! <a href="https://github.com/bigdatagenomics/adam/issues/1750">#1750</a></li>
<li>ReferenceRegion.subtract eliminating valid regions <a href="https://github.com/bigdatagenomics/adam/issues/1747">#1747</a></li>
<li>New Shuffle Join Implementation &ndash; Left Outer + Group By Left <a href="https://github.com/bigdatagenomics/adam/issues/1745">#1745</a></li>
<li>command failure after build success <a href="https://github.com/bigdatagenomics/adam/issues/1744">#1744</a></li>
<li>Recalibrate_base_Qualities <a href="https://github.com/bigdatagenomics/adam/issues/1743">#1743</a></li>
<li>Standardize regionFn for ShuffleJoin returned objects <a href="https://github.com/bigdatagenomics/adam/issues/1740">#1740</a></li>
<li>Shuffle, Broadcast Joins with threshold <a href="https://github.com/bigdatagenomics/adam/issues/1739">#1739</a></li>
<li>Adam on Spark 2.1 <a href="https://github.com/bigdatagenomics/adam/issues/1738">#1738</a></li>
<li>Opening up permission on GenericGenomicRDD constructor <a href="https://github.com/bigdatagenomics/adam/issues/1735">#1735</a></li>
<li>Consistency on ShuffleRegionJoin returns <a href="https://github.com/bigdatagenomics/adam/issues/1734">#1734</a></li>
<li>vcf2adam support <a href="https://github.com/bigdatagenomics/adam/issues/1731">#1731</a></li>
<li>Cloud-scale BWA MEM <a href="https://github.com/bigdatagenomics/adam/issues/1730">#1730</a></li>
<li>Aligned Human Genome couldn&rsquo;t convert to Adam  <a href="https://github.com/bigdatagenomics/adam/issues/1729">#1729</a></li>
<li>Mark Duplicates <a href="https://github.com/bigdatagenomics/adam/issues/1726">#1726</a></li>
<li>Genomics Pipeline <a href="https://github.com/bigdatagenomics/adam/issues/1724">#1724</a></li>
<li>.fastq Alignment  <a href="https://github.com/bigdatagenomics/adam/issues/1723">#1723</a></li>
<li>Is it correct Adam file <a href="https://github.com/bigdatagenomics/adam/issues/1720">#1720</a></li>
<li>.fastQ to .adam <a href="https://github.com/bigdatagenomics/adam/issues/1718">#1718</a></li>
<li>Unable to create .adam from .sam <a href="https://github.com/bigdatagenomics/adam/issues/1717">#1717</a></li>
<li>Add adam- prefix to distribution module name <a href="https://github.com/bigdatagenomics/adam/issues/1716">#1716</a></li>
<li>Python load methods don&rsquo;t have ability to specify validation stringency <a href="https://github.com/bigdatagenomics/adam/issues/1715">#1715</a></li>
<li>NPE when trying to map <em>loadVariants</em> over RDD <a href="https://github.com/bigdatagenomics/adam/issues/1713">#1713</a></li>
<li>Add left normalization of INDELs as an RDD level primitive <a href="https://github.com/bigdatagenomics/adam/issues/1709">#1709</a></li>
<li>Allow validation stringency to be set in AnySAMOutFormatter <a href="https://github.com/bigdatagenomics/adam/issues/1703">#1703</a></li>
<li>InterleavedFastqInFormatter should sort by readInFragment <a href="https://github.com/bigdatagenomics/adam/issues/1702">#1702</a></li>
<li>Allow silencing the # of reads in fragment warning in InterleavedFastqInFormatter <a href="https://github.com/bigdatagenomics/adam/issues/1701">#1701</a></li>
<li>GenomicRDD.toXxx method names should be consistent <a href="https://github.com/bigdatagenomics/adam/issues/1699">#1699</a></li>
<li>Exception thrown in VariantContextConverter.formatAllelicDepth despite SILENT validation stringency <a href="https://github.com/bigdatagenomics/adam/issues/1695">#1695</a></li>
<li>Make GenomicRDD.toString more adam-shell friendly <a href="https://github.com/bigdatagenomics/adam/issues/1694">#1694</a></li>
<li>Add adam-shell friendly VariantContextRDD.saveAsVcf method <a href="https://github.com/bigdatagenomics/adam/issues/1693">#1693</a></li>
<li>change bdgenomics.adam package name for adam-python to bdg-adam <a href="https://github.com/bigdatagenomics/adam/issues/1691">#1691</a></li>
<li>Conflict in bdg-formats dependency version due to org.hammerlab:genomic-loci <a href="https://github.com/bigdatagenomics/adam/issues/1688">#1688</a></li>
<li>Convert and store variant quality field. <a href="https://github.com/bigdatagenomics/adam/issues/1682">#1682</a></li>
<li>Region join shows non-determinism <a href="https://github.com/bigdatagenomics/adam/issues/1680">#1680</a></li>
<li>Shuffle region join throws multimapped exception for unmapped reads <a href="https://github.com/bigdatagenomics/adam/issues/1679">#1679</a></li>
<li>Push validation checks down to INFO/FORMAT fields <a href="https://github.com/bigdatagenomics/adam/issues/1676">#1676</a></li>
<li>IndexOutOfBounds thrown when saving gVCF with no likelihoods <a href="https://github.com/bigdatagenomics/adam/issues/1673">#1673</a></li>
<li>Generate docs from R API for distribution <a href="https://github.com/bigdatagenomics/adam/issues/1672">#1672</a></li>
<li>Support loading a subset of VCF fields <a href="https://github.com/bigdatagenomics/adam/issues/1670">#1670</a></li>
<li>Error with metadata: Multivalued flags are not supported for INFO lines <a href="https://github.com/bigdatagenomics/adam/issues/1669">#1669</a></li>
<li>Include bdg.adam-0.23.0.tar.gz in distribution tarballs <a href="https://github.com/bigdatagenomics/adam/issues/1668">#1668</a></li>
<li>Include bdgenomics.adam-0.23.0_SNAPSHOT-py2.7.egg in distribution tarball <a href="https://github.com/bigdatagenomics/adam/issues/1667">#1667</a></li>
<li>Add SUPPORT.md file to complement CONTRIBUTING.md <a href="https://github.com/bigdatagenomics/adam/issues/1664">#1664</a></li>
<li>Can&rsquo;t merge BAM files containing the same sample <a href="https://github.com/bigdatagenomics/adam/issues/1663">#1663</a></li>
<li>Incorrect README.md  kmer.scala loadAliments method parameter name <a href="https://github.com/bigdatagenomics/adam/issues/1662">#1662</a></li>
<li>Add performance benchmarks similar to Samtools CRAM benchmarking page <a href="https://github.com/bigdatagenomics/adam/issues/1661">#1661</a></li>
<li>Transient bad GZIP header bug when loading BGZF FASTQ <a href="https://github.com/bigdatagenomics/adam/issues/1658">#1658</a></li>
<li>bdgenomics.adam vs bdg.adam for R/Python APIs <a href="https://github.com/bigdatagenomics/adam/issues/1655">#1655</a></li>
<li>Need adamR script <a href="https://github.com/bigdatagenomics/adam/issues/1649">#1649</a></li>
<li>incorrect grep for assembly jars in bin/pyadam <a href="https://github.com/bigdatagenomics/adam/issues/1647">#1647</a></li>
<li>VariantRDD union creates multiple records for the same SNP ID <a href="https://github.com/bigdatagenomics/adam/issues/1644">#1644</a></li>
<li>S3 access documentation <a href="https://github.com/bigdatagenomics/adam/issues/1643">#1643</a></li>
<li>Algorithms docs formatting <a href="https://github.com/bigdatagenomics/adam/issues/1639">#1639</a></li>
<li>Building downstream apps docs reformatting <a href="https://github.com/bigdatagenomics/adam/issues/1638">#1638</a></li>
<li>FastqInputFormat.FILE_SPLITTABLE in conf not getting passed properly <a href="https://github.com/bigdatagenomics/adam/issues/1635">#1635</a></li>
<li>Add benchmarks to documentation <a href="https://github.com/bigdatagenomics/adam/issues/1634">#1634</a></li>
<li>Intro docs contain outdated/incompatible code <a href="https://github.com/bigdatagenomics/adam/issues/1633">#1633</a></li>
<li>Intro docs missing a number of active projects <a href="https://github.com/bigdatagenomics/adam/issues/1632">#1632</a></li>
<li>Installation instructions for Homebrew missing from documentation <a href="https://github.com/bigdatagenomics/adam/issues/1631">#1631</a></li>
<li>Architecture section is missing from docs <a href="https://github.com/bigdatagenomics/adam/issues/1630">#1630</a></li>
<li>Seq<VCFCompoundHeaderLine> vs. Seq<VCFHeaderLine> with javac <a href="https://github.com/bigdatagenomics/adam/issues/1625">#1625</a></li>
<li>ProcessingStep missing from adam-codegen <a href="https://github.com/bigdatagenomics/adam/issues/1623">#1623</a></li>
<li>Add ADAM recipe to bioconda <a href="https://github.com/bigdatagenomics/adam/issues/1618">#1618</a></li>
<li>adam-submit cannot find assembly jar if installed as symlink <a href="https://github.com/bigdatagenomics/adam/issues/1616">#1616</a></li>
<li>Expose transform/transmute in Java/Python/R <a href="https://github.com/bigdatagenomics/adam/issues/1615">#1615</a></li>
<li>Expose VariantContextRDD in R/Python <a href="https://github.com/bigdatagenomics/adam/issues/1614">#1614</a></li>
<li>Expose pipe API from Python/R <a href="https://github.com/bigdatagenomics/adam/issues/1611">#1611</a></li>
<li>Serialization issue with TwoBitFile <a href="https://github.com/bigdatagenomics/adam/issues/1610">#1610</a></li>
<li>Snapshot Distribution Does not include jar files <a href="https://github.com/bigdatagenomics/adam/issues/1607">#1607</a></li>
<li>ManualRegionPartitioner is broken for ParallelFileMerger codepath <a href="https://github.com/bigdatagenomics/adam/issues/1602">#1602</a></li>
<li>VariantRDD doesn&rsquo;t save partition map <a href="https://github.com/bigdatagenomics/adam/issues/1601">#1601</a></li>
<li>Scala copy method not supported in abstract classes such as AlignmentRecordRDD <a href="https://github.com/bigdatagenomics/adam/issues/1599">#1599</a></li>
<li>Interleaved FASTQ recognizes only /1 suffix pattern <a href="https://github.com/bigdatagenomics/adam/issues/1589">#1589</a></li>
<li>Use empty sequence dictionary when loading features <a href="https://github.com/bigdatagenomics/adam/issues/1588">#1588</a></li>
<li>New Illumina FASTQ spec adds metadata to read name line <a href="https://github.com/bigdatagenomics/adam/issues/1585">#1585</a></li>
<li>first run of ADAM <a href="https://github.com/bigdatagenomics/adam/issues/1582">#1582</a></li>
<li>Add unit test coverage for BED12 parser and writer <a href="https://github.com/bigdatagenomics/adam/issues/1579">#1579</a></li>
<li>Spark 1.x Scala 2.10 snapshot artifacts missing since 31 March 2017 <a href="https://github.com/bigdatagenomics/adam/issues/1578">#1578</a></li>
<li>Unable to save GenomicRDDs after a join. <a href="https://github.com/bigdatagenomics/adam/issues/1576">#1576</a></li>
<li>Add filterBySequenceDictionary to GenomicRDD <a href="https://github.com/bigdatagenomics/adam/issues/1575">#1575</a></li>
<li>Unaligned Trait does nothing <a href="https://github.com/bigdatagenomics/adam/issues/1573">#1573</a></li>
<li>Bump to bdg-formats 0.11.1 <a href="https://github.com/bigdatagenomics/adam/issues/1570">#1570</a></li>
<li>PhredUtils conversion to log probabilities has insufficient resolution for PLs <a href="https://github.com/bigdatagenomics/adam/issues/1569">#1569</a></li>
<li>Reference model import code is borked <a href="https://github.com/bigdatagenomics/adam/issues/1568">#1568</a></li>
<li>SequenceDictionary vs Feature[RDD] of reference length features <a href="https://github.com/bigdatagenomics/adam/issues/1567">#1567</a></li>
<li>giab-NA12878 truth_small_variants.vcf.gz header issues <a href="https://github.com/bigdatagenomics/adam/issues/1566">#1566</a></li>
<li>VCF header read from stream ignored in VCFOutFormatter <a href="https://github.com/bigdatagenomics/adam/issues/1564">#1564</a></li>
<li>VCF genotype Number=A attribute throws ArrayIndexOutOfBoundsException <a href="https://github.com/bigdatagenomics/adam/issues/1562">#1562</a></li>
<li>Save compressed single file VCF via HadoopBAM <a href="https://github.com/bigdatagenomics/adam/issues/1554">#1554</a></li>
<li>bucketing strategy <a href="https://github.com/bigdatagenomics/adam/issues/1553">#1553</a></li>
<li>Is parquet using delta encoding for positions? <a href="https://github.com/bigdatagenomics/adam/issues/1552">#1552</a></li>
<li>Export to VCF does not include symbolic non-ref if site has a called alt <a href="https://github.com/bigdatagenomics/adam/issues/1551">#1551</a></li>
<li>Refactor filterByOverlappingRegions not to require a List <a href="https://github.com/bigdatagenomics/adam/issues/1549">#1549</a></li>
<li>Move docs to Sphinx/pure Markdown <a href="https://github.com/bigdatagenomics/adam/issues/1548">#1548</a></li>
<li>java.lang.IncompatibleClassChangeError: Implementing class <a href="https://github.com/bigdatagenomics/adam/issues/1544">#1544</a></li>
<li>Support locus predicate in <code>TransformAlignments</code> <a href="https://github.com/bigdatagenomics/adam/issues/1539">#1539</a></li>
<li>Visibility from Java, jrdd has private access in AvroGenomicRDD <a href="https://github.com/bigdatagenomics/adam/issues/1538">#1538</a></li>
<li>Rename o.b.adam.apis.java package to o.b.adam.api.java <a href="https://github.com/bigdatagenomics/adam/issues/1537">#1537</a></li>
<li>VCF header genotype reserved key FT cardinality clobbered by htsjdk <a href="https://github.com/bigdatagenomics/adam/issues/1535">#1535</a></li>
<li>Compute a SequenceDictionary from a *.genome file <a href="https://github.com/bigdatagenomics/adam/issues/1534">#1534</a></li>
<li>Queryname sorted check should check for queryname grouped as well <a href="https://github.com/bigdatagenomics/adam/issues/1530">#1530</a></li>
<li>Bump to bdg-formats 0.11.0 <a href="https://github.com/bigdatagenomics/adam/issues/1520">#1520</a></li>
<li>Move to Spark 2.2, Parquet 1.8.2 <a href="https://github.com/bigdatagenomics/adam/issues/1517">#1517</a></li>
<li>Minor refactor for TreeRegionJoin for consistency <a href="https://github.com/bigdatagenomics/adam/issues/1514">#1514</a></li>
<li>Allow +Inf and -Inf Float values when reading VCF <a href="https://github.com/bigdatagenomics/adam/issues/1512">#1512</a></li>
<li>SparkFiles temp directory path should be accessible as a variable <a href="https://github.com/bigdatagenomics/adam/issues/1510">#1510</a></li>
<li>SparkFiles.get expects just the filename <a href="https://github.com/bigdatagenomics/adam/issues/1509">#1509</a></li>
<li>Split apart #1324 <a href="https://github.com/bigdatagenomics/adam/issues/1507">#1507</a></li>
<li>Where can I find &ldquo;Phred-scaled quality score&rdquo; (QUAL)? <a href="https://github.com/bigdatagenomics/adam/issues/1506">#1506</a></li>
<li>Alignment Record sort is not consistent with samtools <a href="https://github.com/bigdatagenomics/adam/issues/1504">#1504</a></li>
<li>Sequence dictionary records in TwoBitFile are not stable <a href="https://github.com/bigdatagenomics/adam/issues/1502">#1502</a></li>
<li>Move coverage counter over to Dataset API <a href="https://github.com/bigdatagenomics/adam/issues/1501">#1501</a></li>
<li>Allow users to set the minimum partition count across all load methods <a href="https://github.com/bigdatagenomics/adam/issues/1500">#1500</a></li>
<li>Enable reuse of broadcast object across broadcast region joins <a href="https://github.com/bigdatagenomics/adam/issues/1499">#1499</a></li>
<li>Take union across genomic RDDs <a href="https://github.com/bigdatagenomics/adam/issues/1497">#1497</a></li>
<li>Adam files created by vcf2adam is not recognizable <a href="https://github.com/bigdatagenomics/adam/issues/1496">#1496</a></li>
<li>Scalatest log output disappears with Maven 3.5.0 <a href="https://github.com/bigdatagenomics/adam/issues/1495">#1495</a></li>
<li>ArrayOutOfBoundsException in vcf2adam (spark2_2.11-0.22.0) on UK10K VCFs (VCFv4.1) <a href="https://github.com/bigdatagenomics/adam/issues/1494">#1494</a></li>
<li>ReferenceRegion overlaps and covers returns false if overlap is 1 <a href="https://github.com/bigdatagenomics/adam/issues/1492">#1492</a></li>
<li>Provide asSingleFile parameter for saveAsFastq and related <a href="https://github.com/bigdatagenomics/adam/issues/1490">#1490</a></li>
<li>Min Phred score gets bumped by 33 twice in BQSR <a href="https://github.com/bigdatagenomics/adam/issues/1488">#1488</a></li>
<li>Should throw error when BAM header load fails <a href="https://github.com/bigdatagenomics/adam/issues/1486">#1486</a></li>
<li>Default value for reads.toCoverage(collapse) should be false <a href="https://github.com/bigdatagenomics/adam/issues/1483">#1483</a></li>
<li>Refactor ADAMContext loadXxx methods for consistency <a href="https://github.com/bigdatagenomics/adam/issues/1481">#1481</a></li>
<li>loadGenotypes three time <a href="https://github.com/bigdatagenomics/adam/issues/1480">#1480</a></li>
<li>Fall back to sequential concat when HDFS concat fails <a href="https://github.com/bigdatagenomics/adam/issues/1478">#1478</a></li>
<li>VCF line with <code>.</code> ALT gets dropped <a href="https://github.com/bigdatagenomics/adam/issues/1476">#1476</a></li>
<li>ADAM works on Cloudera but does NOT work on MAPR <a href="https://github.com/bigdatagenomics/adam/issues/1475">#1475</a></li>
<li>Clean up ReferenceRegion.scala <a href="https://github.com/bigdatagenomics/adam/issues/1474">#1474</a></li>
<li>Allow joins on regions that are within a threshold (instead of requiring overlap) <a href="https://github.com/bigdatagenomics/adam/issues/1473">#1473</a></li>
<li>FeatureRDD.toCoverage throws NullPointerException when there is no coverage information <a href="https://github.com/bigdatagenomics/adam/issues/1471">#1471</a></li>
<li>Add quality score binner <a href="https://github.com/bigdatagenomics/adam/issues/1462">#1462</a></li>
<li>Splittable compression and FASTQ <a href="https://github.com/bigdatagenomics/adam/issues/1457">#1457</a></li>
<li>Don&rsquo;t convert .{different-type}.adam in loadAlignments and loadFragments <a href="https://github.com/bigdatagenomics/adam/issues/1456">#1456</a></li>
<li>New primitives for adam-core <a href="https://github.com/bigdatagenomics/adam/issues/1454">#1454</a></li>
<li>Port over code for populating SequenceDictionaries from .dict files <a href="https://github.com/bigdatagenomics/adam/issues/1449">#1449</a></li>
<li>Ignore failed push to Coveralls during CI builds <a href="https://github.com/bigdatagenomics/adam/issues/1444">#1444</a></li>
<li>No asSingleFile parameter for saveAsFasta in NucleotideContigFragmentRDD <a href="https://github.com/bigdatagenomics/adam/issues/1438">#1438</a></li>
<li>shufflejoin and ArrayIndexOutOfBoundsException <a href="https://github.com/bigdatagenomics/adam/issues/1436">#1436</a></li>
<li>Document using ADAM snapshot <a href="https://github.com/bigdatagenomics/adam/issues/1432">#1432</a></li>
<li>Improve metrics coverage across ADAMContext load methods <a href="https://github.com/bigdatagenomics/adam/issues/1428">#1428</a></li>
<li>loadReferenceFile missing from Java API <a href="https://github.com/bigdatagenomics/adam/issues/1421">#1421</a></li>
<li>loadCoverage missing from Java API <a href="https://github.com/bigdatagenomics/adam/issues/1420">#1420</a></li>
<li>Question: How to get paired-end alignemntRecord like RDD[AlignmentRecord, AlignmentRecordRDD]? <a href="https://github.com/bigdatagenomics/adam/issues/1419">#1419</a></li>
<li>Clean up possibly unused methods in Projection <a href="https://github.com/bigdatagenomics/adam/issues/1417">#1417</a></li>
<li>Problem loading SNPeff annotated VCF <a href="https://github.com/bigdatagenomics/adam/issues/1390">#1390</a></li>
<li>RecordGroupDictionary should support <code>isEmpty</code> <a href="https://github.com/bigdatagenomics/adam/issues/1380">#1380</a></li>
<li>Get rid of mutable collection transformations in ShuffleRegionJoin <a href="https://github.com/bigdatagenomics/adam/issues/1379">#1379</a></li>
<li>Add tab5/6 as native output format for AlignmentRecordRDD <a href="https://github.com/bigdatagenomics/adam/issues/1377">#1377</a></li>
<li>ValidationStringency in MDTagging should apply to reads on unknown references <a href="https://github.com/bigdatagenomics/adam/issues/1365">#1365</a></li>
<li>Assembly final name doesn&rsquo;t include spark2 for Spark 2.x builds <a href="https://github.com/bigdatagenomics/adam/issues/1361">#1361</a></li>
<li>Merge reads2fragments and fragments2reads into a single CLI <a href="https://github.com/bigdatagenomics/adam/issues/1359">#1359</a></li>
<li>Investigate failures to load ExAC.0.3.GRCh38.vcf variants <a href="https://github.com/bigdatagenomics/adam/issues/1351">#1351</a></li>
<li>adam-shell does not allow additional jars via Spark jars argument <a href="https://github.com/bigdatagenomics/adam/issues/1349">#1349</a></li>
<li>Loading GZipped VCF returns an empty RDD <a href="https://github.com/bigdatagenomics/adam/issues/1333">#1333</a></li>
<li>Bump Spark 2 build to Spark 2.1.0 <a href="https://github.com/bigdatagenomics/adam/issues/1330">#1330</a></li>
<li>Rename Transform command TransformAlignments or similar <a href="https://github.com/bigdatagenomics/adam/issues/1328">#1328</a></li>
<li>Replace ADAM2Vcf and Vcf2ADAM commands with TransformGenotypes and TransformVariants <a href="https://github.com/bigdatagenomics/adam/issues/1327">#1327</a></li>
<li>FeatureRDD instantiation tries to cache the RDD <a href="https://github.com/bigdatagenomics/adam/issues/1321">#1321</a></li>
<li>Repository for Pipe API wrappers for bioinformatics tools <a href="https://github.com/bigdatagenomics/adam/issues/1314">#1314</a></li>
<li>Trying to get Spark pipeline working with slightly out of date code. <a href="https://github.com/bigdatagenomics/adam/issues/1313">#1313</a></li>
<li>Support for gVCF merging and genotyping (e.g. CombineGVCFs and GenotypeGVCFs) <a href="https://github.com/bigdatagenomics/adam/issues/1312">#1312</a></li>
<li>Support for read alignment and variant calling in Adam? (e.g. BWA + Freebayes) <a href="https://github.com/bigdatagenomics/adam/issues/1311">#1311</a></li>
<li>Don&rsquo;t include log4j.properties in published JAR <a href="https://github.com/bigdatagenomics/adam/issues/1300">#1300</a></li>
<li>Removing ProgramRecords info when saving data to sam/bam? <a href="https://github.com/bigdatagenomics/adam/issues/1257">#1257</a></li>
<li>ADAM on Slurm/LSF <a href="https://github.com/bigdatagenomics/adam/issues/1229">#1229</a></li>
<li>Maintaining sorted/partitioned knowledge <a href="https://github.com/bigdatagenomics/adam/issues/1216">#1216</a></li>
<li>Evaluate bdg-convert external conversion library proposal <a href="https://github.com/bigdatagenomics/adam/issues/1197">#1197</a></li>
<li>Port AMPCamp Tutorial over <a href="https://github.com/bigdatagenomics/adam/issues/1174">#1174</a></li>
<li>Top level WrappedRDD or similar abstraction <a href="https://github.com/bigdatagenomics/adam/issues/1173">#1173</a></li>
<li>GFF3 formatted features written as single file must include gff-version pragma <a href="https://github.com/bigdatagenomics/adam/issues/1169">#1169</a></li>
<li>Can probably eliminate sort in RealignIndels <a href="https://github.com/bigdatagenomics/adam/issues/1137">#1137</a></li>
<li>Load SV type info field &ndash; need for allele uniquness <a href="https://github.com/bigdatagenomics/adam/issues/1134">#1134</a></li>
<li>BroadcastRegionJoin is not a broadcast join <a href="https://github.com/bigdatagenomics/adam/issues/1110">#1110</a></li>
<li>AlignmentRecordRDD does not extend GenomicRDD per javac <a href="https://github.com/bigdatagenomics/adam/issues/1092">#1092</a></li>
<li>Add generic ReferenceRegion pushdown for parquet files <a href="https://github.com/bigdatagenomics/adam/issues/1047">#1047</a></li>
<li>Use of dataset api in ADAM <a href="https://github.com/bigdatagenomics/adam/issues/1018">#1018</a></li>
<li>Difference running markdups with and without projection <a href="https://github.com/bigdatagenomics/adam/issues/1014">#1014</a></li>
<li>ADAM to BAM conversion fails using relative path <a href="https://github.com/bigdatagenomics/adam/issues/1012">#1012</a></li>
<li>Refactor SequenceDictionary to use Contig instead of SequenceRecord <a href="https://github.com/bigdatagenomics/adam/issues/997">#997</a></li>
<li>NoSuchMethodError due to kryo minor-version mismatch <a href="https://github.com/bigdatagenomics/adam/issues/955">#955</a></li>
<li>Autogen field names in projection package <a href="https://github.com/bigdatagenomics/adam/issues/941">#941</a></li>
<li>Future of schemas in bdg-formats <a href="https://github.com/bigdatagenomics/adam/issues/925">#925</a></li>
<li>genotypeType for genotypes with multiple OtherAlt alleles? <a href="https://github.com/bigdatagenomics/adam/issues/897">#897</a></li>
<li>How to filter genotype RDD with FeatureRDD <a href="https://github.com/bigdatagenomics/adam/issues/890">#890</a></li>
<li>How to convert genotype DataFrame to VariantContext DataFrame / RDD <a href="https://github.com/bigdatagenomics/adam/issues/886">#886</a></li>
<li>R language package for Adam <a href="https://github.com/bigdatagenomics/adam/issues/882">#882</a></li>
<li>How to count genotypes with a 10 node Spark/Adam cluster faster than with BCFTools on a single machine? <a href="https://github.com/bigdatagenomics/adam/issues/879">#879</a></li>
<li>Ensure Java API is up-to-date with Scala API <a href="https://github.com/bigdatagenomics/adam/issues/855">#855</a></li>
<li>BroadcastRegionJoin fails with unmapped reads <a href="https://github.com/bigdatagenomics/adam/issues/821">#821</a></li>
<li>Resolve Fragment vs. SingleReadBucket <a href="https://github.com/bigdatagenomics/adam/issues/789">#789</a></li>
<li>Updating/Publishing the docs/ directory <a href="https://github.com/bigdatagenomics/adam/issues/774">#774</a></li>
<li>Next on empty iterator in BroadcastRegionJoin <a href="https://github.com/bigdatagenomics/adam/issues/661">#661</a></li>
<li>Cleanup code smell in sort work balancing code <a href="https://github.com/bigdatagenomics/adam/issues/635">#635</a></li>
<li>Provide low-impact alternative to <code>transform -repartition</code> for reducing partition size <a href="https://github.com/bigdatagenomics/adam/issues/594">#594</a></li>
<li>Create an ADAM Python API <a href="https://github.com/bigdatagenomics/adam/issues/538">#538</a></li>
<li>Migrate serialization libraries out of ADAM core <a href="https://github.com/bigdatagenomics/adam/issues/448">#448</a></li>
<li>Create standardized, interpretable exceptions for error reporting <a href="https://github.com/bigdatagenomics/adam/issues/420">#420</a></li>
<li>Build info/version info inside ADAM-generated files <a href="https://github.com/bigdatagenomics/adam/issues/188">#188</a></li>
</ul>


<p><strong>Merged and closed pull requests:</strong></p>

<ul>
<li>[ADAM-1854] Add requirements.txt file for RTD. <a href="https://github.com/bigdatagenomics/adam/pull/1856">#1856</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1783] Resolve check issues that block pushing to CRAN. <a href="https://github.com/bigdatagenomics/adam/pull/1849">#1849</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1847] Update ADAM scripts to support self-contained pip install. <a href="https://github.com/bigdatagenomics/adam/pull/1848">#1848</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1845] Only build and publish scaladocs in publish-scaladoc.sh. <a href="https://github.com/bigdatagenomics/adam/pull/1846">#1846</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1843] Install sources before calling scala:doc in publish scaladoc <a href="https://github.com/bigdatagenomics/adam/pull/1844">#1844</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Remove python and R profiles from release script <a href="https://github.com/bigdatagenomics/adam/pull/1842">#1842</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1817] Bump to Hadoop-BAM 7.9.1. <a href="https://github.com/bigdatagenomics/adam/pull/1841">#1841</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1838] Make populating variant.annotation field in Genotype configurable <a href="https://github.com/bigdatagenomics/adam/pull/1839">#1839</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1834] Add proper extensions for SAM/BAM/CRAM output formats. <a href="https://github.com/bigdatagenomics/adam/pull/1835">#1835</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1822] Misc docs cleanup <a href="https://github.com/bigdatagenomics/adam/pull/1827">#1827</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Added missing <strong>init</strong>.py for fulltoc. <a href="https://github.com/bigdatagenomics/adam/pull/1824">#1824</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1821] Add missing fulltoc for Sphinx documentation. <a href="https://github.com/bigdatagenomics/adam/pull/1823">#1823</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Fix link to documentation <a href="https://github.com/bigdatagenomics/adam/pull/1820">#1820</a> (<a href="https://github.com/nzachow">nzachow</a>)</li>
<li>[ADAM-1634] Add algorithm benchmarks to documentation. <a href="https://github.com/bigdatagenomics/adam/pull/1818">#1818</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1813] Delegate right outer shuffle region join to left OSRJ implementation. <a href="https://github.com/bigdatagenomics/adam/pull/1814">#1814</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1807] Check for empty partition when running a piped command. <a href="https://github.com/bigdatagenomics/adam/pull/1812">#1812</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1803] Refactor GenomicRDD.writeTextRdd to util.TextRddWriter. <a href="https://github.com/bigdatagenomics/adam/pull/1809">#1809</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Added Filter error when file loaded does not match schema <a href="https://github.com/bigdatagenomics/adam/pull/1805">#1805</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>changed num_jars count <a href="https://github.com/bigdatagenomics/adam/pull/1802">#1802</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1795] Map -DskipTests=true to exec.skip for Python and R tests. <a href="https://github.com/bigdatagenomics/adam/pull/1800">#1800</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1672] Use working directory for R devtools::document(). <a href="https://github.com/bigdatagenomics/adam/pull/1798">#1798</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1789] Move scala-lang to provided scope. <a href="https://github.com/bigdatagenomics/adam/pull/1790">#1790</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1784] loadIndexedBam should pass the raw globbed path to Hadoop-BAM <a href="https://github.com/bigdatagenomics/adam/pull/1785">#1785</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1664] Add SUPPORT.md file to complement CONTRIBUTING.md. <a href="https://github.com/bigdatagenomics/adam/pull/1781">#1781</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1779] Adding code of contact adapted from the Contributor Convenant, version 1.4. <a href="https://github.com/bigdatagenomics/adam/pull/1780">#1780</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1661] Add file storage benchmarks. <a href="https://github.com/bigdatagenomics/adam/pull/1772">#1772</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1770] Genotype should only store core variant fields. <a href="https://github.com/bigdatagenomics/adam/pull/1771">#1771</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1768] Add InFormatter for unpaired FASTQ. <a href="https://github.com/bigdatagenomics/adam/pull/1769">#1769</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1643] Add S3 access documentation. <a href="https://github.com/bigdatagenomics/adam/pull/1767">#1767</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1763] Apply absolute value to destination partition in ModPartitioner <a href="https://github.com/bigdatagenomics/adam/pull/1766">#1766</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add R and Python into distribution artifacts <a href="https://github.com/bigdatagenomics/adam/pull/1765">#1765</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1655] Move R package to bdgenomics.adam. <a href="https://github.com/bigdatagenomics/adam/pull/1764">#1764</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1753] Only emit realignment targets for reads containing a single INDEL <a href="https://github.com/bigdatagenomics/adam/pull/1756">#1756</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1715] Support validation stringency in Python/R. <a href="https://github.com/bigdatagenomics/adam/pull/1755">#1755</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1680] Eliminate non-determinism in the ShuffleRegionJoin. <a href="https://github.com/bigdatagenomics/adam/pull/1754">#1754</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>update to _replaceRdd with tests <a href="https://github.com/bigdatagenomics/adam/pull/1749">#1749</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1747] Fixed subtract bug and tests <a href="https://github.com/bigdatagenomics/adam/pull/1748">#1748</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>[ADAM-1745] Adding LeftOuterShuffleRegionJoinAndGroupByLeft and tests <a href="https://github.com/bigdatagenomics/adam/pull/1746">#1746</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>Enabled thresholding for joins and standardized regionFn <a href="https://github.com/bigdatagenomics/adam/pull/1741">#1741</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>Making join return types consistent <a href="https://github.com/bigdatagenomics/adam/pull/1737">#1737</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>Opening up permissions on GenericGenomicRDD <a href="https://github.com/bigdatagenomics/adam/pull/1736">#1736</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>[ADAM-1716] Add adam- prefix to distribution module name. <a href="https://github.com/bigdatagenomics/adam/pull/1733">#1733</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1695] Check for illegal genotype index after splitting multi-allelic variants. <a href="https://github.com/bigdatagenomics/adam/pull/1725">#1725</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1517] Bump Parquet version in a manner compatible with Spark 2.2.x <a href="https://github.com/bigdatagenomics/adam/pull/1722">#1722</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1512] Support VCFs with +Inf/-Inf float values. <a href="https://github.com/bigdatagenomics/adam/pull/1721">#1721</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1709] Add ability to left normalize reads containing INDELs. <a href="https://github.com/bigdatagenomics/adam/pull/1711">#1711</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1691] Move bdgenomics.adam to use a namespace package. <a href="https://github.com/bigdatagenomics/adam/pull/1706">#1706</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>moved bdgenomics.adam package to bdgenomics-adam <a href="https://github.com/bigdatagenomics/adam/pull/1705">#1705</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Misc cleanup needed for bigdatagenomics/cannoli#65 <a href="https://github.com/bigdatagenomics/adam/pull/1704">#1704</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1699] Make GenomicRDD.toXxx method names consistent. <a href="https://github.com/bigdatagenomics/adam/pull/1700">#1700</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1694] Add short readable descriptions for toString in subclasses of GenomicRDD. <a href="https://github.com/bigdatagenomics/adam/pull/1698">#1698</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1693] Add adam-shell friendly VariantContextRDD.saveAsVcf method. <a href="https://github.com/bigdatagenomics/adam/pull/1696">#1696</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1688] Add bdg-formats exclusion to org.hammerlab:genomic-loci dependency. <a href="https://github.com/bigdatagenomics/adam/pull/1690">#1690</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1679] Unmapped items should not get caught in requirement when sorting <a href="https://github.com/bigdatagenomics/adam/pull/1687">#1687</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1566] Merge VCF header lines with VCFHeaderLineCount.INTEGER correctly. <a href="https://github.com/bigdatagenomics/adam/pull/1685">#1685</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1682] Add variant quality field. <a href="https://github.com/bigdatagenomics/adam/pull/1684">#1684</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Remove adam- prefix from module directory names. <a href="https://github.com/bigdatagenomics/adam/pull/1681">#1681</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Update to hadoop-bam 7.9.0 and htsjdk 2.11.0. <a href="https://github.com/bigdatagenomics/adam/pull/1678">#1678</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1676] Add more finely grained validation for INFO/FORMAT fields. <a href="https://github.com/bigdatagenomics/adam/pull/1677">#1677</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Python API fixes for AlignmentRecordRDD <a href="https://github.com/bigdatagenomics/adam/pull/1675">#1675</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1673] Don&rsquo;t set PL to empty when no PL is attached to a gVCF record <a href="https://github.com/bigdatagenomics/adam/pull/1674">#1674</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1670] Add ability to selectively project VCF fields. <a href="https://github.com/bigdatagenomics/adam/pull/1671">#1671</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1663] Enable read groups with repeated names when unioning. <a href="https://github.com/bigdatagenomics/adam/pull/1665">#1665</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Maint 2.11 0.18.0 <a href="https://github.com/bigdatagenomics/adam/pull/1659">#1659</a> (<a href="https://github.com/Douglas-H">Douglas-H</a>)</li>
<li>[ADAM-1630] Overhauled docs introduction and added architecture section. <a href="https://github.com/bigdatagenomics/adam/pull/1653">#1653</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add adamR script <a href="https://github.com/bigdatagenomics/adam/pull/1651">#1651</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1647] Fix bad JAR discovery grep in bin/pyadam. <a href="https://github.com/bigdatagenomics/adam/pull/1648">#1648</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1548] Generate reStructuredText from pandoc markdown. <a href="https://github.com/bigdatagenomics/adam/pull/1646">#1646</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Algorithms docs formatting <a href="https://github.com/bigdatagenomics/adam/pull/1645">#1645</a> (<a href="https://github.com/gunjanbaid">gunjanbaid</a>)</li>
<li>Cleaned up docs. <a href="https://github.com/bigdatagenomics/adam/pull/1642">#1642</a> (<a href="https://github.com/gunjanbaid">gunjanbaid</a>)</li>
<li>Making example code compatible with current ADAM build <a href="https://github.com/bigdatagenomics/adam/pull/1641">#1641</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>Cleaning up formatting and spacing of docs. <a href="https://github.com/bigdatagenomics/adam/pull/1640">#1640</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>added ExtractRegions <a href="https://github.com/bigdatagenomics/adam/pull/1637">#1637</a> (<a href="https://github.com/antonkulaga">antonkulaga</a>)</li>
<li>[ADAM-1635] Eliminate passing FASTQ splittable status via config. <a href="https://github.com/bigdatagenomics/adam/pull/1636">#1636</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1614] Add VariantContextRDD to R and Python APIs. <a href="https://github.com/bigdatagenomics/adam/pull/1628">#1628</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1615] Add transform and transmute APIs to Java, R, and Python <a href="https://github.com/bigdatagenomics/adam/pull/1627">#1627</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1625] Use explicit types for header lines <a href="https://github.com/bigdatagenomics/adam/pull/1626">#1626</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1623] Add ProcessingStep to adam-codegen. <a href="https://github.com/bigdatagenomics/adam/pull/1624">#1624</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1607] Update distribution assembly task to attach assembly überjar <a href="https://github.com/bigdatagenomics/adam/pull/1622">#1622</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1490] Add asSingleFile to saveAsFastq and related. <a href="https://github.com/bigdatagenomics/adam/pull/1621">#1621</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Update load method docs in Python and R. <a href="https://github.com/bigdatagenomics/adam/pull/1619">#1619</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1616] Resolve installation directory if scripts are symlinks. <a href="https://github.com/bigdatagenomics/adam/pull/1617">#1617</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1611] Extend pipe APIs to Java, Python, and R. <a href="https://github.com/bigdatagenomics/adam/pull/1613">#1613</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1610] Mark non-serializable field in TwoBitFile as transient. <a href="https://github.com/bigdatagenomics/adam/pull/1612">#1612</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1554] Support saving BGZF VCF output. <a href="https://github.com/bigdatagenomics/adam/pull/1608">#1608</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Adding examples of how to use joins in the real world <a href="https://github.com/bigdatagenomics/adam/pull/1605">#1605</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>[ADAM-1599] Add explicit functions for updating GenomicRDD metadata. <a href="https://github.com/bigdatagenomics/adam/pull/1600">#1600</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1576] Allow translation between two different GenomicRDD types. <a href="https://github.com/bigdatagenomics/adam/pull/1598">#1598</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1444] Ignore failed push to Coveralls. <a href="https://github.com/bigdatagenomics/adam/pull/1595">#1595</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Testing, testing, 1&hellip; 2&hellip; 3&hellip; <a href="https://github.com/bigdatagenomics/adam/pull/1592">#1592</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1417] Removed unused Projection.apply method, add test for Filter. <a href="https://github.com/bigdatagenomics/adam/pull/1591">#1591</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1579] Add unit test coverage for BED12 format. <a href="https://github.com/bigdatagenomics/adam/pull/1587">#1587</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1585] Support additional Illumina FASTQ metadata. <a href="https://github.com/bigdatagenomics/adam/pull/1586">#1586</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1438] Add ability to save FASTA back as a single file. <a href="https://github.com/bigdatagenomics/adam/pull/1581">#1581</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Bump bdg-formats correctly to 0.11.1, not SNAPSHOT. <a href="https://github.com/bigdatagenomics/adam/pull/1577">#1577</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1573] Remove unused Unaligned trait. <a href="https://github.com/bigdatagenomics/adam/pull/1574">#1574</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Slurm deployment readme <a href="https://github.com/bigdatagenomics/adam/pull/1571">#1571</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>[ADAM-1564] Read VCF header from stream in VCFOutFormatter. <a href="https://github.com/bigdatagenomics/adam/pull/1565">#1565</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1562] Index off by one for VCF genotype Number=A attributes. <a href="https://github.com/bigdatagenomics/adam/pull/1563">#1563</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1533] Set Theory <a href="https://github.com/bigdatagenomics/adam/pull/1561">#1561</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>Freebayes FORMAT=&lt;ID=AO,Number=A attribute throws ArrayIndexOutOfBoundsException <a href="https://github.com/bigdatagenomics/adam/pull/1560">#1560</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1551] Emit non-reference model genotype at called sites. <a href="https://github.com/bigdatagenomics/adam/pull/1559">#1559</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1449] Add loadSequenceDictionary to ADAM context. <a href="https://github.com/bigdatagenomics/adam/pull/1557">#1557</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1537] Rename o.b.adam.apis.java package to o.b.adam.api.java <a href="https://github.com/bigdatagenomics/adam/pull/1556">#1556</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1549] Make regions provided to filterByOverlappingRegions an Iterable. <a href="https://github.com/bigdatagenomics/adam/pull/1550">#1550</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-941] Automatically generate projection enums.  <a href="https://github.com/bigdatagenomics/adam/pull/1547">#1547</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1361] Fix misnamed ADAM überjar. <a href="https://github.com/bigdatagenomics/adam/pull/1546">#1546</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1257] Add program record support for alignment/fragment files. <a href="https://github.com/bigdatagenomics/adam/pull/1545">#1545</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1359] Merge <code>reads2fragments</code> and <code>fragments2reads</code> into <code>transformFragments</code> <a href="https://github.com/bigdatagenomics/adam/pull/1543">#1543</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Fix minor format mistakes (and typo) in docs <a href="https://github.com/bigdatagenomics/adam/pull/1542">#1542</a> (<a href="https://github.com/kkaneda">kkaneda</a>)</li>
<li>Add a simple unit test to SingleFastqInputFormat <a href="https://github.com/bigdatagenomics/adam/pull/1541">#1541</a> (<a href="https://github.com/kkaneda">kkaneda</a>)</li>
<li>Support locus predicate in Transform <a href="https://github.com/bigdatagenomics/adam/pull/1540">#1540</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1421] Add java API for <code>loadReferenceFile</code>. <a href="https://github.com/bigdatagenomics/adam/pull/1536">#1536</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Refactor Vcf2ADAM and ADAM2Vcf into TransformGenotypes and TransformVariants <a href="https://github.com/bigdatagenomics/adam/pull/1532">#1532</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1530] Support loading GO:query (S/CR/B)AMs as fragments. <a href="https://github.com/bigdatagenomics/adam/pull/1531">#1531</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1169] Write GFF header line pragma in single file mode. <a href="https://github.com/bigdatagenomics/adam/pull/1529">#1529</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1501] Compute coverage using Dataset API. <a href="https://github.com/bigdatagenomics/adam/pull/1528">#1528</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1497] Add union to GenomicRDD. <a href="https://github.com/bigdatagenomics/adam/pull/1526">#1526</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1486] Respect validation stringency if BAM header load fails. <a href="https://github.com/bigdatagenomics/adam/pull/1525">#1525</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1499] Enable reuse of broadcasted objects in region join. <a href="https://github.com/bigdatagenomics/adam/pull/1524">#1524</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1520] Bump to bdg-formats 0.11.0. <a href="https://github.com/bigdatagenomics/adam/pull/1523">#1523</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Adding fragment InFormatter for Bowtie tab5 format <a href="https://github.com/bigdatagenomics/adam/pull/1522">#1522</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1328] Rename <code>Transform</code> to <code>TransformAlignments</code>. <a href="https://github.com/bigdatagenomics/adam/pull/1521">#1521</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1517] Move to Parquet 1.8.2 in preparation for moving to Spark 2.2.0 <a href="https://github.com/bigdatagenomics/adam/pull/1518">#1518</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Fixed minor typos in README. <a href="https://github.com/bigdatagenomics/adam/pull/1516">#1516</a> (<a href="https://github.com/gunjanbaid">gunjanbaid</a>)</li>
<li>Making TreeRegionJoin consistent with ShuffleRegionJoin <a href="https://github.com/bigdatagenomics/adam/pull/1515">#1515</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>Resolve #1508, #1509 for Pipe API <a href="https://github.com/bigdatagenomics/adam/pull/1511">#1511</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1502] Preserve contig ordering in TwoBitFile sequence dictionary. <a href="https://github.com/bigdatagenomics/adam/pull/1508">#1508</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1483] Remove collapse parameter from AlignmentRecordRDD.toCoverage <a href="https://github.com/bigdatagenomics/adam/pull/1493">#1493</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1377] Adding fragment InFormatter for Bowtie tab6 format <a href="https://github.com/bigdatagenomics/adam/pull/1491">#1491</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1488] Only increment BQSR min quality by 33 once. <a href="https://github.com/bigdatagenomics/adam/pull/1489">#1489</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1481] Refactor ADAMContext loadXxx methods for consistency <a href="https://github.com/bigdatagenomics/adam/pull/1487">#1487</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Add quality score binner <a href="https://github.com/bigdatagenomics/adam/pull/1485">#1485</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Clean up ReferenceRegion.scala and add thresholded overlap and covers <a href="https://github.com/bigdatagenomics/adam/pull/1484">#1484</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>[ADAM-1456] Remove .{type}.adam file extension conversions in type-guessing methods. <a href="https://github.com/bigdatagenomics/adam/pull/1482">#1482</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1480] Add switch to disable the fast concat method. <a href="https://github.com/bigdatagenomics/adam/pull/1479">#1479</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1476] Treat <code>.</code> ALT allele as symbolic non-ref. <a href="https://github.com/bigdatagenomics/adam/pull/1477">#1477</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Adding require for Coverage Conversion and related tests <a href="https://github.com/bigdatagenomics/adam/pull/1472">#1472</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>Add cache argument to loadFeatures, additional Feature timers <a href="https://github.com/bigdatagenomics/adam/pull/1427">#1427</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-882] R API <a href="https://github.com/bigdatagenomics/adam/pull/1397">#1397</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1018] Add support for Spark SQL Datasets. <a href="https://github.com/bigdatagenomics/adam/pull/1391">#1391</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>WIP Python API <a href="https://github.com/bigdatagenomics/adam/pull/1387">#1387</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1365] Apply validation stringency to reads on missing contigs when MD tagging <a href="https://github.com/bigdatagenomics/adam/pull/1366">#1366</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Update dependency and plugin versions <a href="https://github.com/bigdatagenomics/adam/pull/1360">#1360</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1330] Move to Spark 2.1.0. <a href="https://github.com/bigdatagenomics/adam/pull/1332">#1332</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Efficient Joins and (re)Partitioning <a href="https://github.com/bigdatagenomics/adam/pull/1324">#1324</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.22.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2017/04/03/adam-0-dot-22-dot-0-release/"/>
    <updated>2017-04-03T12:00:00-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2017/04/03/adam-0-dot-22-dot-0-release</id>
    <content type="html"><![CDATA[<p>ADAM version 0.22.0 has been <a href="https://github.com/bigdatagenomics/adam/releases">released</a>!</p>

<p>Due to major changes between Spark versions 1.6 and 2.0, we build for combinations of Apache Spark and Scala versions:
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.10-0.22.0">Spark 1.x and Scala 2.10</a>,
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.11-0.22.0">Spark 1.x and Scala 2.11</a>,
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-spark2_2.10-0.22.0">Spark 2.x and Scala 2.10</a>, and
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-spark2_2.11-0.22.0">Spark 2.x and Scala 2.11</a>.</p>

<p>The focus of this release was performance, including major improvements to BQSR and INDEL realignment.</p>

<p>More than 80 other issues were closed in this release, including bug fixes around VCF validation and paired end FASTQ parsing
and new features such as pipe API support for features.</p>

<p>The full list of changes since version 0.21.0 is below.</p>

<!-- more -->


<p><strong>Closed issues:</strong></p>

<ul>
<li>Realign all reads at target site, not just reads with no mismatches <a href="https://github.com/bigdatagenomics/adam/issues/1469">#1469</a></li>
<li>Parallel file merger fails if the output file is smaller than the HDFS block size <a href="https://github.com/bigdatagenomics/adam/issues/1467">#1467</a></li>
<li>Add new realigner arguments to docs <a href="https://github.com/bigdatagenomics/adam/issues/1465">#1465</a></li>
<li>Recalibrate method misspelled as recalibateBaseQualities <a href="https://github.com/bigdatagenomics/adam/issues/1463">#1463</a></li>
<li>FASTQ may try to split GZIPed files <a href="https://github.com/bigdatagenomics/adam/issues/1459">#1459</a></li>
<li>Update to Hadoop-BAM 7.8.0 <a href="https://github.com/bigdatagenomics/adam/issues/1455">#1455</a></li>
<li>Publish Markdown and Scaladoc to the interwebs <a href="https://github.com/bigdatagenomics/adam/issues/1453">#1453</a></li>
<li>Make VariantContextConverter public <a href="https://github.com/bigdatagenomics/adam/issues/1451">#1451</a></li>
<li>Apply method in FragmentRDD is package private <a href="https://github.com/bigdatagenomics/adam/issues/1445">#1445</a></li>
<li>Thread pool will block inside of pipe command for streams too large to buffer <a href="https://github.com/bigdatagenomics/adam/issues/1442">#1442</a></li>
<li>FeatureRDD.apply() does not allow addition of other parameters with defaults in the case class <a href="https://github.com/bigdatagenomics/adam/issues/1439">#1439</a></li>
<li>Question : Why the number of paired sequence in adam-0.21.0 less than adam-0.19.0? <a href="https://github.com/bigdatagenomics/adam/issues/1424">#1424</a></li>
<li>loadCoverage missing from Java API <a href="https://github.com/bigdatagenomics/adam/issues/1420">#1420</a></li>
<li>Estimate contig lengths in SequenceDictionary for BED, GFF3, GTF, and NarrowPeak feature formats <a href="https://github.com/bigdatagenomics/adam/issues/1410">#1410</a></li>
<li>loadIntervalList FeatureRDD has empty SequenceDictionary <a href="https://github.com/bigdatagenomics/adam/issues/1409">#1409</a></li>
<li>problem using transform command <a href="https://github.com/bigdatagenomics/adam/issues/1406">#1406</a></li>
<li>Add coveralls <a href="https://github.com/bigdatagenomics/adam/issues/1403">#1403</a></li>
<li>INDEL realigner binary search conditional is flipped <a href="https://github.com/bigdatagenomics/adam/issues/1402">#1402</a></li>
<li>Delete adam-scripts/R <a href="https://github.com/bigdatagenomics/adam/issues/1398">#1398</a></li>
<li>Data missing when transfroming FASTQ to Adam <a href="https://github.com/bigdatagenomics/adam/issues/1393">#1393</a></li>
<li>java.io.FileNotFoundException when file exists <a href="https://github.com/bigdatagenomics/adam/issues/1385">#1385</a></li>
<li>Off-by-1 error in FASTQ InputFormat start positioning code <a href="https://github.com/bigdatagenomics/adam/issues/1383">#1383</a></li>
<li>Set the wrong value for end for symbolic alts <a href="https://github.com/bigdatagenomics/adam/issues/1381">#1381</a></li>
<li>RecordGroupDictionary should support <code>isEmpty</code> <a href="https://github.com/bigdatagenomics/adam/issues/1380">#1380</a></li>
<li>Add pipe API in and out formatters for Features <a href="https://github.com/bigdatagenomics/adam/issues/1374">#1374</a></li>
<li>Increase visibility for SupportedHeaderLines.allHeaderLines <a href="https://github.com/bigdatagenomics/adam/issues/1372">#1372</a></li>
<li>Bits of VariantContextConverter don&rsquo;t get ValidationStringencied <a href="https://github.com/bigdatagenomics/adam/issues/1371">#1371</a></li>
<li>Add Markdown docs for Pipe API <a href="https://github.com/bigdatagenomics/adam/issues/1368">#1368</a></li>
<li>Array[Consensus] not registered <a href="https://github.com/bigdatagenomics/adam/issues/1367">#1367</a></li>
<li>ValidationStringency in MDTagging should apply to reads on unknown references <a href="https://github.com/bigdatagenomics/adam/issues/1365">#1365</a></li>
<li>When doing a release, the SNAPSHOT should bump by 0.1.0, not 0.0.1 <a href="https://github.com/bigdatagenomics/adam/issues/1364">#1364</a></li>
<li>FromKnowns consensus generator fails if no reads overlap a consensus <a href="https://github.com/bigdatagenomics/adam/issues/1362">#1362</a></li>
<li>Performance tune-up in BQSR <a href="https://github.com/bigdatagenomics/adam/issues/1358">#1358</a></li>
<li>Increase visibility for ADAMContext.sc and/or getFs&hellip; methods <a href="https://github.com/bigdatagenomics/adam/issues/1356">#1356</a></li>
<li>Pipe API formatters need to be public <a href="https://github.com/bigdatagenomics/adam/issues/1354">#1354</a></li>
<li>Version 0.21.0: VariantContextConverter fails for 1000G VCF data <a href="https://github.com/bigdatagenomics/adam/issues/1353">#1353</a></li>
<li>ConsensusModel&rsquo;s can&rsquo;t really be instantiated <a href="https://github.com/bigdatagenomics/adam/issues/1352">#1352</a></li>
<li>Runtime conflicts in transitive versions of Guava dependency <a href="https://github.com/bigdatagenomics/adam/issues/1350">#1350</a></li>
<li>Transcript Effects ignored if more than 1 <a href="https://github.com/bigdatagenomics/adam/issues/1347">#1347</a></li>
<li>Remove &ldquo;fork&rdquo; tag from releases <a href="https://github.com/bigdatagenomics/adam/issues/1344">#1344</a></li>
<li>Refactor isSorted boolean parameters to sorted <a href="https://github.com/bigdatagenomics/adam/issues/1341">#1341</a></li>
<li>Loading GZipped VCF returns an empty RDD <a href="https://github.com/bigdatagenomics/adam/issues/1333">#1333</a></li>
<li>Follow up on error messages in build scripts <a href="https://github.com/bigdatagenomics/adam/issues/1331">#1331</a></li>
<li>Bump Spark 2 build to Spark 2.1.0 <a href="https://github.com/bigdatagenomics/adam/issues/1330">#1330</a></li>
<li>FeatureRDD instantiation tries to cache the RDD <a href="https://github.com/bigdatagenomics/adam/issues/1321">#1321</a></li>
<li>Load queryname sorted BAMs as Fragments <a href="https://github.com/bigdatagenomics/adam/issues/1303">#1303</a></li>
<li>Run Duplicate Marking on Fragments <a href="https://github.com/bigdatagenomics/adam/issues/1302">#1302</a></li>
<li>GenomicRDD.pipe may hang on failure error codes <a href="https://github.com/bigdatagenomics/adam/issues/1282">#1282</a></li>
<li>IllegalArgumentException Wrong FS for vcf_head files on HDFS <a href="https://github.com/bigdatagenomics/adam/issues/1272">#1272</a></li>
<li>java.io.NotSerializableException: org.bdgenomics.formats.avro.AlignmentRecord <a href="https://github.com/bigdatagenomics/adam/issues/1240">#1240</a></li>
<li>Investigate sorted join in dataset api <a href="https://github.com/bigdatagenomics/adam/issues/1223">#1223</a></li>
<li>Support looser validation stringency for loading some VCF Integer fields <a href="https://github.com/bigdatagenomics/adam/issues/1213">#1213</a></li>
<li>Add new feature-overlap command to demonstrate new region joins <a href="https://github.com/bigdatagenomics/adam/issues/1194">#1194</a></li>
<li>What should our API at the command line look like? <a href="https://github.com/bigdatagenomics/adam/issues/1178">#1178</a></li>
<li>Split apart partition and join in ShuffleRegionJoin <a href="https://github.com/bigdatagenomics/adam/issues/1175">#1175</a></li>
<li>Merging files should be multithreaded <a href="https://github.com/bigdatagenomics/adam/issues/1164">#1164</a></li>
<li>File _rgdict.avro does not exist <a href="https://github.com/bigdatagenomics/adam/issues/1150">#1150</a></li>
<li>how to collect the .adam files from Spark cluster multiple nodes and some questions about avocado <a href="https://github.com/bigdatagenomics/adam/issues/1140">#1140</a></li>
<li>JFYI: tiny forked adam-core &ldquo;0.20.0&rdquo; release <a href="https://github.com/bigdatagenomics/adam/issues/1139">#1139</a></li>
<li>Samtools (htslib) integration testing <a href="https://github.com/bigdatagenomics/adam/issues/1120">#1120</a></li>
<li>AlignmentRecordRDD does not extend GenomicRDD per javac <a href="https://github.com/bigdatagenomics/adam/issues/1092">#1092</a></li>
<li>Release ADAM version 0.21.0 <a href="https://github.com/bigdatagenomics/adam/issues/1088">#1088</a></li>
<li>Difference running markdups with and without projection <a href="https://github.com/bigdatagenomics/adam/issues/1014">#1014</a></li>
<li>ADAM to BAM conversion fails using relative path <a href="https://github.com/bigdatagenomics/adam/issues/1012">#1012</a></li>
<li>Refactor SequenceDictionary to use Contig instead of SequenceRecord <a href="https://github.com/bigdatagenomics/adam/issues/997">#997</a></li>
<li>Customize adam-main cli from configuration file <a href="https://github.com/bigdatagenomics/adam/issues/918">#918</a></li>
<li>genotypeType for genotypes with multiple OtherAlt alleles? <a href="https://github.com/bigdatagenomics/adam/issues/897">#897</a></li>
<li>How to convert genotype DataFrame to VariantContext DataFrame / RDD <a href="https://github.com/bigdatagenomics/adam/issues/886">#886</a></li>
<li>Ensure Java API is up-to-date with Scala API <a href="https://github.com/bigdatagenomics/adam/issues/855">#855</a></li>
<li>Improve parallelism during FASTA output <a href="https://github.com/bigdatagenomics/adam/issues/842">#842</a></li>
<li>Explicitly validate user args passed to transform enhancement <a href="https://github.com/bigdatagenomics/adam/issues/841">#841</a></li>
<li>BroadcastRegionJoin fails with unmapped reads <a href="https://github.com/bigdatagenomics/adam/issues/821">#821</a></li>
<li>Resolve Fragment vs. SingleReadBucket <a href="https://github.com/bigdatagenomics/adam/issues/789">#789</a></li>
<li>Add profile for skipping test compilation/resolution <a href="https://github.com/bigdatagenomics/adam/issues/713">#713</a></li>
<li>Next on empty iterator in BroadcastRegionJoin <a href="https://github.com/bigdatagenomics/adam/issues/661">#661</a></li>
<li>Cleanup code smell in sort work balancing code <a href="https://github.com/bigdatagenomics/adam/issues/635">#635</a></li>
<li>Remove reliance on MD tags <a href="https://github.com/bigdatagenomics/adam/issues/622">#622</a></li>
<li>Provide low-impact alternative to <code>transform -repartition</code> for reducing partition size <a href="https://github.com/bigdatagenomics/adam/issues/594">#594</a></li>
<li>Clean up Rich records <a href="https://github.com/bigdatagenomics/adam/issues/577">#577</a></li>
<li>Create standardized, interpretable exceptions for error reporting <a href="https://github.com/bigdatagenomics/adam/issues/420">#420</a></li>
<li>Create ADAM Benchmarking suite <a href="https://github.com/bigdatagenomics/adam/issues/120">#120</a></li>
</ul>


<p><strong>Merged and closed pull requests:</strong></p>

<ul>
<li>[ADAM-1469] Don&rsquo;t filter on whether reads have mismatches during realignment <a href="https://github.com/bigdatagenomics/adam/pull/1470">#1470</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1467] Skip <code>concat</code> call if there is only one shard. <a href="https://github.com/bigdatagenomics/adam/pull/1468">#1468</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1465] Updating realigner CLI docs. <a href="https://github.com/bigdatagenomics/adam/pull/1466">#1466</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1463] Rename recalibateBaseQualities method as recalibrateBaseQualities <a href="https://github.com/bigdatagenomics/adam/pull/1464">#1464</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1453] Add hooks to publish ADAM docs from CI flow. <a href="https://github.com/bigdatagenomics/adam/pull/1461">#1461</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1459] Don&rsquo;t split FASTQ when compressed. <a href="https://github.com/bigdatagenomics/adam/pull/1459">#1459</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1451] Make VariantContextConverter class and convert methods public <a href="https://github.com/bigdatagenomics/adam/pull/1452">#1452</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Moving API overview from building apps doc to new source file. <a href="https://github.com/bigdatagenomics/adam/pull/1450">#1450</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1424] Adding test for reads dropped in 0.21.0. <a href="https://github.com/bigdatagenomics/adam/pull/1448">#1448</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1439] Add inferSequenceDictionary ctr to FeatureRDD. <a href="https://github.com/bigdatagenomics/adam/pull/1447">#1447</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1445] Make apply method for FragmentRDD public. <a href="https://github.com/bigdatagenomics/adam/pull/1446">#1446</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1442] Fix thread pool deadlock in GenomicRDD.pipe <a href="https://github.com/bigdatagenomics/adam/pull/1443">#1443</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1164] Add parallel file merger. <a href="https://github.com/bigdatagenomics/adam/pull/1441">#1441</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Dependency version bump + BroadcastRegionJoin fix <a href="https://github.com/bigdatagenomics/adam/pull/1440">#1440</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>added JavaApi for loadCoverage <a href="https://github.com/bigdatagenomics/adam/pull/1437">#1437</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Update versions, etc. in build docs <a href="https://github.com/bigdatagenomics/adam/pull/1435">#1435</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Add test sample(verify number of reads in loadAlignments function) and ADAM SNAPSHOT document <a href="https://github.com/bigdatagenomics/adam/pull/1433">#1433</a> (<a href="https://github.com/xubo245">xubo245</a>)</li>
<li>Add cache argument to loadFeatures, additional Feature timers <a href="https://github.com/bigdatagenomics/adam/pull/1427">#1427</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>feat: speed up 2bit file extract <a href="https://github.com/bigdatagenomics/adam/pull/1426">#1426</a> (<a href="https://github.com/Blaok">Blaok</a>)</li>
<li>BQSR refactor for perf improvements <a href="https://github.com/bigdatagenomics/adam/pull/1423">#1423</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add ADAMContext/GenomicRDD/pipe docs <a href="https://github.com/bigdatagenomics/adam/pull/1422">#1422</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>INDEL realigner cleanup <a href="https://github.com/bigdatagenomics/adam/pull/1412">#1412</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Estimate contig lengths in SequenceDictionary for BED, GFF3, GTF, and NarrowPeak feature formats <a href="https://github.com/bigdatagenomics/adam/pull/1411">#1411</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Add coveralls badge to README.md. <a href="https://github.com/bigdatagenomics/adam/pull/1408">#1408</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1403] Push coverage reports to Coveralls. <a href="https://github.com/bigdatagenomics/adam/pull/1404">#1404</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Added instrumentation timers around joins. <a href="https://github.com/bigdatagenomics/adam/pull/1401">#1401</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add Apache Spark version to &mdash;version text <a href="https://github.com/bigdatagenomics/adam/pull/1400">#1400</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1398] Delete adam-scripts/R. <a href="https://github.com/bigdatagenomics/adam/pull/1399">#1399</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1383] Use gt instead of gteq in FASTQ input format line size checks <a href="https://github.com/bigdatagenomics/adam/pull/1396">#1396</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Maint spark2 2.11 0.21.0 <a href="https://github.com/bigdatagenomics/adam/pull/1395">#1395</a> (<a href="https://github.com/A-Tsai">A-Tsai</a>)</li>
<li>[ADAM-1393] fix missing reads when transforming fastq to adam <a href="https://github.com/bigdatagenomics/adam/pull/1394">#1394</a> (<a href="https://github.com/A-Tsai">A-Tsai</a>)</li>
<li>[ADAM-1380] Adds isEmpty method to RecordGroupDictionary. <a href="https://github.com/bigdatagenomics/adam/pull/1392">#1392</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1381] Fix Variant end position. <a href="https://github.com/bigdatagenomics/adam/pull/1389">#1389</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Make javac see that AlignmentRecordRDD extends GenomicRDD <a href="https://github.com/bigdatagenomics/adam/pull/1386">#1386</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Added ShuffleRegionJoin usage docs <a href="https://github.com/bigdatagenomics/adam/pull/1384">#1384</a> (<a href="https://github.com/devin-petersohn">devin-petersohn</a>)</li>
<li>Misc. INDEL realigner bugfixes <a href="https://github.com/bigdatagenomics/adam/pull/1382">#1382</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add pipe API in and out formatters for Features <a href="https://github.com/bigdatagenomics/adam/pull/1378">#1378</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1356] Make ADAMContext.getFsAndFiles and related protected visibility <a href="https://github.com/bigdatagenomics/adam/pull/1376">#1376</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1372] Increase visibility for DefaultHeaderLines.allHeaderLines <a href="https://github.com/bigdatagenomics/adam/pull/1375">#1375</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1371] Wrap ADAM->htsjdk VariantContext conversion with validation stringency. <a href="https://github.com/bigdatagenomics/adam/pull/1373">#1373</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1367] Register Consensus array for serialization. <a href="https://github.com/bigdatagenomics/adam/pull/1369">#1369</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1365] Apply validation stringency to reads on missing contigs when MD tagging <a href="https://github.com/bigdatagenomics/adam/pull/1366">#1366</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1362] Fixing issue where FromKnowns consensus model fails if no reads hit a target. <a href="https://github.com/bigdatagenomics/adam/pull/1363">#1363</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1352] Clean up consensus model usage. <a href="https://github.com/bigdatagenomics/adam/pull/1357">#1357</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Increase visibility for InFormatter case classes from package private to public <a href="https://github.com/bigdatagenomics/adam/pull/1355">#1355</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Use htsjdk getAttributeAsList for VCF INFO ANN key <a href="https://github.com/bigdatagenomics/adam/pull/1348">#1348</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Fixes parsing variant annotations for multi-allelic rows <a href="https://github.com/bigdatagenomics/adam/pull/1346">#1346</a> (<a href="https://github.com/majkiw">majkiw</a>)</li>
<li>Sort pull requests by id <a href="https://github.com/bigdatagenomics/adam/pull/1345">#1345</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>HBase genotypes backend -revised <a href="https://github.com/bigdatagenomics/adam/pull/1335">#1335</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>[ADAM-1330] Move to Spark 2.1.0. <a href="https://github.com/bigdatagenomics/adam/pull/1332">#1332</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Support deduping fragments <a href="https://github.com/bigdatagenomics/adam/pull/1309">#1309</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1280] Silence CRAM logging in tests. <a href="https://github.com/bigdatagenomics/adam/pull/1294">#1294</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Added test to try and repro #1282. <a href="https://github.com/bigdatagenomics/adam/pull/1292">#1292</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.21.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2017/01/06/adam-0-dot-21-dot-0-release/"/>
    <updated>2017-01-06T11:00:00-08:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2017/01/06/adam-0-dot-21-dot-0-release</id>
    <content type="html"><![CDATA[<p>ADAM version 0.21.0 has been <a href="https://github.com/bigdatagenomics/adam/releases">released</a>!</p>

<p>Due to major changes between Spark versions 1.6 and 2.0, we now build for combinations of Apache Spark and Scala versions:
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.10-0.21.0">Spark 1.x and Scala 2.10</a>,
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.11-0.21.0">Spark 1.x and Scala 2.11</a>,
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-spark2_2.10-0.21.0">Spark 2.x and Scala 2.10</a>, and
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-spark2_2.11-0.21.0">Spark 2.x and Scala 2.11</a>.
The Spark 2.x build-time dependency will be bumped to version 2.1.0 in the next release of ADAM, see issue <a href="https://github.com/bigdatagenomics/adam/issues/1330">#1330</a>.</p>

<p>One focus of this release was documentation, both at the developer API level, including extensive javadoc and scaladoc
source code comments, and at the user level (e.g. <a href="https://github.com/bigdatagenomics/adam/tree/master/docs/source">https://github.com/bigdatagenomics/adam/tree/master/docs/source</a>). The
user docs can be compiled to PDF or HTML with pandoc, but to be honest they look better rendered as Markdown on Github.</p>

<p>Another focus was to more closely follow the VCF specification(s) when reading from and writing to VCF.
For this we made significant changes to our variant and variant annotation schema and added support
for version 1.0 of the <a href="http://snpeff.sourceforge.net/VCFannotationformat_v1.0.pdf">VCF INFO &lsquo;ANN&rsquo; key specification</a>.
This work will continue for our genotype and genotype annotation schema in the next version of ADAM.</p>

<p>The full list of changes since version 0.20.0 is below.</p>

<!-- more -->


<p><strong>Closed issues:</strong></p>

<ul>
<li>Update Markdown docs with ValidationStringency in VCF&lt;&ndash;>ADAM CLI <a href="https://github.com/bigdatagenomics/adam/issues/1342">#1342</a></li>
<li>Variant VCFHeaderLine metadata does not handle wildcards properly <a href="https://github.com/bigdatagenomics/adam/issues/1339">#1339</a></li>
<li>Close called multiple times on VCF header stream <a href="https://github.com/bigdatagenomics/adam/issues/1337">#1337</a></li>
<li>BroadcastRegionJoin has serialization failures <a href="https://github.com/bigdatagenomics/adam/issues/1334">#1334</a></li>
<li>adam-cli uses git-commit-id-plugin which breaks release? <a href="https://github.com/bigdatagenomics/adam/issues/1322">#1322</a></li>
<li>move_to_xyz scripts should have interlocks&hellip; <a href="https://github.com/bigdatagenomics/adam/issues/1317">#1317</a></li>
<li>Lineage for partitionAndJoin in ShuffleRegionJoin causes StackOverflow Errors <a href="https://github.com/bigdatagenomics/adam/issues/1308">#1308</a></li>
<li>Add move_to_spark_1.sh script and update README to mention <a href="https://github.com/bigdatagenomics/adam/issues/1307">#1307</a></li>
<li>adam-submit transform fails with Exception in thread &ldquo;main&rdquo; java.lang.IncompatibleClassChangeError: Implementing class <a href="https://github.com/bigdatagenomics/adam/issues/1306">#1306</a></li>
<li>private ADAMContext constructor? <a href="https://github.com/bigdatagenomics/adam/issues/1296">#1296</a></li>
<li>AlignmentRecord.mateAlignmentEnd never set <a href="https://github.com/bigdatagenomics/adam/issues/1290">#1290</a></li>
<li>how to submit my own driver class via adam-submit? <a href="https://github.com/bigdatagenomics/adam/issues/1289">#1289</a></li>
<li>ReferenceRegion on Genotype seems busted? <a href="https://github.com/bigdatagenomics/adam/issues/1286">#1286</a></li>
<li>Clarify strandedness in ReferenceRegion apply methods <a href="https://github.com/bigdatagenomics/adam/issues/1285">#1285</a></li>
<li>Parquet and CRAM debug logging during unit tests <a href="https://github.com/bigdatagenomics/adam/issues/1280">#1280</a></li>
<li>Add more ANN field parsing unit tests <a href="https://github.com/bigdatagenomics/adam/issues/1273">#1273</a></li>
<li>loadVariantAnnotations returns empty RDD <a href="https://github.com/bigdatagenomics/adam/issues/1271">#1271</a></li>
<li>Implement joinVariantAnnotations with region join <a href="https://github.com/bigdatagenomics/adam/issues/1259">#1259</a></li>
<li>Count how many chromosome in the range of the kmer <a href="https://github.com/bigdatagenomics/adam/issues/1249">#1249</a></li>
<li>ADAM minor release to support htsjdk 2.7.0? <a href="https://github.com/bigdatagenomics/adam/issues/1248">#1248</a></li>
<li>how to config kryo.registrator programmatically <a href="https://github.com/bigdatagenomics/adam/issues/1245">#1245</a></li>
<li>Does the nested record Flattener drop Maps/Arrays? <a href="https://github.com/bigdatagenomics/adam/issues/1244">#1244</a></li>
<li>Dead-ish code cleanup in <code>org.bdgenomics.adam.utils</code> <a href="https://github.com/bigdatagenomics/adam/issues/1242">#1242</a></li>
<li>java.io.FileNotFoundException for old adam file after upgrade to adam0.20 <a href="https://github.com/bigdatagenomics/adam/issues/1240">#1240</a></li>
<li>please add maven-source-plugin into the pom file <a href="https://github.com/bigdatagenomics/adam/issues/1239">#1239</a></li>
<li>Assembly jar doesn&rsquo;t get rebuilt on CLI changes <a href="https://github.com/bigdatagenomics/adam/issues/1238">#1238</a></li>
<li>how to compare with the last the column for the same chromosome name? <a href="https://github.com/bigdatagenomics/adam/issues/1237">#1237</a></li>
<li>Need a way for users to add VCF header lines <a href="https://github.com/bigdatagenomics/adam/issues/1233">#1233</a></li>
<li>Enhancements to VCF save <a href="https://github.com/bigdatagenomics/adam/issues/1232">#1232</a></li>
<li>Must we split multi-allelic sites in our Genotype model? <a href="https://github.com/bigdatagenomics/adam/issues/1231">#1231</a></li>
<li>Can&rsquo;t override default -collapse in reads2coverage <a href="https://github.com/bigdatagenomics/adam/issues/1228">#1228</a></li>
<li>Reads2coverage NPEs on unmapped reads <a href="https://github.com/bigdatagenomics/adam/issues/1227">#1227</a></li>
<li>Strand bias doesn&rsquo;t get exported <a href="https://github.com/bigdatagenomics/adam/issues/1226">#1226</a></li>
<li>Move ADAMFunSuite helper functions upstream to SparkFunSuite <a href="https://github.com/bigdatagenomics/adam/issues/1225">#1225</a></li>
<li>broadcast join using interval tree <a href="https://github.com/bigdatagenomics/adam/issues/1224">#1224</a></li>
<li>Instrumentation is lost in ShuffleRegionJoin <a href="https://github.com/bigdatagenomics/adam/issues/1222">#1222</a></li>
<li>Bump Spark, Scala, Hadoop dependency versions <a href="https://github.com/bigdatagenomics/adam/issues/1221">#1221</a></li>
<li>GenomicRDD shuffle region join passes partition count to partition size <a href="https://github.com/bigdatagenomics/adam/issues/1220">#1220</a></li>
<li>Scala compile errors downstream of Spark 2 Scala 2.11 artifacts <a href="https://github.com/bigdatagenomics/adam/issues/1218">#1218</a></li>
<li>Javac error: incompatible types: SparkContext cannot be converted to ADAMContext <a href="https://github.com/bigdatagenomics/adam/issues/1217">#1217</a></li>
<li>Release 0.20.0 artifacts failed Sonatype Nexus validation <a href="https://github.com/bigdatagenomics/adam/issues/1212">#1212</a></li>
<li>Release script failed for 0.20.0 release <a href="https://github.com/bigdatagenomics/adam/issues/1211">#1211</a></li>
<li>gVCF &ndash; can&rsquo;t load multi-allelic sites <a href="https://github.com/bigdatagenomics/adam/issues/1202">#1202</a></li>
<li>Allow open-ended intervals in loadIndexedBam <a href="https://github.com/bigdatagenomics/adam/issues/1196">#1196</a></li>
<li>Interval tree join in ADAM <a href="https://github.com/bigdatagenomics/adam/issues/1171">#1171</a></li>
<li>spark-submit throw exception in spark-standalone using .adam which transformed from .vcf <a href="https://github.com/bigdatagenomics/adam/issues/1121">#1121</a></li>
<li>BroadcastRegionJoin is not a broadcast join <a href="https://github.com/bigdatagenomics/adam/issues/1110">#1110</a></li>
<li>Improve test coverage of VariantContextConverter <a href="https://github.com/bigdatagenomics/adam/issues/1107">#1107</a></li>
<li>Variant dbsnp rs id tracking in vcf2adam and ADAM2Vcf <a href="https://github.com/bigdatagenomics/adam/issues/1103">#1103</a></li>
<li>Document core ADAM transform methods <a href="https://github.com/bigdatagenomics/adam/issues/1085">#1085</a></li>
<li>Document deploying ADAM on Toil <a href="https://github.com/bigdatagenomics/adam/issues/1084">#1084</a></li>
<li>Clean up packages <a href="https://github.com/bigdatagenomics/adam/issues/1083">#1083</a></li>
<li>VariantCallingAnnotations is getting populated with INFO fields <a href="https://github.com/bigdatagenomics/adam/issues/1063">#1063</a></li>
<li>How to load DatabaseVariantAnnotation information ? <a href="https://github.com/bigdatagenomics/adam/issues/1049">#1049</a></li>
<li>Release ADAM version 0.20.0 <a href="https://github.com/bigdatagenomics/adam/issues/1048">#1048</a></li>
<li>Support VCF annotation ANN field in vcf2adam and adam2vcf <a href="https://github.com/bigdatagenomics/adam/issues/1044">#1044</a></li>
<li>How to create a rich(er) VariantContext RDD? Reconstruct VCF INFO fields. <a href="https://github.com/bigdatagenomics/adam/issues/878">#878</a></li>
<li>Add biologist targeted section to the README <a href="https://github.com/bigdatagenomics/adam/issues/497">#497</a></li>
<li>Update usage docs running for EC2 and CDH <a href="https://github.com/bigdatagenomics/adam/issues/493">#493</a></li>
<li>Add docs about building downstream apps on top of ADAM <a href="https://github.com/bigdatagenomics/adam/issues/291">#291</a></li>
<li>Variant filter representation <a href="https://github.com/bigdatagenomics/adam/issues/194">#194</a></li>
</ul>


<p><strong>Merged and closed pull requests:</strong></p>

<ul>
<li>[ADAM-1342] Update CLI docs after #1288 merged. <a href="https://github.com/bigdatagenomics/adam/pull/1343">#1343</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1339] Use glob-safe method to load VCF header metadata for Parquet <a href="https://github.com/bigdatagenomics/adam/pull/1340">#1340</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1337] Remove os.{flush,close} calls after writing VCF header. <a href="https://github.com/bigdatagenomics/adam/pull/1338">#1338</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1334] Clean up serialization issues in Broadcast region join. <a href="https://github.com/bigdatagenomics/adam/pull/1336">#1336</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1307] move_to_spark_2 fails after moving to scala 2.11. <a href="https://github.com/bigdatagenomics/adam/pull/1329">#1329</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>unroll/optimize some JavaConversions <a href="https://github.com/bigdatagenomics/adam/pull/1326">#1326</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>clean up *Join type-params/scaldocs <a href="https://github.com/bigdatagenomics/adam/pull/1325">#1325</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>[ADAM-1322] Skip git commit plugin if .git is missing. <a href="https://github.com/bigdatagenomics/adam/pull/1323">#1323</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Supports access to indexed fa and fasta files <a href="https://github.com/bigdatagenomics/adam/pull/1320">#1320</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Add interlocks for move_to_xyz scripts. <a href="https://github.com/bigdatagenomics/adam/pull/1319">#1319</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1307] Add script for moving to Spark 1. <a href="https://github.com/bigdatagenomics/adam/pull/1318">#1318</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Update move_to_spark_2.sh <a href="https://github.com/bigdatagenomics/adam/pull/1316">#1316</a> (<a href="https://github.com/creggian">creggian</a>)</li>
<li>[ADAM-1308] Fix stack overflow in join with custom iterator impl. <a href="https://github.com/bigdatagenomics/adam/pull/1315">#1315</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Why Adam? section added to README.md <a href="https://github.com/bigdatagenomics/adam/pull/1310">#1310</a> (<a href="https://github.com/tverbeiren">tverbeiren</a>)</li>
<li>Add docs about using ADAM&rsquo;s Kryo registrator from another Kryo registrator. <a href="https://github.com/bigdatagenomics/adam/pull/1305">#1305</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add docs about building downstream applications <a href="https://github.com/bigdatagenomics/adam/pull/1304">#1304</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-493] Add ADAM-on-Spark-on-YARN docs. <a href="https://github.com/bigdatagenomics/adam/pull/1301">#1301</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Code style fixes <a href="https://github.com/bigdatagenomics/adam/pull/1299">#1299</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Make ADAMContext and JavaADAMContext constructors public <a href="https://github.com/bigdatagenomics/adam/pull/1298">#1298</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Remove back reference between VariantAnnotation and Variant <a href="https://github.com/bigdatagenomics/adam/pull/1297">#1297</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1280] Silence CRAM logging in tests. <a href="https://github.com/bigdatagenomics/adam/pull/1294">#1294</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>HBase as a separate repo <a href="https://github.com/bigdatagenomics/adam/pull/1293">#1293</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>Reference region cleanup <a href="https://github.com/bigdatagenomics/adam/pull/1291">#1291</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Clean rewrite of VariantContextConverter <a href="https://github.com/bigdatagenomics/adam/pull/1288">#1288</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>add function:filterByOverlappingRegions <a href="https://github.com/bigdatagenomics/adam/pull/1287">#1287</a> (<a href="https://github.com/liamlee">liamlee</a>)</li>
<li>Populate fields on VariantAnnotation <a href="https://github.com/bigdatagenomics/adam/pull/1283">#1283</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Add VCF headers for fields in Variant and VariantAnnotation records <a href="https://github.com/bigdatagenomics/adam/pull/1281">#1281</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>CGCloud deploy docs <a href="https://github.com/bigdatagenomics/adam/pull/1279">#1279</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>some style nits <a href="https://github.com/bigdatagenomics/adam/pull/1278">#1278</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>use ParsedLoci in loadIndexedBam <a href="https://github.com/bigdatagenomics/adam/pull/1277">#1277</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>Increasing unit test coverage for VariantContextConverter <a href="https://github.com/bigdatagenomics/adam/pull/1276">#1276</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Expose FeatureRDD to public <a href="https://github.com/bigdatagenomics/adam/pull/1275">#1275</a> (<a href="https://github.com/Georgehe4">Georgehe4</a>)</li>
<li>Clean up CLI operation categories and names, and add documentation for CLI <a href="https://github.com/bigdatagenomics/adam/pull/1274">#1274</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Rename org.bdgenomics.adam.rdd.variation package to o.b.a.rdd.variant <a href="https://github.com/bigdatagenomics/adam/pull/1270">#1270</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>use testFile in some tests <a href="https://github.com/bigdatagenomics/adam/pull/1268">#1268</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>[ADAM-1083] Cleaning up <code>org.bdgenomics.adam.models</code>. <a href="https://github.com/bigdatagenomics/adam/pull/1267">#1267</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>make py file py3-forward-compatible <a href="https://github.com/bigdatagenomics/adam/pull/1266">#1266</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>rm accidentally-added file <a href="https://github.com/bigdatagenomics/adam/pull/1265">#1265</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Finishing up the cleanup on org.bdgenomics.adam.rdd. <a href="https://github.com/bigdatagenomics/adam/pull/1264">#1264</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Clean up <code>org.bdgenomics.adam.rich</code> package. <a href="https://github.com/bigdatagenomics/adam/pull/1263">#1263</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add docs for transform pipeline, ADAM-on-Toil <a href="https://github.com/bigdatagenomics/adam/pull/1262">#1262</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>updates for bdg utils 0.2.9-SNAPSHOT <a href="https://github.com/bigdatagenomics/adam/pull/1261">#1261</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1233] Expose header lines in Variant-related GenomicRDDs <a href="https://github.com/bigdatagenomics/adam/pull/1260">#1260</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1221] Bump Spark/Hadoop versions. <a href="https://github.com/bigdatagenomics/adam/pull/1258">#1258</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Rename org.bdgenomics.adam.rdd.features package to o.b.a.rdd.feature <a href="https://github.com/bigdatagenomics/adam/pull/1256">#1256</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Clean up documentation in <code>org.bdgenomics.adam.projection</code>. <a href="https://github.com/bigdatagenomics/adam/pull/1255">#1255</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1221] Bump Spark/Hadoop versions. <a href="https://github.com/bigdatagenomics/adam/pull/1254">#1254</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Misc shuffle join fixes. <a href="https://github.com/bigdatagenomics/adam/pull/1253">#1253</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1196] Add support for open ReferenceRegions. <a href="https://github.com/bigdatagenomics/adam/pull/1252">#1252</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1225] Move helper functions from ADAMFunSuite to SparkFunSuite. <a href="https://github.com/bigdatagenomics/adam/pull/1251">#1251</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Merge VariantAnnotation and DatabaseVariantAnnotation records <a href="https://github.com/bigdatagenomics/adam/pull/1250">#1250</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Miscellaneous VCF fixes <a href="https://github.com/bigdatagenomics/adam/pull/1247">#1247</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>HBase backend for Genotypes <a href="https://github.com/bigdatagenomics/adam/pull/1246">#1246</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>[ADAM-1242] Clean up dead code in org.bdgenomics.adam.util. <a href="https://github.com/bigdatagenomics/adam/pull/1243">#1243</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Small cleanup of &ldquo;replacing uses of deprecated class SAMFileReader&rdquo; <a href="https://github.com/bigdatagenomics/adam/pull/1236">#1236</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>replacing uses of deprecated class SAMFileReader <a href="https://github.com/bigdatagenomics/adam/pull/1235">#1235</a> (<a href="https://github.com/lbergelson">lbergelson</a>)</li>
<li>[ADAM-1224] Replace BroadcastRegionJoin with tree based algo. <a href="https://github.com/bigdatagenomics/adam/pull/1234">#1234</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Fix reads2coverage issues <a href="https://github.com/bigdatagenomics/adam/pull/1230">#1230</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1212] Add empty assembly object, allows Maven build to create sources and javadoc artifacts <a href="https://github.com/bigdatagenomics/adam/pull/1215">#1215</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1211] Fix call to move_to_scala_2.sh, reorder Spark 2.x Scala 2.10 and 2.10 sections <a href="https://github.com/bigdatagenomics/adam/pull/1214">#1214</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>demonstrate multi-allelic gVCF failure &ndash; test added <a href="https://github.com/bigdatagenomics/adam/pull/1205">#1205</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>Merge VariantAnnotation and DatabaseVariantAnnotation records <a href="https://github.com/bigdatagenomics/adam/pull/1144">#1144</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Upgrade to bdg-formats-0.10.0 <a href="https://github.com/bigdatagenomics/adam/pull/1135">#1135</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.20.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2016/10/19/adam-0-dot-20-dot-0-release/"/>
    <updated>2016-10-19T12:00:00-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2016/10/19/adam-0-dot-20-dot-0-release</id>
    <content type="html"><![CDATA[<p>ADAM version 0.20.0 has been <a href="https://github.com/bigdatagenomics/adam/releases">released</a>!</p>

<p>Due to major changes between Spark versions 1.6 and 2.0, we now build for combinations of Apache Spark and Scala versions:
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.10-0.20.0">Spark 1.x and Scala 2.10</a>,
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.11-0.20.0">Spark 1.x and Scala 2.11</a>,
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-spark2_2.10-0.20.0">Spark 2.x and Scala 2.10</a>, and
<a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-spark2_2.11-0.20.0">Spark 2.x and Scala 2.11</a>.</p>

<p>Since the last release, version 0.19.0, we have closed more than 180 issues and merged more than 120 pull requests.</p>

<p>We added a new pipe API, allowing for streaming alignment and variant records out to external applications and streaming back
in the results. Several new region join implementations are now public API, including a broadcast inner join, broadcast right
outer join, sort-merge inner join, sort-merge right outer join, sort-merge left outer join, sort-merge full outer join,
sort-merge inner join followed by a group by, and a sort-merge right outer join followed by a group by.</p>

<p>Alignment records can now be read from and written to CRAM format. We updated upstream dependencies on Hadoop-BAM and htsjdk to
fix various alignment record header bugs and to add support for gzip and BGZF compressed VCF.</p>

<p>Our sequence feature schema now more closely follow the GFF3 specification, while still supporting BED, GFF2/GTF, IntervalList,
and NarrowPeak formats. We also added a new sample schema for e.g. SRA sample metadata.</p>

<p>With this version the core ADAM APIs are undergoing a major refactoring. We changed many method names on ADAMContext to make
the API more consistent. We also added RDD wrapper classes to increase performance by serializing metadata (such as record groups,
samples, and sequence dictionaries) to disk separate from primary data in Parquet. API incompatibilities between ADAM releases
will settle down by the 1.0 release, currently targeted for early 2017.</p>

<p>The full list of changes since version 0.19.0 is below.</p>

<!-- more -->


<p><strong>Closed issues:</strong></p>

<ul>
<li>Sorting by reference index seems doesn&rsquo;t work or sorted by DESC order? <a href="https://github.com/bigdatagenomics/adam/issues/1204">#1204</a></li>
<li>master won&rsquo;t compile <a href="https://github.com/bigdatagenomics/adam/issues/1200">#1200</a></li>
<li>VCF format tag SB field parse error in loading <a href="https://github.com/bigdatagenomics/adam/issues/1199">#1199</a></li>
<li>Publish sources JAR with snapshots <a href="https://github.com/bigdatagenomics/adam/issues/1195">#1195</a></li>
<li>Type SparkFunSuite in package org.bdgenomics.utils.misc is not available <a href="https://github.com/bigdatagenomics/adam/issues/1193">#1193</a></li>
<li>MDTagging fails on GRCh38 <a href="https://github.com/bigdatagenomics/adam/issues/1192">#1192</a></li>
<li>Fix stack overflow in IndelRealigner serialization <a href="https://github.com/bigdatagenomics/adam/issues/1190">#1190</a></li>
<li>Delete <code>./scripts/commit-pr.sh</code> <a href="https://github.com/bigdatagenomics/adam/issues/1188">#1188</a></li>
<li>Hadoop globStatus returns null if no glob matches <a href="https://github.com/bigdatagenomics/adam/issues/1186">#1186</a></li>
<li>Swapping out IntervalRDD under GenomicRDDs <a href="https://github.com/bigdatagenomics/adam/issues/1184">#1184</a></li>
<li>How to get &ldquo;SO coordinate&rdquo; instead of &ldquo;SO unsorted&rdquo;? <a href="https://github.com/bigdatagenomics/adam/issues/1182">#1182</a></li>
<li>How to read glob of multiple parquet Genotype <a href="https://github.com/bigdatagenomics/adam/issues/1179">#1179</a></li>
<li>Update command line doc and examples in README.md <a href="https://github.com/bigdatagenomics/adam/issues/1176">#1176</a></li>
<li>FastqRecordConverter needs cleanup and tests <a href="https://github.com/bigdatagenomics/adam/issues/1172">#1172</a></li>
<li>TransformFormats write to .gff3 file path incorrectly writes as parquet <a href="https://github.com/bigdatagenomics/adam/issues/1168">#1168</a></li>
<li>Should be able to merge shards across two different file systems <a href="https://github.com/bigdatagenomics/adam/issues/1165">#1165</a></li>
<li>RG ID gets written as the index, not the record group name <a href="https://github.com/bigdatagenomics/adam/issues/1162">#1162</a></li>
<li>Users should be able to save files as <code>-single</code> without merging them <a href="https://github.com/bigdatagenomics/adam/issues/1161">#1161</a></li>
<li>Users should be able to set size of buffer used for merging files <a href="https://github.com/bigdatagenomics/adam/issues/1160">#1160</a></li>
<li>Bump Hadoop-BAM to 7.7.0 <a href="https://github.com/bigdatagenomics/adam/issues/1158">#1158</a></li>
<li>adam-shell prints command trace to stdout <a href="https://github.com/bigdatagenomics/adam/issues/1154">#1154</a></li>
<li>Map IntervalList format column four to feature name or attributes? <a href="https://github.com/bigdatagenomics/adam/issues/1152">#1152</a></li>
<li>Parquet storage of VariantContext <a href="https://github.com/bigdatagenomics/adam/issues/1151">#1151</a></li>
<li>vcf2adam unparsable vcf record <a href="https://github.com/bigdatagenomics/adam/issues/1149">#1149</a></li>
<li>Reorder kryo.register statements in ADAMKryoRegistrator <a href="https://github.com/bigdatagenomics/adam/issues/1146">#1146</a></li>
<li>Make region joins public again <a href="https://github.com/bigdatagenomics/adam/issues/1143">#1143</a></li>
<li>Support CRAM input/output <a href="https://github.com/bigdatagenomics/adam/issues/1141">#1141</a></li>
<li>Transform should run with spark.kryo.requireRegistration=true <a href="https://github.com/bigdatagenomics/adam/issues/1136">#1136</a></li>
<li>adam-shell not handling bash args correctly <a href="https://github.com/bigdatagenomics/adam/issues/1132">#1132</a></li>
<li>Remove Gene and related models and parsing code <a href="https://github.com/bigdatagenomics/adam/issues/1129">#1129</a></li>
<li>Generate Scoverage reports when running CI <a href="https://github.com/bigdatagenomics/adam/issues/1124">#1124</a></li>
<li>Remove PairingRDD <a href="https://github.com/bigdatagenomics/adam/issues/1122">#1122</a></li>
<li>SAMRecordConverter.convert takes unused arguments <a href="https://github.com/bigdatagenomics/adam/issues/1113">#1113</a></li>
<li>Add Pipe API <a href="https://github.com/bigdatagenomics/adam/issues/1112">#1112</a></li>
<li>Improve coverage in Feature unit tests <a href="https://github.com/bigdatagenomics/adam/issues/1106">#1106</a></li>
<li>K-mer.scala code <a href="https://github.com/bigdatagenomics/adam/issues/1105">#1105</a></li>
<li>add -single file output option to ADAM2Vcf <a href="https://github.com/bigdatagenomics/adam/issues/1102">#1102</a></li>
<li>adam2vcf Fails with Sample not serializable <a href="https://github.com/bigdatagenomics/adam/issues/1100">#1100</a></li>
<li>ReferenceRegion.apply(AlignmentRecord) should not NPE on unmapped reads <a href="https://github.com/bigdatagenomics/adam/issues/1099">#1099</a></li>
<li>Add outer region join implementations <a href="https://github.com/bigdatagenomics/adam/issues/1098">#1098</a></li>
<li>VariantContextConverter never returns DatabaseVariantAnnotation <a href="https://github.com/bigdatagenomics/adam/issues/1097">#1097</a></li>
<li>loadvcf: conflicting require statement <a href="https://github.com/bigdatagenomics/adam/issues/1094">#1094</a></li>
<li>ADAM version 0.19.0 will not run on Spark version 2.0.0 <a href="https://github.com/bigdatagenomics/adam/issues/1093">#1093</a></li>
<li>Be more rigorous with FileSystem.get <a href="https://github.com/bigdatagenomics/adam/issues/1087">#1087</a></li>
<li>Remove network-connected and default test-related Maven profiles <a href="https://github.com/bigdatagenomics/adam/issues/1073">#1073</a></li>
<li>Releases should get pushed to Spark Packages <a href="https://github.com/bigdatagenomics/adam/issues/1067">#1067</a></li>
<li>Invalid POM for cli on 0.19.0 <a href="https://github.com/bigdatagenomics/adam/issues/1066">#1066</a></li>
<li>scala.MatchError RegExp does not catch colons in value part properly <a href="https://github.com/bigdatagenomics/adam/issues/1061">#1061</a></li>
<li>Support writing IntervalList header for features <a href="https://github.com/bigdatagenomics/adam/issues/1059">#1059</a></li>
<li>Add -single support when writing features in native formats <a href="https://github.com/bigdatagenomics/adam/issues/1058">#1058</a></li>
<li>Remove workaround for gzip/BGZF compressed VCF headers <a href="https://github.com/bigdatagenomics/adam/issues/1057">#1057</a></li>
<li>Clean up if clauses in Transform <a href="https://github.com/bigdatagenomics/adam/issues/1053">#1053</a></li>
<li>Adam-0.18.2 can not load Adam-0.14.0 adamSave function data (sam) <a href="https://github.com/bigdatagenomics/adam/issues/1050">#1050</a></li>
<li>filterByOverlappingRegion Incorrect for Genotypes <a href="https://github.com/bigdatagenomics/adam/issues/1042">#1042</a></li>
<li>Move Interval trait to utils, added in #75 <a href="https://github.com/bigdatagenomics/adam/issues/1041">#1041</a></li>
<li>Remove implicit GenomicRDD to RDD conversion <a href="https://github.com/bigdatagenomics/adam/issues/1040">#1040</a></li>
<li>VCF sample metadata &ndash; proposal for a GenotypedSampleMetadata object <a href="https://github.com/bigdatagenomics/adam/issues/1039">#1039</a></li>
<li>[build system] ADAM test builds pollute /tmp, leaving lots of cruft&hellip; <a href="https://github.com/bigdatagenomics/adam/issues/1038">#1038</a></li>
<li>adamMarkDuplicates function in AlignmentRecordRDDFunctions class can not mark the same read? <a href="https://github.com/bigdatagenomics/adam/issues/1037">#1037</a></li>
<li>test MarkDuplicatesSuite with two similar read in ref and start position and different avgPhredScore, error! <a href="https://github.com/bigdatagenomics/adam/issues/1035">#1035</a></li>
<li>Explore protocol buffers vs Avro <a href="https://github.com/bigdatagenomics/adam/issues/1031">#1031</a></li>
<li>Increase Avro dependency version to 1.8.0 <a href="https://github.com/bigdatagenomics/adam/issues/1029">#1029</a></li>
<li>ADAM specific logging <a href="https://github.com/bigdatagenomics/adam/issues/1024">#1024</a></li>
<li>Reenable Travis CI for pull request builds <a href="https://github.com/bigdatagenomics/adam/issues/1023">#1023</a></li>
<li>Bump Apache Spark version to 1.6.1 in Jenkins <a href="https://github.com/bigdatagenomics/adam/issues/1022">#1022</a></li>
<li>ADAM compatibility with Spark 2.0 <a href="https://github.com/bigdatagenomics/adam/issues/1021">#1021</a></li>
<li>ADAM to BAM conversion failing on 1000G file <a href="https://github.com/bigdatagenomics/adam/issues/1013">#1013</a></li>
<li>Factor out *RDDFunctions classes <a href="https://github.com/bigdatagenomics/adam/issues/1011">#1011</a></li>
<li>Port single file BAM and header code to VCF <a href="https://github.com/bigdatagenomics/adam/issues/1009">#1009</a></li>
<li>Roll Jenkins JDK 8 changes into ./scripts/jenkins-test <a href="https://github.com/bigdatagenomics/adam/issues/1008">#1008</a></li>
<li>Support GFF3 format <a href="https://github.com/bigdatagenomics/adam/issues/1007">#1007</a></li>
<li>Separate fat jar build from adam-cli to new maven module <a href="https://github.com/bigdatagenomics/adam/issues/1006">#1006</a></li>
<li>adam-cli POM invalid: maven.build.timestamp <a href="https://github.com/bigdatagenomics/adam/issues/1004">#1004</a></li>
<li>Sub-partitioning of Parquet file for ADAM <a href="https://github.com/bigdatagenomics/adam/issues/1003">#1003</a></li>
<li>Flattening the Genotype schema <a href="https://github.com/bigdatagenomics/adam/issues/1002">#1002</a></li>
<li>install adam 0.19 error! <a href="https://github.com/bigdatagenomics/adam/issues/1001">#1001</a></li>
<li>How to solve it please? <a href="https://github.com/bigdatagenomics/adam/issues/1000">#1000</a></li>
<li>Has the project realized alignment reads to reference genome algorithm? <a href="https://github.com/bigdatagenomics/adam/issues/996">#996</a></li>
<li>All file-based input methods should support running on directories, compressed files, and wildcards <a href="https://github.com/bigdatagenomics/adam/issues/993">#993</a></li>
<li>Contig to ContigName Change not reflected in AlignmentRecordField <a href="https://github.com/bigdatagenomics/adam/issues/991">#991</a></li>
<li>Add homebrew guidelines to release checklist or automate PR generation <a href="https://github.com/bigdatagenomics/adam/issues/987">#987</a></li>
<li>fix deprecation warnings <a href="https://github.com/bigdatagenomics/adam/issues/985">#985</a></li>
<li>rename <code>fragments</code> package <a href="https://github.com/bigdatagenomics/adam/issues/984">#984</a></li>
<li>Explore if SeqDict data can be factored out more aggressively <a href="https://github.com/bigdatagenomics/adam/issues/983">#983</a></li>
<li>Make &ldquo;Adam&rdquo; all caps in filename Adam2Fastq.scala <a href="https://github.com/bigdatagenomics/adam/issues/981">#981</a></li>
<li>Adam2Fastq should output reverse complement when 0x10 flag is set for read <a href="https://github.com/bigdatagenomics/adam/issues/980">#980</a></li>
<li>Allow lowercase letters in jar/version names <a href="https://github.com/bigdatagenomics/adam/issues/974">#974</a></li>
<li>Add stringency parameter to flagstat <a href="https://github.com/bigdatagenomics/adam/issues/973">#973</a></li>
<li>Arg-array parsing problem in adam-submit <a href="https://github.com/bigdatagenomics/adam/issues/971">#971</a></li>
<li>Pass recordGroup parameter to loadPairedFastq <a href="https://github.com/bigdatagenomics/adam/issues/969">#969</a></li>
<li>Send a number of partitions to sc.textFile calls <a href="https://github.com/bigdatagenomics/adam/issues/968">#968</a></li>
<li>adamGetReferenceString doesn&rsquo;t reduce pairs correctly <a href="https://github.com/bigdatagenomics/adam/issues/967">#967</a></li>
<li>Update ADAM formula in homebrew-science to version 0.19.0 <a href="https://github.com/bigdatagenomics/adam/issues/963">#963</a></li>
<li>BAM output in ADAM appears to be corrupt <a href="https://github.com/bigdatagenomics/adam/issues/962">#962</a></li>
<li>Remove code workarounds necessary for Spark 1.2.1/Hadoop 1.0.x support <a href="https://github.com/bigdatagenomics/adam/issues/959">#959</a></li>
<li>Issue with version 18.0.2 <a href="https://github.com/bigdatagenomics/adam/issues/957">#957</a></li>
<li>Expose sorting by reference index <a href="https://github.com/bigdatagenomics/adam/issues/952">#952</a></li>
<li>.rgdict and .seqdict files are not placed in the adam directory <a href="https://github.com/bigdatagenomics/adam/issues/945">#945</a></li>
<li>Why does count_kmers not return k-mers that are split between two records? <a href="https://github.com/bigdatagenomics/adam/issues/930">#930</a></li>
<li>Load legacy file formats to Spark SQL Dataframes <a href="https://github.com/bigdatagenomics/adam/issues/912">#912</a></li>
<li>Clean up RDD method names <a href="https://github.com/bigdatagenomics/adam/issues/910">#910</a></li>
<li>Load/store sequence dictionaries alongside Genotype RDDs <a href="https://github.com/bigdatagenomics/adam/issues/909">#909</a></li>
<li>vcf2adam -print_metrics throws IllegalStateException on Spark 1.5.2 or later <a href="https://github.com/bigdatagenomics/adam/issues/902">#902</a></li>
<li>error: no reads in first split: bad BAM file or tiny split size? <a href="https://github.com/bigdatagenomics/adam/issues/896">#896</a></li>
<li>FastaConverter.FastaDescriptionLine not kryo-registered <a href="https://github.com/bigdatagenomics/adam/issues/893">#893</a></li>
<li>Work With ADAM fasta2adam in a distributed mode <a href="https://github.com/bigdatagenomics/adam/issues/881">#881</a></li>
<li>vcf2adam &ndash;> Exception in thread &ldquo;main&rdquo; java.lang.NoSuchMethodError: scala.Predef$.$conforms()Lscala/Predef$$less$colon$less; <a href="https://github.com/bigdatagenomics/adam/issues/871">#871</a></li>
<li>Code coverage profile is broken <a href="https://github.com/bigdatagenomics/adam/issues/849">#849</a></li>
<li>Building Adam on OS X 10.10.5 with Java 1.8 <a href="https://github.com/bigdatagenomics/adam/issues/835">#835</a></li>
<li>Normalize AlignmentRecord.recordGroup* fields onto a separate record type <a href="https://github.com/bigdatagenomics/adam/issues/828">#828</a></li>
<li>Gracefully handle missing Spark- and Hadoop-versions in jenkins-test; document how to set them. <a href="https://github.com/bigdatagenomics/adam/issues/827">#827</a></li>
<li>Use Adam File with Hive <a href="https://github.com/bigdatagenomics/adam/issues/820">#820</a></li>
<li>How do we handle reads that don&rsquo;t have original quality scores when converting to FASTQ with original qualities? <a href="https://github.com/bigdatagenomics/adam/issues/818">#818</a></li>
<li>SAMFileHeader &ldquo;sort order&rdquo; attribute being un-set during file-save job <a href="https://github.com/bigdatagenomics/adam/issues/800">#800</a></li>
<li>Use same sort order as Samtools <a href="https://github.com/bigdatagenomics/adam/issues/796">#796</a></li>
<li>RNAME and RNEXT fields jumbled on transform BAM->ADAM->BAM <a href="https://github.com/bigdatagenomics/adam/issues/795">#795</a></li>
<li>Support loading multiple indexed read files <a href="https://github.com/bigdatagenomics/adam/issues/787">#787</a></li>
<li>Duplicate OUTPUT command line argument metaVar in adam2fastq <a href="https://github.com/bigdatagenomics/adam/issues/776">#776</a></li>
<li>Allow Variant to ReferenceRegion conversion <a href="https://github.com/bigdatagenomics/adam/issues/768">#768</a></li>
<li>Spark Errors References Deprecated SPARK_CLASSPATH <a href="https://github.com/bigdatagenomics/adam/issues/767">#767</a></li>
<li>Spark Errors References Deprecated SPARK_CLASSPATH <a href="https://github.com/bigdatagenomics/adam/issues/766">#766</a></li>
<li>adam2vcf fails with -coalesce <a href="https://github.com/bigdatagenomics/adam/issues/735">#735</a></li>
<li>Writing to a BAM file with adamSAMSave consistently fails <a href="https://github.com/bigdatagenomics/adam/issues/721">#721</a></li>
<li>BQSR on C835.HCC1143_BL.4 uses excessive amount of driver memory <a href="https://github.com/bigdatagenomics/adam/issues/714">#714</a></li>
<li>Support writing RDD[Feature] to various file formats <a href="https://github.com/bigdatagenomics/adam/issues/710">#710</a></li>
<li>adamParquetSave has a menacing false error message about *.adam extension <a href="https://github.com/bigdatagenomics/adam/issues/681">#681</a></li>
<li>BAMHeader not set when running on a cluster <a href="https://github.com/bigdatagenomics/adam/issues/676">#676</a></li>
<li>spark 1.3.1 upgarde to hortonworks HDP 2.2.4.2-2? <a href="https://github.com/bigdatagenomics/adam/issues/675">#675</a></li>
<li><code>Symbol</code> case class is nucleotide-centric <a href="https://github.com/bigdatagenomics/adam/issues/672">#672</a></li>
<li>xAssembler cannot be build using mvn <a href="https://github.com/bigdatagenomics/adam/issues/658">#658</a></li>
<li>adam-submit VerifyError <a href="https://github.com/bigdatagenomics/adam/issues/642">#642</a></li>
<li>vcf2adam : Unsupported type ENUM <a href="https://github.com/bigdatagenomics/adam/issues/638">#638</a></li>
<li>Update CDH documentation <a href="https://github.com/bigdatagenomics/adam/issues/615">#615</a></li>
<li>Remove and generalize plugin code <a href="https://github.com/bigdatagenomics/adam/issues/602">#602</a></li>
<li>Fix record oriented shuffle <a href="https://github.com/bigdatagenomics/adam/issues/599">#599</a></li>
<li>Migrate preprocessing stages out of ADAM <a href="https://github.com/bigdatagenomics/adam/issues/598">#598</a></li>
<li>Publish/socialize a roadmap <a href="https://github.com/bigdatagenomics/adam/issues/591">#591</a></li>
<li>Eliminate format detection and extension checks for loading data <a href="https://github.com/bigdatagenomics/adam/issues/587">#587</a></li>
<li>Improve error message when we can&rsquo;t find a ReferenceRegion for a contig <a href="https://github.com/bigdatagenomics/adam/issues/582">#582</a></li>
<li>Do reference partitioners restrict a partition to contain keys from a single contig? <a href="https://github.com/bigdatagenomics/adam/issues/573">#573</a></li>
<li>Connection refused errors when transforming BAM file with BQSR <a href="https://github.com/bigdatagenomics/adam/issues/516">#516</a></li>
<li>ReferenceRegion shouldn&rsquo;t extend Ordered <a href="https://github.com/bigdatagenomics/adam/issues/511">#511</a></li>
<li>Documentation for common usecases <a href="https://github.com/bigdatagenomics/adam/issues/491">#491</a></li>
<li>Improve handling of &ldquo;*&rdquo; sequences during BQSR <a href="https://github.com/bigdatagenomics/adam/issues/484">#484</a></li>
<li>Original qualities are parsed out, but left in attribute fields <a href="https://github.com/bigdatagenomics/adam/issues/483">#483</a></li>
<li>Need a FileLocator that mirrors the use of Path in HDFS <a href="https://github.com/bigdatagenomics/adam/issues/477">#477</a></li>
<li>FileLocator should support finding &ldquo;child&rdquo; locators. <a href="https://github.com/bigdatagenomics/adam/issues/476">#476</a></li>
<li>Add S3 based Parquet directory loader <a href="https://github.com/bigdatagenomics/adam/issues/463">#463</a></li>
<li>Should FASTQ output use reads&#8217; &ldquo;original qualities&rdquo;? <a href="https://github.com/bigdatagenomics/adam/issues/436">#436</a></li>
<li>VcfStringUtils unused? <a href="https://github.com/bigdatagenomics/adam/issues/428">#428</a></li>
<li>We should be able to filter genotypes that overlap a region <a href="https://github.com/bigdatagenomics/adam/issues/422">#422</a></li>
<li>Create a simplified vocabulary for naming projections. <a href="https://github.com/bigdatagenomics/adam/issues/419">#419</a></li>
<li>Update documentation <a href="https://github.com/bigdatagenomics/adam/issues/406">#406</a></li>
<li>Bake off different region join implementations <a href="https://github.com/bigdatagenomics/adam/issues/395">#395</a></li>
<li>Handle no-ops more intelligently when creating MD tags <a href="https://github.com/bigdatagenomics/adam/issues/392">#392</a></li>
<li>Remove all the commands in the &ldquo;CONVERSION OPERATIONS&rdquo; <code>CommandGroup</code> <a href="https://github.com/bigdatagenomics/adam/issues/373">#373</a></li>
<li>Fail to Write RDD into HDFS with Parquet Format <a href="https://github.com/bigdatagenomics/adam/issues/344">#344</a></li>
<li>Refactor ReferencePositionWithOrientation <a href="https://github.com/bigdatagenomics/adam/issues/317">#317</a></li>
<li>Add docs about SPARK_LOCAL_IP <a href="https://github.com/bigdatagenomics/adam/issues/305">#305</a></li>
<li>PartitionAndJoin should throw an exception if it sees an unmapped read <a href="https://github.com/bigdatagenomics/adam/issues/297">#297</a></li>
<li>Add insert size calculation <a href="https://github.com/bigdatagenomics/adam/issues/296">#296</a></li>
<li>Newbie questions &ndash; learning resources? Reading a range of records from Adam? <a href="https://github.com/bigdatagenomics/adam/issues/281">#281</a></li>
<li>Add variant effect ontology <a href="https://github.com/bigdatagenomics/adam/issues/261">#261</a></li>
<li>Don&rsquo;t flatten optional SAM tags into a string <a href="https://github.com/bigdatagenomics/adam/issues/240">#240</a></li>
<li>Characterize impact of partition size on pileup creation <a href="https://github.com/bigdatagenomics/adam/issues/163">#163</a></li>
<li>Need to support BCF output format <a href="https://github.com/bigdatagenomics/adam/issues/153">#153</a></li>
<li>Allow list of commands to be injected into adam-cli AdamMain <a href="https://github.com/bigdatagenomics/adam/issues/132">#132</a></li>
<li>Parse out common annotations stored in VCF format <a href="https://github.com/bigdatagenomics/adam/issues/118">#118</a></li>
<li>Update normalization code to enable normalization of sequences with more than two indels <a href="https://github.com/bigdatagenomics/adam/issues/64">#64</a></li>
<li>Add clipping heuristic to indel realigner <a href="https://github.com/bigdatagenomics/adam/issues/63">#63</a></li>
<li>BQSR should support recalibration across multiple ADAM files <a href="https://github.com/bigdatagenomics/adam/issues/58">#58</a></li>
</ul>


<p><strong>Merged and closed pull requests:</strong></p>

<ul>
<li>fix SB tag parsing <a href="https://github.com/bigdatagenomics/adam/pull/1209">#1209</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Fastq record converter <a href="https://github.com/bigdatagenomics/adam/pull/1208">#1208</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Doc suggested partitionSize in ShuffleRegionJoin <a href="https://github.com/bigdatagenomics/adam/pull/1207">#1207</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>Test demonstrating region join failure <a href="https://github.com/bigdatagenomics/adam/pull/1206">#1206</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>fix SB tag parsing <a href="https://github.com/bigdatagenomics/adam/pull/1203">#1203</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>fix build <a href="https://github.com/bigdatagenomics/adam/pull/1201">#1201</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>[ADAM-1192] Correctly handle other whitespace in FASTA description. <a href="https://github.com/bigdatagenomics/adam/pull/1198">#1198</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1190] Manually (un)pack IndelRealignmentTarget set. <a href="https://github.com/bigdatagenomics/adam/pull/1191">#1191</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1188] Delete scripts/commit-pr.sh <a href="https://github.com/bigdatagenomics/adam/pull/1189">#1189</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1186] Mask null from fs.globStatus. <a href="https://github.com/bigdatagenomics/adam/pull/1187">#1187</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Fastq record converter <a href="https://github.com/bigdatagenomics/adam/pull/1185">#1185</a> (<a href="https://github.com/zyxue">zyxue</a>)</li>
<li>[ADAM-1182] isSorted=true should write SO:coordinate in SAM/BAM/CRAM header. <a href="https://github.com/bigdatagenomics/adam/pull/1183">#1183</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add scoverage aggregator and fail on low coverage. <a href="https://github.com/bigdatagenomics/adam/pull/1181">#1181</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1179] Improve error message when globbing a parquet file fails. <a href="https://github.com/bigdatagenomics/adam/pull/1180">#1180</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1176] Update command line doc and examples in README.md <a href="https://github.com/bigdatagenomics/adam/pull/1177">#1177</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Refactor CLIs for merging sharded files <a href="https://github.com/bigdatagenomics/adam/pull/1167">#1167</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Update Hadoop-BAM to version 7.7.0 <a href="https://github.com/bigdatagenomics/adam/pull/1166">#1166</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1162] Write record group string name. <a href="https://github.com/bigdatagenomics/adam/pull/1163">#1163</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Map IntervalList format column four to feature name <a href="https://github.com/bigdatagenomics/adam/pull/1159">#1159</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Make AlignmentRecordConverter public so that it can be used from other projects <a href="https://github.com/bigdatagenomics/adam/pull/1157">#1157</a> (<a href="https://github.com/tomwhite">tomwhite</a>)</li>
<li>added predicate option to loadCoverage <a href="https://github.com/bigdatagenomics/adam/pull/1156">#1156</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1154] Change set -x to set -e in ./bin/adam-shell. <a href="https://github.com/bigdatagenomics/adam/pull/1155">#1155</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Remove Gene and related models and parsing code <a href="https://github.com/bigdatagenomics/adam/pull/1153">#1153</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Reorder kryo.register statements in ADAMKryoRegistrator <a href="https://github.com/bigdatagenomics/adam/pull/1148">#1148</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Updated GenomicPartitioners to accept additional key. <a href="https://github.com/bigdatagenomics/adam/pull/1147">#1147</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1141] Add support for saving/loading AlignmentRecords to/from CRAM. <a href="https://github.com/bigdatagenomics/adam/pull/1145">#1145</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>misc pom/test/resource improvements <a href="https://github.com/bigdatagenomics/adam/pull/1142">#1142</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>[ADAM-1136] Transform runs successfully with kryo registration required <a href="https://github.com/bigdatagenomics/adam/pull/1138">#1138</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1132] Fix improper quoting of bash args in adam-shell. <a href="https://github.com/bigdatagenomics/adam/pull/1133">#1133</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Remove StructuralVariant and StructuralVariantType, add names field to Variant <a href="https://github.com/bigdatagenomics/adam/pull/1131">#1131</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Remove StructuralVariant and StructuralVariantType, add names field to Variant <a href="https://github.com/bigdatagenomics/adam/pull/1130">#1130</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>PR #1108 with issue #1122 <a href="https://github.com/bigdatagenomics/adam/pull/1128">#1128</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1038] Eliminate writing to /tmp during CI builds. <a href="https://github.com/bigdatagenomics/adam/pull/1127">#1127</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Update for bdg-formats code style changes <a href="https://github.com/bigdatagenomics/adam/pull/1126">#1126</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1124] Add Scoverage and generate coverage reports in Jenkins. <a href="https://github.com/bigdatagenomics/adam/pull/1125">#1125</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1093] Move to support Spark 2.0.0. <a href="https://github.com/bigdatagenomics/adam/pull/1123">#1123</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>remove duplicated dependency <a href="https://github.com/bigdatagenomics/adam/pull/1119">#1119</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>Clean up ADAMContext <a href="https://github.com/bigdatagenomics/adam/pull/1118">#1118</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-993] Support loading files using globs and from directory paths. <a href="https://github.com/bigdatagenomics/adam/pull/1117">#1117</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1087] Migrate away from FileSystem.get <a href="https://github.com/bigdatagenomics/adam/pull/1116">#1116</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1099] Make reference region not throw NPE. <a href="https://github.com/bigdatagenomics/adam/pull/1115">#1115</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add pipes API <a href="https://github.com/bigdatagenomics/adam/pull/1114">#1114</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1105] Use assembly jar in adam-shell. <a href="https://github.com/bigdatagenomics/adam/pull/1111">#1111</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add outer joins <a href="https://github.com/bigdatagenomics/adam/pull/1109">#1109</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Modified CalculateDepth to calcuate coverage from alignment files <a href="https://github.com/bigdatagenomics/adam/pull/1108">#1108</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Resolves various single file save/header issues <a href="https://github.com/bigdatagenomics/adam/pull/1104">#1104</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1100] Resolve Sample Not Serializable exception <a href="https://github.com/bigdatagenomics/adam/pull/1101">#1101</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>added loadIndexedVcf and loadIndexedBam for multiple ReferenceRegions <a href="https://github.com/bigdatagenomics/adam/pull/1096">#1096</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Added support for Indexed VCF files <a href="https://github.com/bigdatagenomics/adam/pull/1095">#1095</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-582] Eliminate .get on option in FragmentCoverter. <a href="https://github.com/bigdatagenomics/adam/pull/1091">#1091</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-776] Rename duplicate OUTPUT metaVar in ADAM2Fastq. <a href="https://github.com/bigdatagenomics/adam/pull/1090">#1090</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>refactored ReferenceFile to require SequenceDictionary <a href="https://github.com/bigdatagenomics/adam/pull/1086">#1086</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1073] Remove network-connected and default test-related Maven profiles <a href="https://github.com/bigdatagenomics/adam/pull/1082">#1082</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1053] Clean up Transform <a href="https://github.com/bigdatagenomics/adam/pull/1081">#1081</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1061] Clean up attributes regex and denormalized fields <a href="https://github.com/bigdatagenomics/adam/pull/1080">#1080</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Extended TwoBitFile and NucleotideContigFragmentRDDFunctions to behave more similar <a href="https://github.com/bigdatagenomics/adam/pull/1079">#1079</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Refactor variant and genotype annotations <a href="https://github.com/bigdatagenomics/adam/pull/1078">#1078</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1039] Add basic support for Sample record. <a href="https://github.com/bigdatagenomics/adam/pull/1077">#1077</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Remove code workarounds necessary for Spark 1.2.1/Hadoop 1.0.x support <a href="https://github.com/bigdatagenomics/adam/pull/1076">#1076</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-194] Use separate filtersFailed and filtersPassed arrays for variant quality filters <a href="https://github.com/bigdatagenomics/adam/pull/1075">#1075</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Whitespace code style fixes <a href="https://github.com/bigdatagenomics/adam/pull/1074">#1074</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1006] Split überjar out to adam-assembly submodule. <a href="https://github.com/bigdatagenomics/adam/pull/1072">#1072</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Remove code coverage profile <a href="https://github.com/bigdatagenomics/adam/pull/1071">#1071</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-768] ReferenceRegion from variant/genotypes <a href="https://github.com/bigdatagenomics/adam/pull/1070">#1070</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1044] Support VCF annotation ANN field <a href="https://github.com/bigdatagenomics/adam/pull/1069">#1069</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-1067] Add release documentation and scripting for Spark Packages. <a href="https://github.com/bigdatagenomics/adam/pull/1068">#1068</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-602] Remove plugin code. <a href="https://github.com/bigdatagenomics/adam/pull/1065">#1065</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Refactoring <code>org.bdgenomics.adam.io</code> package. <a href="https://github.com/bigdatagenomics/adam/pull/1064">#1064</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Cleanup in org.bdgenomics.adam.converters package. <a href="https://github.com/bigdatagenomics/adam/pull/1062">#1062</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1057] Remove workaround for gzip/BGZF compressed VCF headers <a href="https://github.com/bigdatagenomics/adam/pull/1057">#1057</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Cleanup on <code>org.bdgenomics.adam.algorithms.smithwaterman</code> package. <a href="https://github.com/bigdatagenomics/adam/pull/1056">#1056</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Documentation cleanup and minor refactor on the consensus package. <a href="https://github.com/bigdatagenomics/adam/pull/1055">#1055</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Add KEYS with public code signing keys <a href="https://github.com/bigdatagenomics/adam/pull/1054">#1054</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Adding GA4GH 0.5.1 converter for reads. <a href="https://github.com/bigdatagenomics/adam/pull/1052">#1052</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-1011] Refactor to add GenomicRDDs for all Avro types <a href="https://github.com/bigdatagenomics/adam/pull/1051">#1051</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>removed interval trait and redirected to interval in utils-intervalrdd <a href="https://github.com/bigdatagenomics/adam/pull/1046">#1046</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-952] Expose sorting by reference index. <a href="https://github.com/bigdatagenomics/adam/pull/1045">#1045</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>overlap query reflects new formats <a href="https://github.com/bigdatagenomics/adam/pull/1043">#1043</a> (<a href="https://github.com/erictu">erictu</a>)</li>
<li>Changed loadIndexedBam to use hadoop-bam InputFormat <a href="https://github.com/bigdatagenomics/adam/pull/1036">#1036</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Increase Avro dependency version to 1.8.0 <a href="https://github.com/bigdatagenomics/adam/pull/1034">#1034</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Improved README fix using feedback from other approach review. <a href="https://github.com/bigdatagenomics/adam/pull/1034">#1034</a> (<a href="https://github.com/InvisibleTech">InvisibleTech</a>)</li>
<li>Error in the README.md for kmer.scala example, need to get rdd first. <a href="https://github.com/bigdatagenomics/adam/pull/1032">#1032</a> (<a href="https://github.com/InvisibleTech">InvisibleTech</a>)</li>
<li>Add fragmentEndPosition to NucleotideContigFragment <a href="https://github.com/bigdatagenomics/adam/pull/1030">#1030</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Logging to be done by ADAM utils code rather than Spark <a href="https://github.com/bigdatagenomics/adam/pull/1028">#1028</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>add maxScore <a href="https://github.com/bigdatagenomics/adam/pull/1027">#1027</a> (<a href="https://github.com/xubo245">xubo245</a>)</li>
<li>[ADAM-1008] Modify jenkins-test script to support Java 8 build. <a href="https://github.com/bigdatagenomics/adam/pull/1026">#1026</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>whitespace change, do not merge <a href="https://github.com/bigdatagenomics/adam/pull/1025">#1025</a> (<a href="https://github.com/shaneknapp">shaneknapp</a>)</li>
<li>require kryo registration in tests <a href="https://github.com/bigdatagenomics/adam/pull/1020">#1020</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>print full stack traces on test failures <a href="https://github.com/bigdatagenomics/adam/pull/1019">#1019</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>bump commons-io version <a href="https://github.com/bigdatagenomics/adam/pull/1017">#1017</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>exclude javadoc jar in adam-shell <a href="https://github.com/bigdatagenomics/adam/pull/1016">#1016</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>[ADAM-909] Refactoring variation RDDs. <a href="https://github.com/bigdatagenomics/adam/pull/1015">#1015</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Modified CalculateDepth to get coverage on whole alignment adam files <a href="https://github.com/bigdatagenomics/adam/pull/1010">#1010</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>[ADAM-1004] Remove recursive maven.build.timestamp declaration <a href="https://github.com/bigdatagenomics/adam/pull/1005">#1005</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Maint 2.11 0.19.0 <a href="https://github.com/bigdatagenomics/adam/pull/999">#999</a> (<a href="https://github.com/tushu1232">tushu1232</a>)</li>
<li>[ADAM-710] Add saveAs methods for feature formats GTF, BED, IntervalList, and NarrowPeak <a href="https://github.com/bigdatagenomics/adam/pull/998">#998</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Moving Adam2Fastq to ADAM2Fastq <a href="https://github.com/bigdatagenomics/adam/pull/995">#995</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Update release doc for CHANGES.md and homebrew <a href="https://github.com/bigdatagenomics/adam/pull/994">#994</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Update to AlignmentRecordField and its usages as contig changed to co… <a href="https://github.com/bigdatagenomics/adam/pull/992">#992</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>[ADAM-974] Short term fix for multiple ADAM cli assembly jars check <a href="https://github.com/bigdatagenomics/adam/pull/990">#990</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Update hadoop-bam dependency version to 7.5.0 <a href="https://github.com/bigdatagenomics/adam/pull/989">#989</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Replaced Contig with ContigName in AlignmentRecord and related changes <a href="https://github.com/bigdatagenomics/adam/pull/988">#988</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>fix some deprecation/style things and rename a pkg <a href="https://github.com/bigdatagenomics/adam/pull/986">#986</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>Fix Adam2fastq in case of read with both reverse and unmapped flags <a href="https://github.com/bigdatagenomics/adam/pull/982">#982</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>[ADAM-510] Refactoring RDD function names <a href="https://github.com/bigdatagenomics/adam/pull/979">#979</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Use .adam/_{seq,rg}dict.avro paths for Avro-formatted dictionaries <a href="https://github.com/bigdatagenomics/adam/pull/978">#978</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Remove unused file VcfHeaderUtils.scala <a href="https://github.com/bigdatagenomics/adam/pull/977">#977</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>add validation stringency to bam parsing, flagstat <a href="https://github.com/bigdatagenomics/adam/pull/976">#976</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>more permissible jar regex in adam-submit <a href="https://github.com/bigdatagenomics/adam/pull/975">#975</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>fix bash arg array processing in adam-submit <a href="https://github.com/bigdatagenomics/adam/pull/972">#972</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>adamGetReferenceString reduces pairs correctly, fixes #967 <a href="https://github.com/bigdatagenomics/adam/pull/970">#970</a> (<a href="https://github.com/erictu">erictu</a>)</li>
<li>A few improvements <a href="https://github.com/bigdatagenomics/adam/pull/966">#966</a> (<a href="https://github.com/ryan-williams">ryan-williams</a>)</li>
<li>improve SW performance by replacing functional reductions with imperative ones <a href="https://github.com/bigdatagenomics/adam/pull/965">#965</a> (<a href="https://github.com/noamBarkai">noamBarkai</a>)</li>
<li>[ADAM-962] Fix corrupt single-file BAM output. <a href="https://github.com/bigdatagenomics/adam/pull/964">#964</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-960] Updating bdg-utils dependency version to 0.2.4 <a href="https://github.com/bigdatagenomics/adam/pull/961">#961</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-946] Fixes to FlagStat for Samtools concordance issue <a href="https://github.com/bigdatagenomics/adam/pull/954">#954</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>Use hadoop-bam BAMInputFormat to do loadIndexedBam <a href="https://github.com/bigdatagenomics/adam/pull/953">#953</a> (<a href="https://github.com/andrewmchen">andrewmchen</a>)</li>
<li>Add -print_metrics option to Jenkins build <a href="https://github.com/bigdatagenomics/adam/pull/947">#947</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>adam2vcf doesn&rsquo;t have info fields <a href="https://github.com/bigdatagenomics/adam/pull/939">#939</a> (<a href="https://github.com/andrewmchen">andrewmchen</a>)</li>
<li>[ADAM-893] Register missing serializers. <a href="https://github.com/bigdatagenomics/adam/pull/933">#933</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.19.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2016/02/25/adam-0-dot-19-dot-0-release/"/>
    <updated>2016-02-25T11:00:00-08:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2016/02/25/adam-0-dot-19-dot-0-release</id>
    <content type="html"><![CDATA[<p>ADAM version 0.19.0 has been <a href="https://github.com/bigdatagenomics/adam/releases">released</a>, built for both <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.10-0.19.0">Scala 2.10</a> and <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.11-0.19.0">Scala 2.11</a>.</p>

<p>The 0.19.0 release contains various concordance fixes and performance improvements for accessing read metadata.  Schema changes, including a bump to version 0.7.0 of the Big Data Genomics <a href="https://github.com/bigdatagenomics/bdg-formats/releases/tag/bdg-formats-0.7.0">Avro data formats</a>, were made to support the read metadata performance improvements.  Additionally, the performance of exporting a single BAM file was improved, and this was made to be guaranteed correct for sorted data.</p>

<p>ADAM now targets Apache Spark 1.5.2 and Apache Hadoop 2.6.0 as the default build environment.  ADAM and applications built on ADAM should run on a wide range of Apache Spark (1.3.1 up to and including the most recent, 1.6.0) and Apache Hadoop (currently 2.3.0 and 2.6.0) versions.  A compatibility matrix of Spark, Hadoop, and Scala version builds in our <a href="https://amplab.cs.berkeley.edu/jenkins/view/Big%20Data%20Genomics/">continuous integration system</a> verifies this.  Please note, as of this release, support for Apache Spark 1.2.x and Apache Hadoop 1.0.x <a href="https://github.com/bigdatagenomics/adam/issues/958">has been dropped</a>.</p>

<p>The full list of changes since version 0.18.2 is below.</p>

<!-- more -->


<p><strong>Closed issues:</strong></p>

<ul>
<li>Update bdg-utils dependency version to 0.2.4 <a href="https://github.com/bigdatagenomics/adam/issues/960">#960</a></li>
<li>Drop support for Spark version 1.2.1, Hadoop version 1.0.x <a href="https://github.com/bigdatagenomics/adam/issues/958">#958</a></li>
<li>Exception occurs when running tests on master <a href="https://github.com/bigdatagenomics/adam/issues/956">#956</a></li>
<li>Flagstat results still don&rsquo;t match samtools flagstat <a href="https://github.com/bigdatagenomics/adam/issues/946">#946</a></li>
<li>readInFragment value is not properly read from parquet file into RDD[AlignmentRecord] <a href="https://github.com/bigdatagenomics/adam/issues/942">#942</a></li>
<li>adam2vcf -sort_on_save flag broken <a href="https://github.com/bigdatagenomics/adam/issues/940">#940</a></li>
<li>Transform -limit_projection requires .sam.seqdict file <a href="https://github.com/bigdatagenomics/adam/issues/937">#937</a></li>
<li>MarkDuplicates fails if library name is not set <a href="https://github.com/bigdatagenomics/adam/issues/934">#934</a></li>
<li>fastqtobam or sam <a href="https://github.com/bigdatagenomics/adam/issues/928">#928</a></li>
<li>Vcf2Adam uses SB field instead of FS field for fisher exact test for strand bias <a href="https://github.com/bigdatagenomics/adam/issues/923">#923</a></li>
<li>Add back limit_projection on Transform <a href="https://github.com/bigdatagenomics/adam/issues/920">#920</a></li>
<li>BAM header is not getting set on partition 0 with headerless BAM output format <a href="https://github.com/bigdatagenomics/adam/issues/916">#916</a></li>
<li>Add numParts apply method to GenomicRegionPartitioner <a href="https://github.com/bigdatagenomics/adam/issues/914">#914</a></li>
<li>Add Spark version 1.6.x to Jenkins build matrix <a href="https://github.com/bigdatagenomics/adam/issues/913">#913</a></li>
<li>Target Spark 1.5.2 as default Spark version <a href="https://github.com/bigdatagenomics/adam/issues/911">#911</a></li>
<li>Move to bdg-formats 0.7.0 <a href="https://github.com/bigdatagenomics/adam/issues/905">#905</a></li>
<li>secondOfPair and firstOfPair flag is missing in the newest 0.18 adam transformed results from BAM <a href="https://github.com/bigdatagenomics/adam/issues/903">#903</a></li>
<li>Future pull request <a href="https://github.com/bigdatagenomics/adam/issues/900">#900</a></li>
<li>error in vcf2adam <a href="https://github.com/bigdatagenomics/adam/issues/899">#899</a></li>
<li>Importing directory of VCFs seems to fail <a href="https://github.com/bigdatagenomics/adam/issues/898">#898</a></li>
<li>How to filter genotypeRDD on sample names? org.apache.spark.SparkException: Task not serializable? <a href="https://github.com/bigdatagenomics/adam/issues/891">#891</a></li>
<li>Add Spark version 1.5.x to Jenkins build matrix <a href="https://github.com/bigdatagenomics/adam/issues/889">#889</a></li>
<li>Transform DAG causes stages to recompute <a href="https://github.com/bigdatagenomics/adam/issues/883">#883</a></li>
<li>adam-submit buildinfo is confused <a href="https://github.com/bigdatagenomics/adam/issues/880">#880</a></li>
<li>move_to_scala_2.11 and maven-javadoc-plugin <a href="https://github.com/bigdatagenomics/adam/issues/863">#863</a></li>
<li>NativeCodeLoader: Unable to load native-hadoop library for your platform&hellip; using builtin-java classes where applicable <a href="https://github.com/bigdatagenomics/adam/issues/837">#837</a></li>
<li>Fix record oriented shuffle <a href="https://github.com/bigdatagenomics/adam/issues/599">#599</a></li>
<li>Avro.GenericData error with ADAM 0.12.0 on reading from ADAM file <a href="https://github.com/bigdatagenomics/adam/issues/290">#290</a></li>
</ul>


<p><strong>Merged and closed pull requests:</strong></p>

<ul>
<li>[ADAM-960] Updating bdg-utils dependency version to 0.2.4 <a href="https://github.com/bigdatagenomics/adam/pull/961">#961</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-946] Fixes to FlagStat for Samtools concordance issue <a href="https://github.com/bigdatagenomics/adam/pull/954">#954</a> (<a href="https://github.com/jpdna">jpdna</a>)</li>
<li>Fix for travis build, replace reads2ref with reads2fragments <a href="https://github.com/bigdatagenomics/adam/pull/950">#950</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-940] Fix adam2vcf -sort_on_save flag <a href="https://github.com/bigdatagenomics/adam/pull/949">#949</a> (<a href="https://github.com/massie">massie</a>)</li>
<li>Remove BuildInformation and extraneous git-commit-id-plugin configuration <a href="https://github.com/bigdatagenomics/adam/pull/948">#948</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Update readme for spark 1.5.2 and hadoop 2.6.0 <a href="https://github.com/bigdatagenomics/adam/pull/944">#944</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-942] Replace first/secondInRead with readInFragment <a href="https://github.com/bigdatagenomics/adam/pull/943">#943</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-937] Adding check for aligned read predicate or limit projection flags and non-parquet input path <a href="https://github.com/bigdatagenomics/adam/pull/938">#938</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>[ADAM-934] Properly handle unset library name during duplicate marking <a href="https://github.com/bigdatagenomics/adam/pull/935">#935</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-911] Move to Spark 1.5.2 and Hadoop 2.6.0 as default versions. <a href="https://github.com/bigdatagenomics/adam/pull/932">#932</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>added start and end values to Interval Trait. Used for IntervalRDD <a href="https://github.com/bigdatagenomics/adam/pull/931">#931</a> (<a href="https://github.com/akmorrow13">akmorrow13</a>)</li>
<li>Removing buildinfo command <a href="https://github.com/bigdatagenomics/adam/pull/929">#929</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Removing symbolic test resource links, read from test classpath instead <a href="https://github.com/bigdatagenomics/adam/pull/927">#927</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Changed fisher strand bias field for VCF2Adam from SB to FS <a href="https://github.com/bigdatagenomics/adam/pull/924">#924</a> (<a href="https://github.com/andrewmchen">andrewmchen</a>)</li>
<li>[ADAM-920] Limit tag/orig qual flags in Transform. <a href="https://github.com/bigdatagenomics/adam/pull/921">#921</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Change the README to use adam-shell -i instead of pasting <a href="https://github.com/bigdatagenomics/adam/pull/919">#919</a> (<a href="https://github.com/andrewmchen">andrewmchen</a>)</li>
<li>[ADAM-916] New strategy for writing header. <a href="https://github.com/bigdatagenomics/adam/pull/917">#917</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>[ADAM-914] Create a GenomicRegionPartitioner given a partition count. <a href="https://github.com/bigdatagenomics/adam/pull/915">#915</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Squashed #907 and ran format-sources <a href="https://github.com/bigdatagenomics/adam/pull/908">#908</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Various small fixes <a href="https://github.com/bigdatagenomics/adam/pull/908">#907</a> (<a href="https://github.com/huitseeker">huitseeker</a>)</li>
<li>ADAM-599, 905: Move to bdg-formats:0.7.0 and migrate metadata <a href="https://github.com/bigdatagenomics/adam/pull/906">#906</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Rewrote the getType method to handle all ploidy levels <a href="https://github.com/bigdatagenomics/adam/pull/904">#904</a> (<a href="https://github.com/NeillGibson">NeillGibson</a>)</li>
<li>Single file save from #733, rebased <a href="https://github.com/bigdatagenomics/adam/pull/901">#901</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Added is* genotype methods from HTS-JDK Genotype to RichGenotype <a href="https://github.com/bigdatagenomics/adam/pull/895">#895</a> (<a href="https://github.com/NeillGibson">NeillGibson</a>)</li>
<li>[ADAM-891] Mark SparkContext as @transient. <a href="https://github.com/bigdatagenomics/adam/pull/894">#894</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
<li>Update README URLs based on HTTP redirects <a href="https://github.com/bigdatagenomics/adam/pull/892">#892</a> (<a href="https://github.com/ReadmeCritic">ReadmeCritic</a>)</li>
<li>adding &mdash;version command line option <a href="https://github.com/bigdatagenomics/adam/pull/888">#888</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Add exception in move_to_scala_2.11.sh for maven-javadoc-plugin <a href="https://github.com/bigdatagenomics/adam/pull/887">#887</a> (<a href="https://github.com/heuermh">heuermh</a>)</li>
<li>Fix tightlist bug in Pandoc <a href="https://github.com/bigdatagenomics/adam/pull/885">#885</a> (<a href="https://github.com/massie">massie</a>)</li>
<li>[ADAM-883] Add caching to Transform pipeline. <a href="https://github.com/bigdatagenomics/adam/pull/884">#884</a> (<a href="https://github.com/fnothaft">fnothaft</a>)</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.18.2 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2015/11/11/adam-0-dot-18-dot-2-released/"/>
    <updated>2015-11-11T11:00:00-08:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2015/11/11/adam-0-dot-18-dot-2-released</id>
    <content type="html"><![CDATA[<p>A few ADAM releases have been made since the last announcement; we&rsquo;ll attempt to catch up here.</p>

<p>The most recent is a version <a href="https://github.com/bigdatagenomics/adam/releases">0.18.2 bugfix release</a>, built for both <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.10-0.18.2">Scala 2.10</a> and <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.11-0.18.2">Scala 2.11</a>.  It fixes <a href="https://github.com/bigdatagenomics/adam/pull/873">a minor issue</a> with the binary distribution artifact from version 0.18.1.</p>

<p>Prior to version 0.18.2, we made significant changes to support version 0.6.0 of the Big Data Genomics <a href="https://github.com/bigdatagenomics/bdg-formats/releases/tag/bdg-formats-0.6.0">Avro data formats</a>.  We also improved performance on core transforms (markdups, indel realignment, bqsr) by using finer grained projection.  Some issues in 2bitfile when dealing with gaps and masked regions were fixed.  Round-trip transformations from native formats (e.g., FASTA, FASTQ, SAM, BAM) to ADAM and back have been improved.  We made extending ADAM more straightforward.</p>

<p>ADAM now runs on a wide range of Apache Spark (1.2.1 up to and including the most recent, 1.5.1) and Apache Hadoop (currently 1.0.4, 2.3.0 and 2.6.0) versions.  This is verified by a compatibility matrix of Spark, Hadoop, and Scala version builds in our <a href="https://amplab.cs.berkeley.edu/jenkins/view/Big%20Data%20Genomics/">continuous integration system</a>.</p>

<p>The full list of changes since version 0.17.0 is below.</p>

<!-- more -->


<h3>Version 0.18.2</h3>

<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/877">877</a>: Minor fix to commit script to support https.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/876">876</a>: Separate command line argument words by underscores</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/875">875</a>: P Operator parsing for MDTag</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/873">873</a>: [ADAM-872] Modify regex to capture release and SNAPSHOT jars but not javadoc or sources jars</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/866">866</a>: [ADAM-864] Don&rsquo;t force shuffle if reducing partition count.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/856">856</a>: export valid fastq</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/847">847</a>: Updating build dependency versions to latest minor versions</li>
</ul>


<h3>Version 0.18.1</h3>

<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/870">870</a>: [ADAM-867] add pull requests missing from 0.18.0 release to CHANGES.md</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/869">869</a>: [ADAM-868] make release branch and tag names consistent</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/862">862</a>: [ADAM-861] use -d to check for repo assembly dir</li>
</ul>


<h3>Version 0.18.0</h3>

<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/860">860</a>: New release and pr-commit scripts</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/859">859</a>: [ADAM-857] Corrected handling of env vars in bin scripts</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/854">854</a>: [ADAM-853] allow main class in adam-submit to be specified</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/852">852</a>: [ADAM-851] Slienced Parquet logging.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/850">850</a>: [ADAM-848] TwoBitFile now support nBlocks and maskBlocks</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/846">846</a>: Updating maven build plugin dependency versions</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/845">845</a>: [ADAM-780] Make DecadentRead package private.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/844">844</a>: [ADAM-843] Aggressively project out metadata fields.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/840">840</a>: fix flagstat output file encoding</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/839">839</a>: let flagstat write to file</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/831">831</a>: Support loading paired fastqs</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/830">830</a>: better validation when saving paired fastqs</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/829">829</a>: fix <code>Long != null</code> warnings</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/819">819</a>: Implement custom ReferenceRegion hashcode</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/816">816</a>: [ADAM-793] adding command to convert ADAM nucleotide contig fragments to FASTA files</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/815">815</a>: Upgrade to bdg-formats:0.6.0, add Fragment datatype converters</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/814">814</a>: [ADAM-812] fix for javadoc errors on JDK8</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/813">813</a>: [ADAM-808] build an assembly cli jar with maven shade plugin</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/810">810</a>: [ADAM-807] workaround for ktoso/maven-git-commit-id-plugin#61</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/809">809</a>: [ADAM-785] Add support for all numeric array (TYPE=B) tags</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/806">806</a>: [ADAM-755] updating utils dependency version to 0.2.3</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/805">805</a>: Better transform error when file doesn&rsquo;t exist</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/803">803</a>: fix unmapped-read sorting</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/802">802</a>: stop writing contig names as md5 sums</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/798">798</a>: fix SAM-attr conversion bug; int[]&rsquo;s not byte[]&rsquo;s</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/790">790</a>: optionally add MDTags to reads with <code>transform</code></li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/782">782</a>: Fix SAM Attribute parser for numeric array tags</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/773">773</a>: [ADAM-772] fix some bash var quoting</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/765">765</a>: [ADAM-752] Build for many combos of Spark/Hadoop versions.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/764">764</a>: More involved README restructuring</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/762">762</a>: [ADAM-132] allowing list of commands to be injected into adam-cli ADAMMain</li>
</ul>


<h3>Version 0.17.1</h3>

<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/784">784</a>: [ADAM-783] Write @SQ header lines in sorted order.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/792">792</a>: [ADAM-791] Add repartition parameter to Fasta2ADAM.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/781">781</a>: [ADAM-777] Add validation stringency flag for BQSR.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/757">757</a>: We should print a warning message if the user has ADAM_OPTS set.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/770">770</a>: [ADAM-769] Fix serialization issue in known indel consensus model.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/763">763</a>: Clean up README links, other nits</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/749">749</a>: Remove adam-cli jar from classpath during adam-submit</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/754">754</a>: Bump ADAM to Spark 1.4</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/753">753</a>: Bump Spark to 1.4</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/748">748</a>: Fix for mdtag issues with insertions</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/746">746</a>: Upgrade to Parquet 1.8.1.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/744">744</a>: [ADAM-743] exclude conflicting jackson dependencies</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/737">737</a>: Reverse complement negative strand reads in fastq output</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/731">731</a>: Fixed bug preventing use of TLEN attribute</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/730">730</a>: [ADAM-729] Stuff TLEN into attributes.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/728">728</a>: [ADAM-709] Remove FeatureHierarchy and FeatureHierarchySuite</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/719">719</a>: [ADAM-718] Use filesystem path to get underlying file system.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/712">712</a>: unify header-setting between BAM/SAM and VCF</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/696">696</a>: include SequenceRecords from second-in-pair reads</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/698">698</a>: class-ify ShuffleRegionJoin, force setting seqdict</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/706">706</a>: restore clause guarding pruneCache check</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/705">705</a>: GeneFeatureRDDFunctions → FeatureRDDFunctions</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[Genomic Analysis Using ADAM, Spark and Deep Learning]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2015/07/10/genomic-analysis-using-adam/"/>
    <updated>2015-07-10T10:19:45-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2015/07/10/genomic-analysis-using-adam</id>
    <content type="html"><![CDATA[<blockquote><p>Special thanks to <a href="https://github.com/nfergu">Neil Ferguson</a> for this blog post on genomic analysis using ADAM, Spark and Deep Learning</p></blockquote>

<p>Can we use deep learning to predict which population group you belong to, based solely on your genome?</p>

<p>Yes, we can &ndash; and in this post, we will show you exactly how to do this in a scalable way, using Apache Spark. We will explain how to apply <a href="https://en.wikipedia.org/wiki/Deep_learning">deep learning</a> using <a href="https://en.wikipedia.org/wiki/Artificial_neural_network">artifical neural networks</a> to predict which population group an individual belongs to &ndash; based entirely on his or her genomic data.</p>

<p>This is a follow-up to an earlier post: <a href="http://bdgenomics.org/blog/2015/02/02/scalable-genomes-clustering-with-adam-and-spark/">Scalable Genomes Clustering With ADAM and Spark</a> and attempts to replicate the results of that post. However, we will use a different machine learning technique.  Where the original post used <a href="https://en.wikipedia.org/wiki/K-means_clustering">k-means clustering</a>, we will use deep learning.</p>

<p>We will use <a href="https://github.com/bigdatagenomics/adam">ADAM</a> and <a href="https://spark.apache.org/">Apache Spark</a> in combination with <a href="http://0xdata.com/product/">H2O</a>, an open source predictive analytics platform, and <a href="http://0xdata.com/product/sparkling-water/">Sparking Water</a>, which integrates H2O with Spark.</p>

<!-- more -->


<h2>Code</h2>

<p>In this section, we&rsquo;ll dive straight into the code. If you&rsquo;d rather get something working before looking at the code you can skip to the &ldquo;Building and Running&rdquo; section.</p>

<p>The complete Scala code for this example can be found in <a href="https://github.com/nfergu/popstrat/blob/master/src/main/scala/com/neilferguson/PopStrat.scala">the PopStrat.scala class on GitHub</a> and we&rsquo;ll refer to sections of the code here. Basic familiarity with Scala and <a href="https://spark.apache.org/">Apache Spark</a> is assumed.</p>

<h3>Setting-up</h3>

<p>The first thing we need to do is to read the names of the Genotype and Panel files that are passed into our program.  The Genotype file contains data about a set of individuals (referred to here as &ldquo;samples&rdquo;) and their genetic variation. The Panel file lists the population group (or &ldquo;region&rdquo;) for each sample in the Genotype file; this is what we will try to predict.</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">genotypeFile</span> <span class="k">=</span> <span class="n">args</span><span class="o">(</span><span class="mi">0</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">panelFile</span> <span class="k">=</span> <span class="n">args</span><span class="o">(</span><span class="mi">1</span><span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<p>Next, we set-up our Spark Context. Our program permits the Spark master to be specified as one of its arguments. This is useful when running from an IDE, but is omitted when running from the <code>spark-submit</code> script (see below).</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">master</span> <span class="k">=</span> <span class="k">if</span> <span class="o">(</span><span class="n">args</span><span class="o">.</span><span class="n">length</span> <span class="o">&gt;</span> <span class="mi">2</span><span class="o">)</span> <span class="nc">Some</span><span class="o">(</span><span class="n">args</span><span class="o">(</span><span class="mi">2</span><span class="o">))</span> <span class="k">else</span> <span class="nc">None</span>
</span><span class='line'><span class="k">val</span> <span class="n">conf</span> <span class="k">=</span> <span class="k">new</span> <span class="nc">SparkConf</span><span class="o">().</span><span class="n">setAppName</span><span class="o">(</span><span class="s">&quot;PopStrat&quot;</span><span class="o">)</span>
</span><span class='line'><span class="n">master</span><span class="o">.</span><span class="n">foreach</span><span class="o">(</span><span class="n">conf</span><span class="o">.</span><span class="n">setMaster</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">sc</span> <span class="k">=</span> <span class="k">new</span> <span class="nc">SparkContext</span><span class="o">(</span><span class="n">conf</span><span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<p>Next, we declare a set called <code>populations</code> which contains all of the population groups that we&rsquo;re interested
in predicting. We then read the Panel file into a Map, filtering it based on the population groups in the
<code>populations</code> set. The format of the panel file is described <a href="http://www.1000genomes.org/faq/what-panel-file">here</a>.
Luckily it&rsquo;s very simple, containing the sample ID in the first column and the population group in the second.</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">populations</span> <span class="k">=</span> <span class="nc">Set</span><span class="o">(</span><span class="s">&quot;GBR&quot;</span><span class="o">,</span> <span class="s">&quot;ASW&quot;</span><span class="o">,</span> <span class="s">&quot;CHB&quot;</span><span class="o">)</span>
</span><span class='line'><span class="k">def</span> <span class="n">extract</span><span class="o">(</span><span class="n">file</span><span class="k">:</span> <span class="kt">String</span><span class="o">,</span> <span class="n">filter</span><span class="k">:</span> <span class="o">(</span><span class="kt">String</span><span class="o">,</span> <span class="kt">String</span><span class="o">)</span> <span class="k">=&gt;</span> <span class="nc">Boolean</span><span class="o">)</span><span class="k">:</span> <span class="kt">Map</span><span class="o">[</span><span class="kt">String</span>,<span class="kt">String</span><span class="o">]</span> <span class="k">=</span> <span class="o">{</span>
</span><span class='line'>  <span class="nc">Source</span><span class="o">.</span><span class="n">fromFile</span><span class="o">(</span><span class="n">file</span><span class="o">).</span><span class="n">getLines</span><span class="o">().</span><span class="n">map</span><span class="o">(</span><span class="n">line</span> <span class="k">=&gt;</span> <span class="o">{</span>
</span><span class='line'>    <span class="k">val</span> <span class="n">tokens</span> <span class="k">=</span> <span class="n">line</span><span class="o">.</span><span class="n">split</span><span class="o">(</span><span class="s">&quot;\t&quot;</span><span class="o">).</span><span class="n">toList</span>
</span><span class='line'>    <span class="n">tokens</span><span class="o">(</span><span class="mi">0</span><span class="o">)</span> <span class="o">-&gt;</span> <span class="n">tokens</span><span class="o">(</span><span class="mi">1</span><span class="o">)</span>
</span><span class='line'>  <span class="o">}).</span><span class="n">toMap</span><span class="o">.</span><span class="n">filter</span><span class="o">(</span><span class="n">tuple</span> <span class="k">=&gt;</span> <span class="n">filter</span><span class="o">(</span><span class="n">tuple</span><span class="o">.</span><span class="n">_1</span><span class="o">,</span> <span class="n">tuple</span><span class="o">.</span><span class="n">_2</span><span class="o">))</span>
</span><span class='line'><span class="o">}</span>
</span><span class='line'><span class="k">val</span> <span class="n">panel</span><span class="k">:</span> <span class="kt">Map</span><span class="o">[</span><span class="kt">String</span>,<span class="kt">String</span><span class="o">]</span> <span class="k">=</span> <span class="n">extract</span><span class="o">(</span><span class="n">panelFile</span><span class="o">,</span> <span class="o">(</span><span class="n">sampleID</span><span class="k">:</span> <span class="kt">String</span><span class="o">,</span> <span class="n">pop</span><span class="k">:</span> <span class="kt">String</span><span class="o">)</span> <span class="k">=&gt;</span> <span class="n">populations</span><span class="o">.</span><span class="n">contains</span><span class="o">(</span><span class="n">pop</span><span class="o">))</span>
</span></code></pre></td></tr></table></div></figure>


<h3>Preparing the Genomics Data</h3>

<p>Next, we use <a href="https://github.com/bigdatagenomics/adam">ADAM</a> to read our genotype data into a Spark RDD. Since we&rsquo;ve imported <code>ADAMContext._</code> at the top of our class, this is simply a matter of calling <code>loadGenotypes</code> on the Spark Context. Then, we filter the genotype data to contain only samples that are in the population groups which we&rsquo;re interested in.</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">allGenotypes</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[</span><span class="kt">Genotype</span><span class="o">]</span> <span class="k">=</span> <span class="n">sc</span><span class="o">.</span><span class="n">loadGenotypes</span><span class="o">(</span><span class="n">genotypeFile</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">genotypes</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[</span><span class="kt">Genotype</span><span class="o">]</span> <span class="k">=</span> <span class="n">allGenotypes</span><span class="o">.</span><span class="n">filter</span><span class="o">(</span><span class="n">genotype</span> <span class="k">=&gt;</span> <span class="o">{</span><span class="n">panel</span><span class="o">.</span><span class="n">contains</span><span class="o">(</span><span class="n">genotype</span><span class="o">.</span><span class="n">getSampleId</span><span class="o">)})</span>
</span></code></pre></td></tr></table></div></figure>


<p>Next, we convert the ADAM <code>Genotype</code> objects into our own <code>SampleVariant</code> objects. These objects contain just the data we need for further processing: the sample ID (which uniquely identifies a particular sample), a variant ID (which uniquely identifies a particular genetic variant) and a count of alternate <a href="http://www.snpedia.com/index.php/Allele">alleles</a>, where the sample differs from the reference genome. These variations will help us to classify individuals according to their population group.</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
<span class='line-number'>9</span>
<span class='line-number'>10</span>
<span class='line-number'>11</span>
<span class='line-number'>12</span>
<span class='line-number'>13</span>
<span class='line-number'>14</span>
<span class='line-number'>15</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">case</span> <span class="k">class</span> <span class="nc">SampleVariant</span><span class="o">(</span><span class="n">sampleId</span><span class="k">:</span> <span class="kt">String</span><span class="o">,</span> <span class="n">variantId</span><span class="k">:</span> <span class="kt">Int</span><span class="o">,</span> <span class="n">alternateCount</span><span class="k">:</span> <span class="kt">Int</span><span class="o">)</span>
</span><span class='line'><span class="k">def</span> <span class="n">variantId</span><span class="o">(</span><span class="n">genotype</span><span class="k">:</span> <span class="kt">Genotype</span><span class="o">)</span><span class="k">:</span> <span class="kt">String</span> <span class="o">=</span> <span class="o">{</span>
</span><span class='line'>  <span class="k">val</span> <span class="n">name</span> <span class="k">=</span> <span class="n">genotype</span><span class="o">.</span><span class="n">getVariant</span><span class="o">.</span><span class="n">getContig</span><span class="o">.</span><span class="n">getContigName</span>
</span><span class='line'>  <span class="k">val</span> <span class="n">start</span> <span class="k">=</span> <span class="n">genotype</span><span class="o">.</span><span class="n">getVariant</span><span class="o">.</span><span class="n">getStart</span>
</span><span class='line'>  <span class="k">val</span> <span class="n">end</span> <span class="k">=</span> <span class="n">genotype</span><span class="o">.</span><span class="n">getVariant</span><span class="o">.</span><span class="n">getEnd</span>
</span><span class='line'>  <span class="n">s</span><span class="s">&quot;$name:$start:$end&quot;</span>
</span><span class='line'><span class="o">}</span>
</span><span class='line'><span class="k">def</span> <span class="n">alternateCount</span><span class="o">(</span><span class="n">genotype</span><span class="k">:</span> <span class="kt">Genotype</span><span class="o">)</span><span class="k">:</span> <span class="kt">Int</span> <span class="o">=</span> <span class="o">{</span>
</span><span class='line'>  <span class="n">genotype</span><span class="o">.</span><span class="n">getAlleles</span><span class="o">.</span><span class="n">asScala</span><span class="o">.</span><span class="n">count</span><span class="o">(</span><span class="k">_</span> <span class="o">!=</span> <span class="nc">GenotypeAllele</span><span class="o">.</span><span class="nc">Ref</span><span class="o">)</span>
</span><span class='line'><span class="o">}</span>
</span><span class='line'><span class="k">def</span> <span class="n">toVariant</span><span class="o">(</span><span class="n">genotype</span><span class="k">:</span> <span class="kt">Genotype</span><span class="o">)</span><span class="k">:</span> <span class="kt">SampleVariant</span> <span class="o">=</span> <span class="o">{</span>
</span><span class='line'>  <span class="c1">// Intern sample IDs as they will be repeated a lot</span>
</span><span class='line'>  <span class="k">new</span> <span class="nc">SampleVariant</span><span class="o">(</span><span class="n">genotype</span><span class="o">.</span><span class="n">getSampleId</span><span class="o">.</span><span class="n">intern</span><span class="o">(),</span> <span class="n">variantId</span><span class="o">(</span><span class="n">genotype</span><span class="o">).</span><span class="n">hashCode</span><span class="o">(),</span> <span class="n">alternateCount</span><span class="o">(</span><span class="n">genotype</span><span class="o">))</span>
</span><span class='line'><span class="o">}</span>
</span><span class='line'><span class="k">val</span> <span class="n">variantsRDD</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[</span><span class="kt">SampleVariant</span><span class="o">]</span> <span class="k">=</span> <span class="n">genotypes</span><span class="o">.</span><span class="n">map</span><span class="o">(</span><span class="n">toVariant</span><span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<p>Next, we count the total number of samples (individuals) in the data. We then group the data by variant ID and filter out those variants which do not appear in all of the samples. The aim of this is to simplify the processing of the data and, since we have a very large number of variants in the data (up to 30 million, depending on the exact data set), filtering out a small number will not make a significant difference to the results. In fact, in the next step we&rsquo;ll reduce the number of variants even further.</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">variantsBySampleId</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[(</span><span class="kt">String</span>, <span class="kt">Iterable</span><span class="o">[</span><span class="kt">SampleVariant</span><span class="o">])]</span> <span class="k">=</span> <span class="n">variantsRDD</span><span class="o">.</span><span class="n">groupBy</span><span class="o">(</span><span class="k">_</span><span class="o">.</span><span class="n">sampleId</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">sampleCount</span><span class="k">:</span> <span class="kt">Long</span> <span class="o">=</span> <span class="n">variantsBySampleId</span><span class="o">.</span><span class="n">count</span><span class="o">()</span>
</span><span class='line'><span class="n">println</span><span class="o">(</span><span class="s">&quot;Found &quot;</span> <span class="o">+</span> <span class="n">sampleCount</span> <span class="o">+</span> <span class="s">&quot; samples&quot;</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">variantsByVariantId</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[(</span><span class="kt">Int</span>, <span class="kt">Iterable</span><span class="o">[</span><span class="kt">SampleVariant</span><span class="o">])]</span> <span class="k">=</span> <span class="n">variantsRDD</span><span class="o">.</span><span class="n">groupBy</span><span class="o">(</span><span class="k">_</span><span class="o">.</span><span class="n">variantId</span><span class="o">).</span><span class="n">filter</span> <span class="o">{</span>
</span><span class='line'>  <span class="k">case</span> <span class="o">(</span><span class="k">_</span><span class="o">,</span> <span class="n">sampleVariants</span><span class="o">)</span> <span class="k">=&gt;</span> <span class="n">sampleVariants</span><span class="o">.</span><span class="n">size</span> <span class="o">==</span> <span class="n">sampleCount</span>
</span><span class='line'><span class="o">}</span>
</span></code></pre></td></tr></table></div></figure>


<p>When we train our machine learning model, each variant will be treated as a &ldquo;<a href="https://en.wikipedia.org/wiki/Feature_(machine_learning">feature</a>)&rdquo; that is used to train the model.  Since it can be difficult to train machine learning models with very large numbers of features in the data (particularly if the number of samples is relatively small), we first need to try and reduce the number of variants in the data.</p>

<p>To do this, we first compute the frequency with which alternate alleles have occurred for each variant. We then filter the variants down to just those that appear within a certain frequency range. In this case, we&rsquo;ve chosen a fairly arbitrary frequency of 11. This was chosen through experimentation as a value that leaves around 3,000 variants in the data set we are using.</p>

<p>There are more structured approaches to <a href="https://en.wikipedia.org/wiki/Dimensionality_reduction">dimensionality reduction</a>, which we perhaps could have
employed, but this technique seems to work well enough for this example.</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
<span class='line-number'>9</span>
<span class='line-number'>10</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">variantFrequencies</span><span class="k">:</span> <span class="kt">collection.Map</span><span class="o">[</span><span class="kt">Int</span>, <span class="kt">Int</span><span class="o">]</span> <span class="k">=</span> <span class="n">variantsByVariantId</span><span class="o">.</span><span class="n">map</span> <span class="o">{</span>
</span><span class='line'>  <span class="k">case</span> <span class="o">(</span><span class="n">variantId</span><span class="o">,</span> <span class="n">sampleVariants</span><span class="o">)</span> <span class="k">=&gt;</span> <span class="o">(</span><span class="n">variantId</span><span class="o">,</span> <span class="n">sampleVariants</span><span class="o">.</span><span class="n">count</span><span class="o">(</span><span class="k">_</span><span class="o">.</span><span class="n">alternateCount</span> <span class="o">&gt;</span> <span class="mi">0</span><span class="o">))</span>
</span><span class='line'><span class="o">}.</span><span class="n">collectAsMap</span><span class="o">()</span>
</span><span class='line'><span class="k">val</span> <span class="n">permittedRange</span> <span class="k">=</span> <span class="n">inclusive</span><span class="o">(</span><span class="mi">11</span><span class="o">,</span> <span class="mi">11</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">filteredVariantsBySampleId</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[(</span><span class="kt">String</span>, <span class="kt">Iterable</span><span class="o">[</span><span class="kt">SampleVariant</span><span class="o">])]</span> <span class="k">=</span> <span class="n">variantsBySampleId</span><span class="o">.</span><span class="n">map</span> <span class="o">{</span>
</span><span class='line'>  <span class="k">case</span> <span class="o">(</span><span class="n">sampleId</span><span class="o">,</span> <span class="n">sampleVariants</span><span class="o">)</span> <span class="k">=&gt;</span>
</span><span class='line'>    <span class="k">val</span> <span class="n">filteredSampleVariants</span> <span class="k">=</span> <span class="n">sampleVariants</span><span class="o">.</span><span class="n">filter</span><span class="o">(</span><span class="n">variant</span> <span class="k">=&gt;</span> <span class="n">permittedRange</span><span class="o">.</span><span class="n">contains</span><span class="o">(</span>
</span><span class='line'>      <span class="n">variantFrequencies</span><span class="o">.</span><span class="n">getOrElse</span><span class="o">(</span><span class="n">variant</span><span class="o">.</span><span class="n">variantId</span><span class="o">,</span> <span class="o">-</span><span class="mi">1</span><span class="o">)))</span>
</span><span class='line'>    <span class="o">(</span><span class="n">sampleId</span><span class="o">,</span> <span class="n">filteredSampleVariants</span><span class="o">)</span>
</span><span class='line'><span class="o">}</span>
</span></code></pre></td></tr></table></div></figure>


<h3>Creating the Training Data</h3>

<p>To train our model, we need our data to be in tabular form where each row represents a single sample, and each column represents a specific variant. The table also contains a column for the population group or &ldquo;Region&rdquo;, which is what we are trying to predict.</p>

<p>Ultimately, in order for our data to be consumed by H2O we need it to end up in an H2O <code>DataFrame</code> object. Currently, the best way to do this in Spark seems to be to convert our data to an RDD of Spark SQL <a href="http://spark.apache.org/docs/1.4.0/api/scala/index.html#org.apache.spark.sql.Row">Row</a> objects, and then this can automatically be converted to an H2O DataFrame.</p>

<p>To achieve this, we first need to group the data by sample ID, and then sort the variants for each sample in a consistent manner (by variant ID). We can then create a header row for our table, containing the Region column, the sample ID and all of the variants. We then create an RDD of type <code>Row</code> for each sample.</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
<span class='line-number'>9</span>
<span class='line-number'>10</span>
<span class='line-number'>11</span>
<span class='line-number'>12</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">sortedVariantsBySampleId</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[(</span><span class="kt">String</span>, <span class="kt">Array</span><span class="o">[</span><span class="kt">SampleVariant</span><span class="o">])]</span> <span class="k">=</span> <span class="n">filteredVariantsBySampleId</span><span class="o">.</span><span class="n">map</span> <span class="o">{</span>
</span><span class='line'>  <span class="k">case</span> <span class="o">(</span><span class="n">sampleId</span><span class="o">,</span> <span class="n">variants</span><span class="o">)</span> <span class="k">=&gt;</span>
</span><span class='line'>    <span class="o">(</span><span class="n">sampleId</span><span class="o">,</span> <span class="n">variants</span><span class="o">.</span><span class="n">toArray</span><span class="o">.</span><span class="n">sortBy</span><span class="o">(</span><span class="k">_</span><span class="o">.</span><span class="n">variantId</span><span class="o">))</span>
</span><span class='line'><span class="o">}</span>
</span><span class='line'><span class="k">val</span> <span class="n">header</span> <span class="k">=</span> <span class="nc">StructType</span><span class="o">(</span><span class="nc">Array</span><span class="o">(</span><span class="nc">StructField</span><span class="o">(</span><span class="s">&quot;Region&quot;</span><span class="o">,</span> <span class="nc">StringType</span><span class="o">))</span> <span class="o">++</span>
</span><span class='line'>  <span class="n">sortedVariantsBySampleId</span><span class="o">.</span><span class="n">first</span><span class="o">().</span><span class="n">_2</span><span class="o">.</span><span class="n">map</span><span class="o">(</span><span class="n">variant</span> <span class="k">=&gt;</span> <span class="o">{</span><span class="nc">StructField</span><span class="o">(</span><span class="n">variant</span><span class="o">.</span><span class="n">variantId</span><span class="o">.</span><span class="n">toString</span><span class="o">,</span> <span class="nc">IntegerType</span><span class="o">)}))</span>
</span><span class='line'><span class="k">val</span> <span class="n">rowRDD</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[</span><span class="kt">Row</span><span class="o">]</span> <span class="k">=</span> <span class="n">sortedVariantsBySampleId</span><span class="o">.</span><span class="n">map</span> <span class="o">{</span>
</span><span class='line'>  <span class="k">case</span> <span class="o">(</span><span class="n">sampleId</span><span class="o">,</span> <span class="n">sortedVariants</span><span class="o">)</span> <span class="k">=&gt;</span>
</span><span class='line'>    <span class="k">val</span> <span class="n">region</span><span class="k">:</span> <span class="kt">Array</span><span class="o">[</span><span class="kt">String</span><span class="o">]</span> <span class="k">=</span> <span class="nc">Array</span><span class="o">(</span><span class="n">panel</span><span class="o">.</span><span class="n">getOrElse</span><span class="o">(</span><span class="n">sampleId</span><span class="o">,</span> <span class="s">&quot;Unknown&quot;</span><span class="o">))</span>
</span><span class='line'>    <span class="k">val</span> <span class="n">alternateCounts</span><span class="k">:</span> <span class="kt">Array</span><span class="o">[</span><span class="kt">Int</span><span class="o">]</span> <span class="k">=</span> <span class="n">sortedVariants</span><span class="o">.</span><span class="n">map</span><span class="o">(</span><span class="k">_</span><span class="o">.</span><span class="n">alternateCount</span><span class="o">)</span>
</span><span class='line'>    <span class="nc">Row</span><span class="o">.</span><span class="n">fromSeq</span><span class="o">(</span><span class="n">region</span> <span class="o">++</span> <span class="n">alternateCounts</span><span class="o">)</span>
</span><span class='line'><span class="o">}</span>
</span></code></pre></td></tr></table></div></figure>


<p>As mentioned above, once we have our RDD of <code>Row</code> objects we can then convert these automatically to an H2O DataFrame using Sparking Water (H2O&rsquo;s Spark integration).</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">sqlContext</span> <span class="k">=</span> <span class="k">new</span> <span class="n">org</span><span class="o">.</span><span class="n">apache</span><span class="o">.</span><span class="n">spark</span><span class="o">.</span><span class="n">sql</span><span class="o">.</span><span class="nc">SQLContext</span><span class="o">(</span><span class="n">sc</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">schemaRDD</span> <span class="k">=</span> <span class="n">sqlContext</span><span class="o">.</span><span class="n">applySchema</span><span class="o">(</span><span class="n">rowRDD</span><span class="o">,</span> <span class="n">header</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">h2oContext</span> <span class="k">=</span> <span class="k">new</span> <span class="n">H2OContext</span><span class="o">(</span><span class="n">sc</span><span class="o">).</span><span class="n">start</span><span class="o">()</span>
</span><span class='line'><span class="k">import</span> <span class="nn">h2oContext._</span>
</span><span class='line'><span class="k">val</span> <span class="n">dataFrame</span> <span class="k">=</span> <span class="n">h2oContext</span><span class="o">.</span><span class="n">toDataFrame</span><span class="o">(</span><span class="n">schemaRDD</span><span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<p>Now that we have a DataFrame, we want to split it into the training data (which we&rsquo;ll use to train our model), and a <a href="https://en.wikipedia.org/wiki/Test_set">test set</a> (which we&rsquo;ll use to ensure that <a href="https://en.wikipedia.org/wiki/Overfitting">overfitting</a> has not occurred).</p>

<p>We will also create a &ldquo;validation&rdquo; set, which performs a similar purpose to the test set &ndash; in that it will be used to validate the strength of our model as it is being built, while avoiding overfitting. However, when training a neural network, we typically keep the validation set distinct from the test set, to enable us to learn <a href="http://colinraffel.com/wiki/neural_network_hyperparameters">hyper-parameters</a> for the model. See <a href="http://neuralnetworksanddeeplearning.com/chap3.html">chapter 3 of Michael Nielsen&rsquo;s &ldquo;Neural Networks and Deep Learning&rdquo;</a>
for more details on this.</p>

<p>H2O comes with a class called <code>FrameSplitter</code>, so splitting the data is simply a matter of calling creating one of those and letting it split the data set.</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">frameSplitter</span> <span class="k">=</span> <span class="k">new</span> <span class="nc">FrameSplitter</span><span class="o">(</span><span class="n">dataFrame</span><span class="o">,</span> <span class="nc">Array</span><span class="o">(.</span><span class="mi">5</span><span class="o">,</span> <span class="o">.</span><span class="mi">3</span><span class="o">),</span> <span class="nc">Array</span><span class="o">(</span><span class="s">&quot;training&quot;</span><span class="o">,</span> <span class="s">&quot;test&quot;</span><span class="o">,</span> <span class="s">&quot;validation&quot;</span><span class="o">).</span><span class="n">map</span><span class="o">(</span><span class="nc">Key</span><span class="o">.</span><span class="n">make</span><span class="o">),</span> <span class="kc">null</span><span class="o">)</span>
</span><span class='line'><span class="n">water</span><span class="o">.</span><span class="n">H2O</span><span class="o">.</span><span class="n">submitTask</span><span class="o">(</span><span class="n">frameSplitter</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">splits</span> <span class="k">=</span> <span class="n">frameSplitter</span><span class="o">.</span><span class="n">getResult</span>
</span><span class='line'><span class="k">val</span> <span class="n">training</span> <span class="k">=</span> <span class="n">splits</span><span class="o">(</span><span class="mi">0</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">validation</span> <span class="k">=</span> <span class="n">splits</span><span class="o">(</span><span class="mi">2</span><span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<h3>Training the Model</h3>

<p>Next, we need to set the parameters for our deep learning model. We specify the training and validation data sets, as well as the column in the data which contains the item we are trying to predict (in this case, the Region).  We also set some <a href="http://colinraffel.com/wiki/neural_network_hyperparameters">hyper-parameters</a> which affect the way the model learns. We won&rsquo;t go into detail about these here, but you can read more in the <a href="http://docs.h2o.ai/h2oclassic/datascience/deeplearning.html">H2O documentation</a>. These parameters have been chosen through experimentation &ndash; however, H2O provides methods for <a href="http://learn.h2o.ai/content/hands-on_training/deep_learning.html">automatically tuning hyper-parameters</a> so it may be possible to achieve better results by employing one of these methods.</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">deepLearningParameters</span> <span class="k">=</span> <span class="k">new</span> <span class="nc">DeepLearningParameters</span><span class="o">()</span>
</span><span class='line'><span class="n">deepLearningParameters</span><span class="o">.</span><span class="nc">_train</span> <span class="k">=</span> <span class="n">training</span>
</span><span class='line'><span class="n">deepLearningParameters</span><span class="o">.</span><span class="nc">_valid</span> <span class="k">=</span> <span class="n">validation</span>
</span><span class='line'><span class="n">deepLearningParameters</span><span class="o">.</span><span class="nc">_response_column</span> <span class="k">=</span> <span class="s">&quot;Region&quot;</span>
</span><span class='line'><span class="n">deepLearningParameters</span><span class="o">.</span><span class="nc">_epochs</span> <span class="k">=</span> <span class="mi">10</span>
</span><span class='line'><span class="n">deepLearningParameters</span><span class="o">.</span><span class="nc">_activation</span> <span class="k">=</span> <span class="nc">Activation</span><span class="o">.</span><span class="nc">RectifierWithDropout</span>
</span><span class='line'><span class="n">deepLearningParameters</span><span class="o">.</span><span class="nc">_hidden</span> <span class="k">=</span> <span class="nc">Array</span><span class="o">[</span><span class="kt">Int</span><span class="o">](</span><span class="mi">100</span><span class="o">,</span><span class="mi">100</span><span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<p>Finally, we&rsquo;re ready to train our deep learning model! Now that we&rsquo;ve set everything up this is easy:
we simply create a H2O <code>DeepLearning</code> object and call <code>trainModel</code> on it.</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">deepLearning</span> <span class="k">=</span> <span class="k">new</span> <span class="nc">DeepLearning</span><span class="o">(</span><span class="n">deepLearningParameters</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">deepLearningModel</span> <span class="k">=</span> <span class="n">deepLearning</span><span class="o">.</span><span class="n">trainModel</span><span class="o">.</span><span class="n">get</span>
</span></code></pre></td></tr></table></div></figure>


<p>Having trained our model in the previous step, we now need to check how well it predicts the population groups in our data set. To do this we &ldquo;score&rdquo; our entire data set (including training, test, and validation data) against our model:</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="n">deepLearningModel</span><span class="o">.</span><span class="n">score</span><span class="o">(</span><span class="n">dataFrame</span><span class="o">)(</span><span class="-Symbol">&#39;predict</span><span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<p>This final step will print a <a href="https://en.wikipedia.org/wiki/Confusion_matrix">confusion matrix</a> which shows how well our model predicts our population groups. All being well, the confusion matrix should look something like this:</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="nc">Confusion</span> <span class="nc">Matrix</span> <span class="o">(</span><span class="n">vertical</span><span class="k">:</span> <span class="kt">actual</span><span class="o">;</span> <span class="n">across</span><span class="k">:</span> <span class="kt">predicted</span><span class="o">)</span><span class="k">:</span>
</span><span class='line'><span class="kt">ASW</span>    <span class="kt">CHB</span> <span class="kt">GBR</span>  <span class="kt">Error</span>      <span class="kt">Rate</span>
</span><span class='line'><span class="nc">ASW</span>     <span class="mi">60</span>   <span class="mi">1</span>   <span class="mi">0</span> <span class="mf">0.0164</span> <span class="k">=</span> <span class="mi">1</span> <span class="o">/</span>  <span class="mi">61</span>
</span><span class='line'><span class="nc">CHB</span>      <span class="mi">0</span> <span class="mi">103</span>   <span class="mi">0</span> <span class="mf">0.0000</span> <span class="k">=</span> <span class="mi">0</span> <span class="o">/</span> <span class="mi">103</span>
</span><span class='line'><span class="nc">GBR</span>      <span class="mi">0</span>   <span class="mi">1</span>  <span class="mi">90</span> <span class="mf">0.0110</span> <span class="k">=</span> <span class="mi">1</span> <span class="o">/</span>  <span class="mi">91</span>
</span><span class='line'><span class="nc">Totals</span>  <span class="mi">60</span> <span class="mi">105</span>  <span class="mi">90</span> <span class="mf">0.0078</span> <span class="k">=</span> <span class="mi">2</span> <span class="o">/</span> <span class="mi">255</span>
</span></code></pre></td></tr></table></div></figure>


<p>This tells us that the model has correctly predicted 253 out of 255 population groups correctly (an accuracy of more than 99%). Nice!</p>

<h2>Building and Running</h2>

<h3>Prerequisites</h3>

<p>Before building and running the example, please ensure you have version 7 or later of the
<a href="http://www.oracle.com/technetwork/java/javase/downloads/index.html">Java JDK</a> installed.</p>

<h3>Building</h3>

<p>To build the example, first clone the GitHub repo at <a href="https://github.com/nfergu/popstrat">https://github.com/nfergu/popstrat</a>.</p>

<p>Then <a href="http://maven.apache.org/download.cgi">download and install Maven</a>. Then, at the command line, type:</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="n">mvn</span> <span class="n">clean</span> <span class="k">package</span>
</span></code></pre></td></tr></table></div></figure>


<p>This will build a JAR (<code>target/uber-popstrat-0.1-SNAPSHOT.jar</code>), containing the <code>PopStrat</code> class,
as well as all of its dependencies.</p>

<h3>Running</h3>

<p>First, <a href="http://spark.apache.org/downloads.html">download Spark version 1.2.0</a> and unpack it on your machine.</p>

<p>Next you&rsquo;ll need to get some genomics data. Go to your <a href="http://www.1000genomes.org/data#DataAccess">nearest mirror of the 1000 genomes FTP site</a>.  From the <code>release/20130502/</code> directory download the <code>ALL.chr22.phase3_shapeit2_mvncall_integrated_v5a.20130502.genotypes.vcf.gz</code> file and the <code>integrated_call_samples_v3.20130502.ALL.panel</code> file. The first file file is the genotype data for chromosome 22, and the second file is the panel file, which describes the population group for each sample in the genotype data.</p>

<p>Unzip the genotype data before continuing. This will require around 10GB of disk space.</p>

<p>To speed up execution and save disk space, you can convert the genotype VCF file to <a href="https://github.com/bigdatagenomics/adam">ADAM</a> format (using the ADAM <code>transform</code> command) if you wish. However, this will take some time up-front. Both ADAM and VCF formats are supported.</p>

<p>Next, run the following command:</p>

<figure class='code'><figcaption><span></span></figcaption><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='bash'><span class='line'><span class="nv">$ </span>YOUR_SPARK_HOME/bin/spark-submit --class <span class="s2">&quot;com.neilferguson.PopStrat&quot;</span> --master <span class="nb">local</span><span class="o">[</span>6<span class="o">]</span> --driver-memory 6G target/uber-popstrat-0.1-SNAPSHOT.jar &lt;genotypesfile&gt; &lt;panelfile&gt;
</span></code></pre></td></tr></table></div></figure>


<p>Replacing &lt;genotypesfile&gt; with the path to your genotype data file (ADAM or VCF), and &lt;panelfile&gt; with the panel file from 1000 genomes.</p>

<p>This runs the example using a local (in-process) Spark master with 6 cores and 6GB of RAM. You can run against a different Spark cluster by modifying the options in the above command line. See the <a href="https://spark.apache.org/docs/1.2.0/submitting-applications.html">Spark documentation</a> for further details.</p>

<p>Using the above data, the example may take up to 2-3 hours to run, depending on hardware. When it is finished, you should see a <a href="http://en.wikipedia.org/wiki/Confusion_matrix">confusion matrix</a> which shows the predicted versus the actual populations. If all has gone well, this should show an accuracy of more than 99%. See the &ldquo;Code&rdquo; section above for more details on what exactly you should expect to see.</p>

<h2>Conclusion</h2>

<p>In this post, we have shown how to combine ADAM and Apache Spark with H2O&rsquo;s deep learning capabilities to predict an individual&rsquo;s population group based on his or her genomic data. Our results demonstrate that we can predict these very well, with more than 99% accuracy. Our choice of technologies makes for a relatively straightforward implementation, and we expect it to be very scalable.</p>

<p>Future work could involve validating the scalability of our solution on more hardware, trying to predict a wider range of population groups (currently we only predict 3 groups), and tuning the deep learning hyper-parameters to achieve even better accuracy.</p>
]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.17.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2015/06/04/adam-0-dot-17-dot-0-released/"/>
    <updated>2015-06-04T10:49:26-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2015/06/04/adam-0-dot-17-dot-0-released</id>
    <content type="html"><![CDATA[<p>The 0.17.0 release of ADAM includes a <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.10-0.17.0">release for Scala 2.10</a> and a <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent_2.11-0.17.0">release for Scala 2.11</a>. We&rsquo;ve been working to cleanup APIs and simplify ADAM for developers. Code that isn&rsquo;t useful has been removed. Code that belongs in other downstream or upstream projects has been moved. Parquet and HTSJDK has been upgraded.</p>

<p>There are also some new features, e.g. you can now now <code>transform</code> all the SAM/BAM files in a directory by specifying the directory and there&rsquo;s a new <code>flatten</code> command that allows you to flatten the schema of ADAM data to process in Impala, Hive, SparkSQL, etc; there are also many bug fixes.</p>

<!-- more -->


<p>For more details, see the following pull requests:</p>

<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/691">691</a>: fix BAM/SAM header setting when writing on cluster</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/688">688</a>: make adamLoad public</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/694">694</a>: Fix parent reference in distribution module</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/684">684</a>: a few region-join nits</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/682">682</a>: [ADAM-681] Remove menacing error message about reqd .adam extension</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/680">680</a>: [ADAM-674] Delete Bam2ADAM.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/678">678</a>: upgrade to bdg utils 0.2.1</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/668">668</a>: [ADAM-597] Move correction out of ADAM and into a downstream project.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/671">671</a>: Bug fix in ReferenceUtils.unionReferenceSet</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/667">667</a>: [ADAM-666] Clean up key not found error in partitioner code.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/656">656</a>: Update Vcf2ADAM.scala</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/652">652</a>: added filterByOverlappingRegion in GeneFeatureRDDFunctions</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/650">650</a>: [ADAM-649] Support transform of all BAM/SAM files in a directory.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/647">647</a>: [ADAM-646] Special case reads with &lsquo;*&rsquo; quality during BQSR.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/645">645</a>: [ADAM-634] Create a local ParquetLister for testing purposes.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/633">633</a>: [Adam] Tests for SAMRecordConverter.scala</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/641">641</a>: [ADAM-640] Fix incorrect exclusion for org.seqdoop.htsjdk.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/632">632</a>: [ADAM-631] Allow VCF conversion to sort on output after coalescing.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/628">628</a>: [ADAM-627] Makes ReferenceFile trait extend Serializable.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/637">637</a>: check for mac brew alternate spark install structure</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/624">624</a>: Conceptual fix for duplicate marking and sorting stragglers</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/629">629</a>: [ADAM-604] Remove normalization code.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/630">630</a>: Add flatten command.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/619">619</a>: [ADAM-540] Move to new HTSJDK release; should support Java 8.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/626">626</a>: [ADAM-625] Enable globbing for BAM.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/621">621</a>: Removes the predicates package.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/620">620</a>: [ADAM-600] Adding RegionJoin trait.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/616">616</a>: [ADAM-565] Upgrade to Parquet filter2 API.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/613">613</a>: [ADAM-612] Point to proper k-mer counters.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/588">588</a>: [ADAM-587] Clean up loading checks.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/592">592</a>: [ADAM-513] Remove ReferenceMappable trait.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/606">606</a>: [ADAM-605] Remove visualization code.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/596">596</a>: [ADAM-595] Delete the &lsquo;comparisons&rsquo; code.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/590">590</a>: [ADAM-589] Removed pileup code.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/586">586</a>: [ADAM-452] Fixes SM attribute on ADAM to BAM conversion.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/584">584</a>: [ADAM-583] Add k-mer counting functionality for nucleotide contig fragments</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.16.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2015/02/18/adam-0-dot-16-dot-0-released/"/>
    <updated>2015-02-18T16:32:31-08:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2015/02/18/adam-0-dot-16-dot-0-released</id>
    <content type="html"><![CDATA[<p><a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-0.16.0">ADAM 0.16.0</a> is now available.</p>

<p>This release improves the performance of Base Quality Score Recalibration (BQSR) by 3.5x, adds support for multiline FASTQ input, visualization of variants when given VCF input, includes a new RegionJoin implementation that is shuffle-based, and adds new methods for region coverage calculations.</p>

<p>Drop into our Gitter channel to talk with us about this release</p>

<p><a href="https://gitter.im/bigdatagenomics/adam?utm_source=badge&amp;utm_medium=badge&amp;utm_campaign=pr-badge"><img src="https://badges.gitter.im/Join%20Chat.svg" alt="Gitter" /></a></p>

<!-- more -->


<p>Complete list of changes for ADAM <code>0.16.0</code>:</p>

<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/570">570</a>: A few small conversion fixes</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/579">579</a>: [ADAM-578] Update end of read when trimming.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/564">564</a>: [ADAM-563] Add warning message when saving Parquet files with incorrect extension</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/576">576</a>: Changed hashCode implementations to improve performance of BQSR</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/569">569</a>: Typo in the narrowPeak parser</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/568">568</a>: Moved the Timers object from bdg-utils back to ADAM</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/478">478</a>: Move non-genomics code</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/550">550</a>: [ADAM-549] Added documentation for testing and CI for ADAM.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/555">555</a>: Makes maybeLoadVCF private.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/558">558</a>: Makes Features2ADAMSuite use SparkFunSuite</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/557">557</a>: Randomize ports and turn off Spark UI to reduce bind exceptions in tests</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/552">552</a>: Create test suite for FlagStat</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/554">554</a>: privatize ADAMContext.maybeLoad{Bam,Fastq}</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/551">551</a>: [ADAM-386] Multiline FASTQ input</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/542">542</a>: Variants Visualization</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/545">545</a>: [ADAM-543][ADAM-544] Fix issues with ADAM scripts and classpath</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/535">535</a>: [ADAM-441] put a check in for Nothing. Throws an IAE if no return type is provided</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/546">546</a>: [ADAM-532] Fix wigFix intermittent test failure</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/534">534</a>: [ADAM-528][ADAM-533] Adds new RegionJoin impl that is shuffle-based</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/531">531</a>: [ADAM-529] Attaching scaladoc to released distribution.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/413">413</a>: [ADAM-409][ADAM-520] Added local wigfix2bed tool</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/527">527</a>: [ADAM-526] <code>VcfAnnotation2ADAM</code> only counts once</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/523">523</a>: don&rsquo;t open non-.adam-extension files as ADAM files</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/521">521</a>: quieting wget output</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/482">482</a>: [ADAM-462] Coverage region calculation</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/515">515</a>: [ADAM-510] fix for bash syntax error; add ADDL_JARS check to adam-submit</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[Scalable genomes clustering with ADAM and Spark]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2015/02/02/scalable-genomes-clustering-with-adam-and-spark/"/>
    <updated>2015-02-02T13:49:48-08:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2015/02/02/scalable-genomes-clustering-with-adam-and-spark</id>
    <content type="html"><![CDATA[<p>In this post, we will detail how to perform simple scalable population stratification analysis, leveraging ADAM and Spark MLlib, as previously presented at <a href="http://www.slideshare.net/noootsab/lightning-fast-genomics-with-spark-adam-and-scala">scala.io</a>.</p>

<p>The data source is the set of genotypes from the <a href="http://1000genomes.org">1000genomes</a> project, resulting from whole genomes sequencing run on samples taken from about 1000 individuals with a known geographic and ethnic origin.</p>

<p>This dataset is rather large and allows us to test scalability of the methods we present here and gives us the possibility to do interesting machine learning.
Based on the data we have, we can for example:</p>

<ul>
<li>build models to classify genomes by population</li>
<li>run unsupervised learning (clustering) to see if populations are reconstructed in the model.</li>
<li>build models to infer missing genotypes</li>
</ul>


<p>We&rsquo;ve gone the second way (clustering), the line-up being the following:</p>

<ul>
<li>Setup the environment</li>
<li>Collection and extraction of the original data</li>
<li>Distribute the original data and convert it to the ADAM model</li>
<li>Collect metadata (samples labels and completeness)</li>
<li>Filter the data to match our cluster capacity (number of nodes, cpus and mem and wall clock time&hellip;)</li>
<li>Read and prepare the ADAM formatted and distributed genotypes to have them into a separable high-dimensional space (need a metric)</li>
<li>Apply the KMeans (train/predict)</li>
<li>Assess performance</li>
</ul>


<!-- more -->


<h2>Environment setup</h2>

<h3>Cluster</h3>

<p>One of the easiest way to setup an environment with flexibility on deployed resources is EC2. Especially because Spark is distributed with scripts to spawn clusters preconfigured on EC2 (see <a href="http://spark.apache.org/docs/1.2.0/ec2-scripts.html">http://spark.apache.org/docs/1.2.0/ec2-scripts.html</a>).</p>

<p>For the case we&rsquo;re discussing here, there are several points worth considering:</p>

<ul>
<li>instances flavor: we opted for <code>m3.xlarge</code> to give us more memory</li>
<li>the region: we used <code>eu-west-1</code>. Based in Europe, we&rsquo;d like to have the results nearby</li>
<li>hadoop 2: this was necessary to deal with the VCFs (use the <code>--hadoop-major-version="2"</code> argument)</li>
<li><strong>EBS</strong>: since we&rsquo;ll use the result often, we created ESB to have the data persistent even after cluster is stopped (use the <code>--ebs-vol-size="100"</code> for <code>100G</code> per instance).</li>
</ul>


<p>A cluster with 4 slaves and 1 master will take about 20 minutes to spawn. When the cluster is stopped, the data in the persistent hdfs (ESB) remains and will be readily available after the following start. They&rsquo;ll be lost only if the cluster is explicitely destroyed.</p>

<p><em>Remark</em>: the spark ec2 scripts install two instances of hdfs, ephemeral and persistent, however only the ephemeral is started. So, you&rsquo;ll need to start the persistent one yourself using:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='bash'><span class='line'>/root/persistent-hdfs/sbin/start-dfs.sh
</span></code></pre></td></tr></table></div></figure>


<p>It can also be insteresting to shutdown the ephemeral (to save some memory for instance).</p>

<h3>s3cmd</h3>

<p>Since the data we use is available on S3, a client is required, it is worthwhile to install <code>s3cmd</code> if some data management is done from the shell.</p>

<p>Luckily, it&rsquo;s very simple, and everything is explained <a href="http://s3tools.org/s3cmd">here</a>.</p>

<h3>Spark Notebook</h3>

<p>For the operational part, we use the <a href="http://github.com/andypetrella/spark-notebook">Spark Notebook</a>. It is our favorite choice because we need something that can rerun our tasks and accomodate easily for changes, in an interactive way.</p>

<p>The easiest is to download the distribution that <strong>matches</strong> both the spark and hadoop versions installed on the cluster. The distributions are available on <a href="https://s3.eu-central-1.amazonaws.com/spark-notebook/index.html">s3</a> or <a href="https://registry.hub.docker.com/u/andypetrella/spark-notebook/">docker</a>, here is the <a href="https://s3.eu-central-1.amazonaws.com/spark-notebook/zip/spark-notebook-0.2.1-spark-1.2.0-hadoop-2.0.0-cdh4.2.0.zip">zip</a> for spark 1.2.0 and hadoop 2.0.0 cdh4.2.0.</p>

<p>Before starting the notebook, you have to make sure to load the spark environment variables (<code>/root/spark/conf/spark-env.sh</code>). And to use s3, the <code>AWS_ACCESS_KEY_ID</code> and <code>AWS_SECRET_ACCESS_KEY</code> environment variables must be set as well.</p>

<p>The spark-notebook server can then be launched from the root of its installation, using for example port 8999 (because the default port 9000 is used by hadoop):</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='bash'><span class='line'>bin/spark-notebook -Dhttp.port<span class="o">=</span>8999
</span></code></pre></td></tr></table></div></figure>


<p>You can access the UI in your browser on localhost:8999 by opening an ssh tunnel, for exemple from you local machine issuing:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='bash'><span class='line'>ssh -L 8999:localhost:8999 &lt;spark-master&gt;
</span></code></pre></td></tr></table></div></figure>


<p>It might also be required to open the 8999 port on the ec2 console.</p>

<p>In the distribution, a notebook called <code>Clustering Genomes using Adam and MLLib</code> contains the code this blog post is illustrating.</p>

<h2>Data collection</h2>

<p>The 1000 genomes project genotypes are available in VCF format from <a href="http://ftp.1000genomes.ebi.ac.uk/vol1/ftp/phase1/analysis_results/integrated_call_sets/">ftp servers</a> (ncbi and ebi) and also in <a href="http://aws.amazon.com/1000genomes/">s3</a>.</p>

<p>While repositories with such datasets converted in ADAM format are under development (f.i. <a href="https://github.com/bigdatagenomics/eggo">eggo</a>), most datasets have to be collected from traditional (e.g ftp servers) sources and distributed/converted for scalable processing.</p>

<p>The master node EBS disk is used as a buffer space to get the gzipped vcf files (one per chromosome), decompress them and send them to hdfs. Below, you&rsquo;ll find the flow for chomosome 1.</p>

<h3>Get the VCF for chromosome 1</h3>

<p>With the EBS disk mounted on <code>/vol0</code>:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
</pre></td><td class='code'><pre><code class='bash'><span class='line'><span class="nb">cd</span> /vol0/data
</span><span class='line'>s3cmd get s3://1000genomes/phase1/analysis_results/integrated_call_sets/ALL.chr1.integrated_phase1_v3.20101123.snps_indels_svs.genotypes.vcf.gz
</span></code></pre></td></tr></table></div></figure>


<h3>Decompress</h3>

<p>As seen above, the files are gizzed, hence we need to decompress them. However, it takes quite a while, so launch the following command and grab a beer!</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='bash'><span class='line'>gunzip ALL.chr1.integrated_phase1_v3.20101123.snps_indels_svs.genotypes.vcf.gz
</span></code></pre></td></tr></table></div></figure>


<p>This task takes around <strong>one hour</strong>, as we&rsquo;ll see later on, it explains why ADAM is so important when dealing with such data.</p>

<h3>Put VCF in persistent HDFS</h3>

<p>The unzipped vcf file then has to be copied to hdfs in order to be readable with ADAM. This is optional but then, the convertion has to be done from the driver (where the VCF resides) rather than on the cluster.</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='bash'><span class='line'>/root/persistent-hdfs/bin/hadoop fs -put ALL.chr1.integrated_phase1_v3.20101123.snps_indels_svs.genotypes.vcf /data/ALL.chr1.vcf
</span></code></pre></td></tr></table></div></figure>


<h3>Free some space on disk</h3>

<p>Delete VCF from disk! Along the same line, after having converted the VCF in ADAM and saved either on the hdfs or in s3, it can be good to remove the VCF from hdfs and save space.</p>

<h2>Notebook</h2>

<p>In the next section we&rsquo;ll cover the nitty gritty details of our exploration and results.</p>

<p>Although some code excerpts are presented, yet seeing them running can improve satisfaction or reduce perplexity.</p>

<p>That&rsquo;s why we created some notebooks for you!
To use them, launch the Spark Notebook as descrived above, you&rsquo;ll see them in the default list:</p>

<ul>
<li>Convert ADAM</li>
<li>Read 1000Genomes dataset (chr-N)</li>
<li>Clustering Genomics Data using Adam and MLLib</li>
</ul>


<p>Here is a screenshot of the clustering analysis notebook:</p>

<p><img class="center" src="http://bigdatagenomics.github.io/images/1k-genomes-stratification.png"></p>

<h2>Data Analysis</h2>

<h3>Data preparation (Convert VCF to ADAM)</h3>

<p>Now that the VCF file is in HDFS, we can use ADAM and our cluster to convert it to the ADAM format, which undr the hood is a parquet (optimized) version based on the <a href="https://github.com/bigdatagenomics/bdg-formats">bdg-formats</a> schema (in avro). The resulting data consists of partitions saved as gz files (each of size 7MB), either on the cluster hdfs or on s3. In our case, we saved on both, a local copy for performance and a s3 copy reusable on other clusters.</p>

<p>The code to do this is pretty trivial:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
<span class='line-number'>9</span>
<span class='line-number'>10</span>
<span class='line-number'>11</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="c1">// UTIL FUNCTION TO MAKE HDFS URLS</span>
</span><span class='line'><span class="k">def</span> <span class="n">hu</span><span class="o">(</span><span class="n">s</span><span class="k">:</span><span class="kt">String</span><span class="o">)</span> <span class="k">=</span> <span class="n">s</span><span class="s">&quot;hdfs://$master:9010/data/$s&quot;</span>
</span><span class='line'>
</span><span class='line'><span class="c1">// INPUT AND OUTPUT FILES ON HDFS</span>
</span><span class='line'><span class="k">val</span> <span class="n">vcfFile</span> <span class="k">=</span> <span class="n">hu</span><span class="o">(</span><span class="s">&quot;/data/ALL.chr1.vcf&quot;</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">outputFile</span> <span class="k">=</span> <span class="n">vcfFile</span><span class="o">+</span><span class="s">&quot;.adam&quot;</span>
</span><span class='line'>
</span><span class='line'><span class="c1">// READ-CONVERT-SAVE</span>
</span><span class='line'><span class="k">val</span> <span class="n">variantContext</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[</span><span class="kt">VariantContext</span><span class="o">]</span> <span class="k">=</span> <span class="n">sparkContext</span><span class="o">.</span><span class="n">adamVCFLoad</span><span class="o">(</span><span class="n">vcfFile</span><span class="o">,</span> <span class="n">dict</span> <span class="k">=</span> <span class="nc">None</span><span class="o">)</span>
</span><span class='line'><span class="k">val</span> <span class="n">genotypes</span> <span class="k">=</span> <span class="n">variantContext</span><span class="o">.</span><span class="n">flatMap</span><span class="o">(</span><span class="n">p</span> <span class="k">=&gt;</span> <span class="n">p</span><span class="o">.</span><span class="n">genotypes</span><span class="o">)</span>
</span><span class='line'><span class="n">gts</span><span class="o">.</span><span class="n">adamParquetSave</span><span class="o">(</span><span class="n">outputFile</span><span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<h3>Samples: location filter and population labels</h3>

<p>For practical reasons (available resources), we will not train the k-means model on all variants. We select a pretty arbitrary slice of a chromosome to limit ourselves to a dataset size that is processed in a few minutes.</p>

<p>For example, selecting genotypes for variants located on chromosome1 between position 1 and 1,000,000 is done with a simple filter:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">start</span> <span class="k">=</span> <span class="mi">1</span>
</span><span class='line'><span class="k">val</span> <span class="n">end</span> <span class="k">=</span> <span class="mi">1000000</span>
</span><span class='line'><span class="k">val</span> <span class="n">sampledGts</span> <span class="k">=</span> <span class="n">genotypes</span><span class="o">.</span><span class="n">filter</span><span class="o">(</span><span class="n">g</span> <span class="k">=&gt;</span> <span class="o">(</span><span class="n">g</span><span class="o">.</span><span class="n">getVariant</span><span class="o">.</span><span class="n">getStart</span> <span class="o">&gt;=</span> <span class="n">start</span> <span class="o">&amp;&amp;</span> <span class="n">g</span><span class="o">.</span><span class="n">getVariant</span><span class="o">.</span><span class="n">getEnd</span> <span class="o">&lt;=</span> <span class="n">end</span><span class="o">)</span> <span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<p>Our protocol consists in measuring how the processing a fixed sample will scale with the cluster size. We also check how performance scales with dataset size by varying the number of variants.</p>

<p>Also, we do not include all populations, the reason is that populations relationships are best represented by hierarchical clustering, using simple K-means will not work well if we do not flatten the structure. So we select only 3 populations and train the K-means with 3 clusters. This really aims at targeting the purpose of evaluating the technologies, not discovering something original in the data.</p>

<p>The samples populations are available from the 1000genomes data repository and are converted into a map with samples IDs as keys and populations labels as value. This map is then broadcasted in the cluster to avoid shipping it in every closure:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
</pre></td><td class='code'><pre><code class='bash'><span class='line'><span class="c"># IN THE SHELL...</span>
</span><span class='line'>wget ftp://ftp.1000genomes.ebi.ac.uk/vol1/ftp/release/20130502/integrated_call_samples_v3.20130502.ALL.panel -O /vol0/data/ALL.panel
</span></code></pre></td></tr></table></div></figure>


<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
<span class='line-number'>9</span>
<span class='line-number'>10</span>
<span class='line-number'>11</span>
<span class='line-number'>12</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="c1">// IN THE NOTEBOOK</span>
</span><span class='line'><span class="k">val</span> <span class="n">panelFile</span> <span class="k">=</span> <span class="s">&quot;/vol0/data/ALL.panel&quot;</span>
</span><span class='line'>
</span><span class='line'><span class="c1">// populations to select</span>
</span><span class='line'><span class="k">val</span> <span class="n">pops</span> <span class="k">=</span> <span class="nc">Set</span><span class="o">(</span><span class="s">&quot;GBR&quot;</span><span class="o">,</span> <span class="s">&quot;ASW&quot;</span><span class="o">,</span> <span class="s">&quot;CHB&quot;</span><span class="o">)</span>
</span><span class='line'>
</span><span class='line'><span class="c1">// TRANSFORM THE panelFile Content in the sampleID -&gt; population map</span>
</span><span class='line'><span class="c1">// containing the populations of interest (pops)</span>
</span><span class='line'><span class="k">val</span> <span class="n">panel</span><span class="k">:</span> <span class="kt">Map</span><span class="o">[</span><span class="kt">String</span>, <span class="kt">String</span><span class="o">]</span> <span class="k">=</span> <span class="o">...</span>
</span><span class='line'>
</span><span class='line'><span class="c1">// broadcast the panel </span>
</span><span class='line'><span class="k">val</span> <span class="n">bPanel</span> <span class="k">=</span> <span class="n">sparkContext</span><span class="o">.</span><span class="n">broadcast</span><span class="o">(</span><span class="n">panel</span><span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<p>And we can filter the genotypes for hte selected populations:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="n">genotypes</span><span class="o">.</span><span class="n">filter</span><span class="o">(</span><span class="n">g</span> <span class="k">=&gt;</span>  <span class="n">bPanel</span><span class="o">.</span><span class="n">value</span><span class="o">.</span><span class="n">contains</span><span class="o">(</span><span class="n">g</span><span class="o">.</span><span class="n">getSampleId</span><span class="o">))</span>
</span></code></pre></td></tr></table></div></figure>


<p>To understand if the k-means extracted population structure, we will compare the clusters assignments with the populations labels of the samples, i.e. in a confusion matrix.</p>

<h3>Missing data</h3>

<p>Some data is missing, a few genotypes are not present in the Sample x Variant matrix. As we have plenty of variants to play with (up to ~ 30,000,000), removing the ones for which some genotypes are missing across the 1000 samples does not hurt.</p>

<p>First, we must identify all such incomplete variants and optionally save the list on disk, this can come handy for the prediction phase. For convenience (later runs), the list of complete list of variants is saved as well:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
<span class='line-number'>9</span>
<span class='line-number'>10</span>
<span class='line-number'>11</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="c1">// NUMBER OF SAMPLES</span>
</span><span class='line'><span class="k">val</span> <span class="n">sampleCount</span> <span class="k">=</span> <span class="n">genotypes</span><span class="o">.</span><span class="n">map</span><span class="o">(</span><span class="k">_</span><span class="o">.</span><span class="n">getSampleId</span><span class="o">.</span><span class="n">toString</span><span class="o">.</span><span class="n">hashCode</span><span class="o">).</span><span class="n">distinct</span><span class="o">.</span><span class="n">count</span>
</span><span class='line'>
</span><span class='line'><span class="c1">// A VARIANT SHOULD HAVE sampleCount GENOTYPES</span>
</span><span class='line'><span class="c1">// variantId returns string identifier for a variant (see notebook ref...)</span>
</span><span class='line'><span class="k">val</span> <span class="n">variantsById</span> <span class="k">=</span> <span class="n">gts</span><span class="o">.</span><span class="n">keyBy</span><span class="o">(</span><span class="n">g</span> <span class="k">=&gt;</span> <span class="n">variantId</span><span class="o">(</span><span class="n">g</span><span class="o">).</span><span class="n">hashCode</span><span class="o">).</span><span class="n">groupByKey</span>
</span><span class='line'><span class="k">val</span> <span class="n">missingVariantsRDD</span> <span class="k">=</span> <span class="n">variantsById</span><span class="o">.</span><span class="n">filter</span> <span class="o">{</span> <span class="k">case</span> <span class="o">(</span><span class="n">k</span><span class="o">,</span> <span class="n">it</span><span class="o">)</span> <span class="k">=&gt;</span> <span class="n">it</span><span class="o">.</span><span class="n">size</span> <span class="o">!=</span> <span class="n">sampleCount</span> <span class="o">}.</span><span class="n">keys</span>
</span><span class='line'><span class="n">missingVariantsRDD</span><span class="o">.</span><span class="n">saveAsObjectFile</span><span class="o">(</span><span class="s">&quot;/tmp/model/missing-variants&quot;</span><span class="o">)</span>
</span><span class='line'>
</span><span class='line'><span class="c1">// could be broadcased as well...</span>
</span><span class='line'><span class="k">val</span> <span class="n">missingVariants</span> <span class="k">=</span> <span class="n">missingVariantsRDD</span><span class="o">.</span><span class="n">collect</span><span class="o">().</span><span class="n">toSet</span>
</span></code></pre></td></tr></table></div></figure>


<p>Then, we remove all these incomplete variants from the dataset:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="n">genotypes</span><span class="o">.</span><span class="n">filter</span> <span class="o">{</span> <span class="n">g</span> <span class="k">=&gt;</span> <span class="o">!</span> <span class="o">(</span><span class="n">missingVariants</span> <span class="n">contains</span> <span class="n">variantId</span><span class="o">(</span><span class="n">g</span><span class="o">).</span><span class="n">hashCode</span><span class="o">)</span> <span class="o">}</span>
</span></code></pre></td></tr></table></div></figure>


<h3>Features extraction</h3>

<p>Before running the clustering algorithm (K-Means), we need to transform the data from a flat representation (RDD of genotypes) to a more structured one, matching the input requirements of MLLib training methods.</p>

<p>Each sample must be represented by a vector of features in a space with a defined metric. MLLib relies on the breeze library for linear algebra and the euclidian metric is the one provided.</p>

<p>Usually a Mahanatan distance is used in genetics, with genotypes encoded as 0, 1 or 2 (1 being the heterozygote). We have used this encoding albeit with breeze provides only the euclidian distance. A <code>asDouble(Genotype)</code> function does the genotype encoding.</p>

<p>The rdd tranformations to obtain encoded genotypes, grouped by sampleId are:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">sampleToData</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[(</span><span class="kt">String</span>, <span class="o">(</span><span class="kt">Double</span>, <span class="kt">Int</span><span class="o">))]</span> <span class="k">=</span>
</span><span class='line'>    <span class="n">genotypes</span><span class="o">.</span><span class="n">map</span> <span class="o">{</span> <span class="n">g</span> <span class="k">=&gt;</span> <span class="o">(</span><span class="n">g</span><span class="o">.</span><span class="n">getSampleId</span><span class="o">.</span><span class="n">toString</span><span class="o">,</span> <span class="o">(</span><span class="n">asDouble</span><span class="o">(</span><span class="n">g</span><span class="o">),</span> <span class="n">variantId</span><span class="o">(</span><span class="n">g</span><span class="o">).</span><span class="n">hashCode</span><span class="o">))</span> <span class="o">}</span>
</span><span class='line'>
</span><span class='line'><span class="k">val</span> <span class="n">groupedSampleToData</span> <span class="k">=</span> <span class="n">sampleToData</span><span class="o">.</span><span class="n">groupByKey</span>
</span></code></pre></td></tr></table></div></figure>


<p>And for each sample, we sort the genotypes by variant (i.e. variant name hash) so that each sample vector has its features consistently ordered (Vector is the MLLib Vector class):</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
<span class='line-number'>4</span>
<span class='line-number'>5</span>
<span class='line-number'>6</span>
<span class='line-number'>7</span>
<span class='line-number'>8</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">def</span> <span class="n">makeSortedVector</span><span class="o">(</span><span class="n">gts</span><span class="k">:</span> <span class="kt">Iterable</span><span class="o">[(</span><span class="kt">Double</span>, <span class="kt">Int</span><span class="o">)])</span><span class="k">:</span> <span class="kt">Vector</span> <span class="o">=</span> <span class="nc">Vectors</span><span class="o">.</span><span class="n">dense</span><span class="o">(</span> <span class="n">gts</span><span class="o">.</span><span class="n">toArray</span><span class="o">.</span><span class="n">sortBy</span><span class="o">(</span><span class="k">_</span><span class="o">.</span><span class="n">_2</span><span class="o">).</span><span class="n">map</span><span class="o">(</span><span class="k">_</span><span class="o">.</span><span class="n">_1</span><span class="o">)</span> <span class="o">)</span>
</span><span class='line'>
</span><span class='line'><span class="k">val</span> <span class="n">dataPerSampleId</span><span class="k">:</span><span class="kt">RDD</span><span class="o">[(</span><span class="kt">String</span>, <span class="kt">MLVector</span><span class="o">)]</span> <span class="k">=</span>
</span><span class='line'>    <span class="n">groupedSampleToData</span><span class="o">.</span><span class="n">mapValues</span> <span class="o">{</span> <span class="n">it</span> <span class="k">=&gt;</span>
</span><span class='line'>      <span class="n">makeSortedVector</span><span class="o">(</span><span class="n">it</span><span class="o">)</span>
</span><span class='line'>    <span class="o">}</span>
</span><span class='line'>
</span><span class='line'><span class="k">val</span> <span class="n">dataFrame</span><span class="k">:</span><span class="kt">RDD</span><span class="o">[</span><span class="kt">MLVector</span><span class="o">]</span> <span class="k">=</span> <span class="n">dataPerSampleId</span><span class="o">.</span><span class="n">values</span>
</span></code></pre></td></tr></table></div></figure>


<p>At this stage, we have a dataset ready for training with MLLib!</p>

<h3>Training and Predictions with K-Means</h3>

<p>Training the model is achieved very easily, in this case with 3 clusters and 10 iterations&hellip;</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">model</span><span class="k">:</span> <span class="kt">KMeansModel</span> <span class="o">=</span> <span class="nc">KMeans</span><span class="o">.</span><span class="n">train</span><span class="o">(</span><span class="n">dataFrame</span><span class="o">,</span> <span class="mi">3</span><span class="o">,</span> <span class="mi">10</span><span class="o">)</span>
</span></code></pre></td></tr></table></div></figure>


<p>In order to check whether the samples clusters match the samples populations, we used the model to predict the cluster of each sample and compared these with the population label of the sample.</p>

<p>There is one prediction for each sample (the key of the predictions RDD), as value we keep the predicted class (the cluster number as Int) and the population label:</p>

<figure class='code'><div class="highlight"><table><tr><td class="gutter"><pre class="line-numbers"><span class='line-number'>1</span>
<span class='line-number'>2</span>
<span class='line-number'>3</span>
</pre></td><td class='code'><pre><code class='scala'><span class='line'><span class="k">val</span> <span class="n">predictions</span><span class="k">:</span> <span class="kt">RDD</span><span class="o">[(</span><span class="kt">String</span>, <span class="o">(</span><span class="kt">Int</span>, <span class="kt">String</span><span class="o">))]</span> <span class="k">=</span> <span class="n">dataPerSampleId</span><span class="o">.</span><span class="n">map</span><span class="o">(</span><span class="n">elt</span> <span class="k">=&gt;</span> <span class="o">{</span>
</span><span class='line'>    <span class="o">(</span><span class="n">elt</span><span class="o">.</span><span class="n">_1</span><span class="o">,</span> <span class="o">(</span> <span class="n">model</span><span class="o">.</span><span class="n">predict</span><span class="o">(</span><span class="n">elt</span><span class="o">.</span><span class="n">_2</span><span class="o">),</span> <span class="n">bPanel</span><span class="o">.</span><span class="n">value</span><span class="o">.</span><span class="n">get</span><span class="o">(</span><span class="n">elt</span><span class="o">.</span><span class="n">_1</span><span class="o">)))</span>
</span><span class='line'><span class="o">})</span>
</span></code></pre></td></tr></table></div></figure>


<p>We can extract and display the confusion matrix, clearly showing that the clustering actually matches pretty well the population:</p>

<pre><code>    #0   #1   #2
GBR  0    0   89
ASW 54    0    7
CHB  0   97    0
</code></pre>

<h3>Performance</h3>

<p>We have taken a few metrics to get an idea of how the ADAM and MLLib scale with available resources and dataset size. We ran the notebook on 2 clusters (2 and 20 slaves).
We processed 3 datasets, one is a very limited sample (2,168 variants) the next is a medium one (121,023 variants). We also processed the entire chromosome 22 but only on the 20 nodes cluster (491,222 variants).</p>

<p>Note that we processed 114 partitions, which in the case of the 20 nodes (80 cores) cluster leads to a penalty because on average, 114/80 tasks are assigned to a core while 2 to 3 minimum are required to evenly distribute cores utilization.
We systematically lose a factor 1.5 in performance on the 20 nodes cluster.</p>

<pre><code>                                     2 NODES       20 NODES

Cluster launch:                       10 min         30 min 

Count chr22 genotypes (from S3):       6 min        1.1 min 
Save chr22 from s3 to HDFS:           26 min        3.5 min 
Count chr22 genotypes (from HDFS):    10 min        1.4 min 

2168 Variants
Missing data (collect):                7 sec          3 sec
Train (10 iterations):                20 sec         30 sec
Predict (collect):                   0.5 sec        0.3 sec

121,023 Variants
Missing data (collect):              7.8 min         33 sec
Train (10 iterations):               2.1 min         28 sec
Predict (collect):                     8 sec          2 sec

491,222 Variants
Missing data (collect):                             3.7 min
Train (10 iterations):                              1.6 min
Predict (collect):                                   25 sec
</code></pre>

<p>We have not gathered here other metrics like memory utilization, amount of data shuffled etc, but this gives already a good idea on the scalability of the processing with ADAM and MLLib.</p>

<h3>Conclusions</h3>

<p>We have shown a flow to manipulate genetic data at scale with ADAM and MLLib. With the help of the spark notebook, it is pretty easy to develop such scalable genomes processing on top of ADAM and Spark. The cluster size is very transparent for the development phase, and the system proves to scale well with dataset size and number of node.</p>

<p>All in all, it becomes really fun and efficient to engage into distributed computing with such good APIs (ADAM, Spark), underlying data formats (parquet, avro), infrastructure (EC2 and the like), machine learning implementations (MLLib) and interactive development/execution environments (Spark-notebook).</p>
]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.15.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2014/11/26/adam-0-dot-15-dot-0-released/"/>
    <updated>2014-11-26T10:27:00-08:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2014/11/26/adam-0-dot-15-dot-0-released</id>
    <content type="html"><![CDATA[<p>We&rsquo;re proud to announce the <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-0.15.0">release of ADAM 0.15.0</a>!</p>

<p>This release includes important memory and performance improvements, better documentation, new features and many bug fixes.</p>

<p>We have upgraded from Parquet <code>1.4.3</code> to <code>1.6.0</code> in order to dramatically reduce our memory footprint. For string columns with dictionary encoding, the amount of memory used will now be proportional to the number of dictionary entries instead of the number of records materialized. Parquet 1.6.0 also provides improved column statistics and the ability to store custom metadata. We will use these features in subsequent ADAM releases to improve random access performance. Note that ADAM <code>0.14.0</code> had a serious memory regression so upgrading to <code>0.15.0</code> as soon as possible is recommended.</p>

<p>We are unhappy with the quality of the documentation we have been providing ADAM users and are working to improve it. With this release, all documentation has been centralized into the <code>./docs</code> directory and we&rsquo;re using <code>pandoc</code> to convert the Markdown source into both PDF and HTML formats. We are committed to improving the content of the docs over time and welcome your pull requests!</p>

<p>This release includes <a href="https://repo1.maven.org/maven2/org/bdgenomics/adam/adam-distribution/0.15.0/">binary distributions</a> to make it easier for you to get up and running with ADAM. We do not include any Spark or Hadoop artifacts in order to prevent versioning conflicts. For application developers, we have also changed our Spark and Hadoop dependencies to <code>provided</code>. This means that you can more easily running on ADAM using your preferred Spark and Hadoop version and configuration. We want to make deployment as easy as possible.</p>

<p>This release includes numerous features and bug fixes that are detailed below:</p>

<!-- more -->


<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/509">509</a>: Add a &lsquo;distribution&rsquo; module to create assemblies</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/508">508</a>: Upgrade from Parquet 1.4.3 to 1.6.0rc4</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/498">498</a>: [ADAM-496] Changes VCF to flat ADAM command name and usage</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/500">500</a>: [ADAM-495] Require SPARK_HOME for adam-submit</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/501">501</a>: [ADAM-499] Add -onlyvariants option to vcf2adam</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/507">507</a>: [ADAM-505] Removed <code>adam-local</code> from docs</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/504">504</a>: [ADAM-502] Add missing Long implicit to ColumnReaderInput</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/503">503</a>: [ADAM-473] Make RecordCondition and FieldCondition public</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/494">494</a>: Fix foreach block for vcf ingest</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/492">492</a>: Documentation cleanup and style improvements</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/481">481</a>: [ADAM-480] Switch assembly to single goal.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/487">487</a>: [ADAM-486] Add port option to viz command.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/469">469</a>: [ADAM-461] Fix ReferenceRegion and ReferencePosition impl</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/440">440</a>: [ADAM-439] Fix ADAM to account for BDG-FORMATS-35: Avro uses Strings</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/470">470</a>: added ReferenceMapping for Genotype, filterByOverlappingRegion for GenotypeRDDFunctions</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/468">468</a>: refactor RDD loading; explicitly load alignments</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/474">474</a>: Consolidate documentation into a single location in source.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/471">471</a>: Fixed typo on MAVEN_OPTS quotation mark</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/467">467</a>: [ADAM-436] Optionally output original qualities to fastq</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/451">451</a>: add <code>adam view</code> command, analogous to <code>samtools view</code></li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/466">466</a>: working examples on .sam included in repo</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/458">458</a>: Remove unused val from Reads2Ref</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/438">438</a>: Add ability to save paired-FASTQ files</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/457">457</a>: A few random Predicate-related cleanups</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/459">459</a>: a few tweaks to scripts/jenkins-test</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/460">460</a>: Project only the sequence when kmer/qmer counting</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/450">450</a>: Refactor some file writing and reading logic</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/455">455</a>: [ADAM-454] Add serializers for Avro objects which don&rsquo;t have serializers</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/447">447</a>: Update the contribution guidelines</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/453">453</a>: Better null handling for isSameContig utility</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/417">417</a>: Stores original position and original cigar during realignment.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/449">449</a>: read “OQ” attr from structured SAMRecord field</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/446">446</a>: Revert &ldquo;[ADAM-237] Migrate to Chill serialization libraries.&rdquo;</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/437">437</a>: random nits</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/434">434</a>: Few transform tweaks</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/435">435</a>: [ADAM-403] Remove seqDict from RegionJoin</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/431">431</a>: A few tweaks, typo corrections, and random cleanups</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/430">430</a>: [ADAM-429] adam-submit now handles args correctly.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/427">427</a>: Fixes for indel realigner issues</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/418">418</a>: [ADAM-416] Removing &lsquo;ADAM&rsquo; prefix</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/404">404</a>: [ADAM-327] Adding gene, transcript, and exon models.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/414">414</a>: Fix error in <code>adam-local</code> alias</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/415">415</a>: Update README.md to reflect Spark 1.1</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/412">412</a>: [ADAM-411] Updated usage aliases in README. Fixes #411.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/408">408</a>: [ADAM-405] Add FASTQ output.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/385">385</a>: [ADAM-384] Adds import from FASTQ.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/400">400</a>: [ADAM-399] Fix link to schemas.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/396">396</a>: [ADAM-388] Sets Kryo serialization with &mdash;conf args</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/394">394</a>: [ADAM-393] Adds knobs to SparkContext creation in SparkFunSuite</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/391">391</a>: [ADAM-237] Migrate to Chill serialization libraries.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/380">380</a>: Rewrite of MarkDuplicates which seems to improve performance</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/387">387</a>: fix some deprecation warnings</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[Lightning Fast Genomics]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2014/11/03/lightning-fast-genomics/"/>
    <updated>2014-11-03T08:24:15-08:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2014/11/03/lightning-fast-genomics</id>
    <content type="html"><![CDATA[<p><a href="https://twitter.com/noootsab">Andy Petrella</a> and <a href="https://twitter.com/xtordoir">Xavier Tordoir</a> gave a talk, <em><a href="http://scala.io/talks.html#/#SVK-108">Scalable Genomics with ADAM</a></em>, at <a href="http://scala.io/">Scala.IO</a> in Paris, France.</p>

<blockquote><p>We are at a time where biotech allow us to get personal genomes for $1000. Tremendous progress since the 70s in DNA sequencing have been done, e.g. more samples in an experiment, more genomic coverages at higher speeds. Genomic analysis standards that have been developed over the years weren&rsquo;t designed with scalability and adaptability in mind. In this talk, we’ll present a game changing technology in this area, ADAM, initiated by the AMPLab at Berkeley. ADAM is framework based on Apache Spark and the Parquet storage. We’ll see how it can speed up a sequence reconstruction to a factor 150.</p></blockquote>

<p>Andy and Xavier&rsquo;s talk included a demo: using Spark&rsquo;s MLlib to do population stratification across 1000 Genomes in just a few minutes in the cloud using Amazon Web Services (AWS). Their talk highlights the advantages of building on open-source technologies, like Apache <a href="http://spark.apache.org">Spark</a> and <a href="http://parquet.io">Parquet</a>, designed for performance and scale.</p>

<p>Andy also modified the <a href="https://github.com/Bridgewater/scala-notebook">Scala Notebook</a> to create <a href="https://github.com/andypetrella/spark-notebook">Spark Notebook</a> which enables visualization and reproducible analysis on Apache Spark inside a web browser. A great addition to the Spark ecosystem!</p>

<iframe src="http://bigdatagenomics.github.io//www.slideshare.net/slideshow/embed_code/40715122" width="850" height="710" frameborder="0" marginwidth="0" marginheight="0" scrolling="no" style="border:1px solid #CCC; border-width:1px; margin-bottom:5px; max-width: 100%;" allowfullscreen> </iframe>


<p> <div style="margin-bottom:5px"> <strong> <a href="http://bigdatagenomics.github.io//fr.slideshare.net/noootsab/lightning-fast-genomics-with-spark-adam-and-scala" title="Lightning fast genomics with Spark, Adam and Scala" target="_blank">Lightning fast genomics with Spark, Adam and Scala</a> </strong> from <strong><a href="http://bigdatagenomics.github.io//www.slideshare.net/noootsab" target="_blank">noootsab</a></strong> </div></p>
]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.14.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2014/09/17/adam-0-dot-14-dot-0-released/"/>
    <updated>2014-09-17T14:33:35-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2014/09/17/adam-0-dot-14-dot-0-released</id>
    <content type="html"><![CDATA[<p>ADAM <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-0.14.0">0.14.0</a> is now available. Special thanks to Arun Ahuja, Timothy Danford, Michael L Heuer, Uri Laserson, Frank Nothaft, Andy Petrella and Ryan Williams for their contributions to this release!</p>

<p>This release uses the <a href="https://spark.apache.org/releases/spark-release-1-1-0.html">newly-released Apache Spark 1.1.0</a> which brings operational and performance improvements in Spark core. Two new scripts, <code>adam-shell</code> and <code>adam-submit</code>, allow you to use ADAM via the Spark shell or the Spark submit script in addition to the ADAM CLI.</p>

<p>The <a href="http://sourceforge.net/projects/hadoop-bam/">Hadoop-BAM</a> team is now publishing <a href="http://search.maven.org/#search%7Cga%7C1%7Cg%3A%22org.seqdoop%22">their artifacts to Maven Central</a> (yea!) so we no longer rely on snapshot releases. ADAM <code>0.14.0</code> uses the <code>7.0.0</code> release of Hadoop-BAM.</p>

<p>This release also adds a new Java plugin interface, improves MD tag processing as well as fixes numerous bugs.</p>

<p>We hope that you enjoy this release. Drop by <code>#adamdev</code> on freenode.net, <a href="https://twitter.com/bigdatagenomics">follow us on Twitter</a> or <a href="http://bdgenomics.org/mail/">subscribe to our mailing list</a> to stay in touch.</p>

<!-- more -->


<p>For more details, see the changelog below:</p>

<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/376">376</a>: [ADAM-375] Upgrade to Hadoop-BAM 7.0.0.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/378">378</a>: [ADAM-360] Upgrade to Spark 1.1.0.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/379">379</a>: Fix the position of the jar path in the submit.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/383">383</a>: Make Mdtags handle &lsquo;=&rsquo; and &lsquo;X&rsquo; cigar operators</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/369">369</a>: [ADAM-369] Improve debug output for indel realigner</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/377">377</a>: [ADAM-377] Update to Jenkins scripts and README.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/374">374</a>: [ADAM-372][ADAM-371][ADAM-365] Refactoring CLI to simplify and integrate with Spark model better</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/370">370</a>: [ADAM-367] Updated alias in README.md</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/368">368</a>: erasure, nonexhaustive-match, deprecation warnings</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/354">354</a>: [ADAM-353] Fixing issue with SAM/BAM/VCF header attachment when running distributed</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/357">357</a>: [ADAM-357] Added Java Plugin hook for ADAM.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/352">352</a>: Fix failing MD tag</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/363">363</a>: Adding maven assembly plugin configuration to create tarballs</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/364">364</a>: [ADAM-364] Fixing remaining cs.berkeley.edu URLs.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/362">362</a>: Remove mention of uberjar from README</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.13.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2014/08/20/adam-0-dot-13-dot-0-released/"/>
    <updated>2014-08-20T14:04:41-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2014/08/20/adam-0-dot-13-dot-0-released</id>
    <content type="html"><![CDATA[<p>ADAM <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-0.13.0">0.13.0</a> is now available!</p>

<p>This release includes <a href="https://github.com/bigdatagenomics/adam/pull/346">genome visualization</a> to view aligned reads and coverage
information over a reference region. You simply run e.g. <code>adam viz myreads.adam chr1</code> from the ADAM source directory and open
your favorite web browser to <a href="http://localhost:8080/">http://localhost:8080/</a> to view your data.</p>

<p>This release also includes a number of features and bug fixes including upgrading to Spark 1.0.1.</p>

<!-- more -->


<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/343">343</a>: Allow retrying on failure for HTTPRangedByteAccess</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/349">349</a>: Fix for a NullPointerException when hostname is null in Task Metrics</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/347">347</a>: Bug fix for genome browser</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/346">346</a>: Genome visualization</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/342">342</a>: [ADAM-309] Update to bdg-formats 0.2.0</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/333">333</a>: [ADAM-332] Upgrades ADAM to Spark 1.0.1.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/341">341</a>: [ADAM-340] Adding the TrackedLayout trait and implementation.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/337">337</a>: [ADAM-335] Updated README.md to reflect migration to appassembler.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/311">311</a>: Adding several simple normalizations.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/330">330</a>: Make mismatch and deletes positions accessible</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/334">334</a>: Moving code coverage into a profile</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/329">329</a>: Add count of mismatches to mdtag</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/328">328</a>: [ADAM-326] Adding a 5-second retry on the HttpRangedByteAccess test.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/325">325</a>: Adding documentation for commit/issue nomenclature and rebasing</li>
</ul>


<p>This summer, we also quietly pushed out a <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-0.12.1">0.12.1</a> release
that included a number of features (e.g. Parquet and indexed Parquet Spark RDDs, k-mer/q-mer counting, fixed depth prefix tries) and bug fixes:</p>

<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/308">308</a>: Fixing the &lsquo;index 0&rsquo; bug in features2adam</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/306">306</a>: Adding code for lifting over between sequences and the reference genome.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/320">320</a>: Remove extraneous implicit methods in ReferenceMappingContext</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/314">314</a>: Updates to indel realigner to improve performance and accuracy.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/319">319</a>: Adding scripts for publishing scaladoc.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/315">315</a>: Added table of (wall-clock) stage durations when print_metrics is used</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/312">312</a>: Fixing sources jar</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/313">313</a>: Making the CredentialsProperties file optional</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/267">267</a>: Parquet and indexed Parquet RDD implementations, and indices.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/301">301</a>: Add Beacon&rsquo;s AlleleCount</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/293">293</a>: Add aggregation and display of metrics obtained from Spark</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/295">295</a>: Fix broken link to ADAM specification for storing reads.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/292">292</a>: Cleaning up scaladoc generation warnings.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/289">289</a>: Modifying interleaved fastq format to be hadoop version independent.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/288">288</a>: Add ADAMFeature to Kryo registrator</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/286">286</a>: Removing some debug printout that was left in.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/287">287</a>: Cleaning hadoop dependencies</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/285">285</a>: Refactoring read groups to increase the amount of data stored.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/284">284</a>: Cleaning up build warnings.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/280">280</a>: Move to bdg-formats</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/283">283</a>: Fix reference name comment</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/282">282</a>: Minor cleanup on interleaved FASTQ input format.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/277">277</a>: Implemented HTTPRangedByteAccess.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/274">274</a>: Added clarifying note to <code>ADAMVariantContext</code></li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/279">279</a>: Simplify format-source</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/278">278</a>: Use maven license plugin to ensure source has correct license</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/268">268</a>: Adding fixed depth prefix trie implementation</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/273">273</a>: Fixes issue in reference models where strings are not sanitized on collection from avro.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/272">272</a>: Created command categories</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/269">269</a>: Adding k-mer and q-mer counting.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/271">271</a>: Consolidate Parquet logging configuration</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[Talk on ADAM at the Spark Summit]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2014/07/02/spark-summit-talk-on-adam/"/>
    <updated>2014-07-02T00:31:44-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2014/07/02/spark-summit-talk-on-adam</id>
    <content type="html"><![CDATA[<p><a href="http://www.fnothaft.net">Frank Austin Nothaft</a> gave a talk on ADAM at the <a href="http://www.spark-summit.org">Spark Summit</a> in San Francisco.</p>

<iframe src="http://bigdatagenomics.github.io//www.slideshare.net/slideshow/embed_code/36516706" width="427" height="356" frameborder="0" marginwidth="0" marginheight="0" scrolling="no" style="border:1px solid #CCC; border-width:1px 1px 0; margin-bottom:5px; max-width: 100%;" allowfullscreen> </iframe>


<p> <div style="margin-bottom:5px"> <strong> <a href="https://www.slideshare.net/fnothaft/adamspark-summit-2014" title="ADAM—Spark Summit, 2014" target="_blank">ADAM—Spark Summit, 2014</a> </strong> from <strong><a href="http://www.slideshare.net/fnothaft" target="_blank">fnothaft</a></strong> </div></p>

<p>The Spark Summit organizers will make a video of the talk available soon; we will post a link to the talk as soon as it is available.</p>
]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.12.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2014/06/17/adam-0-dot-12-dot-0-released/"/>
    <updated>2014-06-17T15:35:12-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2014/06/17/adam-0-dot-12-dot-0-released</id>
    <content type="html"><![CDATA[<p>ADAM <a href="https://github.com/bigdatagenomics/adam/releases">0.12.0</a> is now available!</p>

<p>This release includes new Parquet utilities that are part of an effort to read/write Parquet directly on S3, eliminating
the need to transfer data from S3 to HDFS for processing. This release also upgrades
ADAM to Spark 1.0 and provides new schema definitions, bug fixes and features:</p>

<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/264">264</a>: Parquet-related Utility Classes</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/259">259</a>: ADAMFlatGenotype is a smaller, flat version of a genotype schema</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/266">266</a>: Removed extra command &lsquo;BuildInformation&rsquo;</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/263">263</a>: Added AdamContext.referenceLengthFromCigar</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/260">260</a>: Modifying conversion code to resolve #112.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/258">258</a>: Adding an &lsquo;args&rsquo; parameter to the plugin framework.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/262">262</a>: Adding reference assembly name to ADAMContig.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/256">256</a>: Upgrading to Spark 1.0</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/257">257</a>: Adds toString method for sequence dictionary.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/255">255</a>: Add equals, canEqual, and hashCode methods to MdTag class</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[ADAM 0.11.0 Released]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2014/06/02/adam-0-dot-11-dot-0-released/"/>
    <updated>2014-06-02T16:48:42-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2014/06/02/adam-0-dot-11-dot-0-released</id>
    <content type="html"><![CDATA[<p>ADAM <a href="https://github.com/bigdatagenomics/adam/releases/tag/adam-parent-0.11.0">0.11.0</a> is now available.</p>

<p>This release allows you not just read but also write to SAM/BAM files, adds utilities for trimming reads,
implements contig-to-RefSeq translation, refactors SequenceDictionary to include RefSeq information (and without numeric IDs)
and prepare ADAMGenotype for incorporating reference model information, and fixes a bug in FASTA fragments.</p>

<p>For details see the following issues&hellip;</p>

<ul>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/250">250</a>: Adding ADAM to SAM conversion.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/248">248</a>: Adding utilities for read trimming.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/252">252</a>: Added a note about rebasing-off-master to CONTRIBUTING.md</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/249">249</a>: Cosmetic changes to FastaConverter and FastaConverterSuite.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/251">251</a>: CHANGES.md is updated at release instead of per pull request</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/247">247</a>: For #244, Fragments were incorrect order and incomplete</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/246">246</a>: Making sample ID field in genotype nullable.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/245">245</a>: Adding ADAMContig back to ADAMVariant.</li>
<li>ISSUE <a href="https://github.com/bigdatagenomics/adam/pull/243">243</a>: Rebase PR#238 onto master</li>
</ul>

]]></content>
  </entry>
  
  <entry>
    <title type="html"><![CDATA[Developing Big Data Genomics: A Screencast]]></title>
    <link href="http://bigdatagenomics.github.io/blog/2014/05/15/up-and-running-with-big-data-genomics/"/>
    <updated>2014-05-15T10:00:00-07:00</updated>
    <id>http://bigdatagenomics.github.io/blog/2014/05/15/up-and-running-with-big-data-genomics</id>
    <content type="html"><![CDATA[<iframe id="ytplayer" type="text/html" width="640" height="390" src="http://www.youtube.com/embed/BCoIXqUfFkU?autoplay=0&origin=http://bdgenomics.org" frameborder="0"></iframe>


<br/><br/>


<p>This short screencast is meant to get someone new to Scala, IntelliJ, and the Big Data Genomics stack up and running with a configured development environment suitable for working with or on projects like ADAM and Avocado.</p>

<p>We&rsquo;ll walk you through downloading the appropriate JDK, IntelliJ IDE, and plugings. Then we will set up the project (using ADAM as the example), generating sources, packaging the application, and building the project. Finally, we cover running tests, as well as some basic exploration and code navigation using the IDE.</p>

<hr />

<p>Note, if you have trouble using <code>mvn package</code> in the command line, you may want to add the following to your <code>.bashrc</code>, or at least export these environment variables before running <code>mvn package</code>:</p>

<pre><code>export MAVEN_OPTS="-Xmx512m -XX:MaxPermSize=128M"
export JAVA_HOME=`/usr/libexec/java_home -v 1.7`
</code></pre>

<h3>Links</h3>

<ul>
<li>00:00:14  <a href="http://www.oracle.com/technetwork/java/javase/downloads/jdk7-downloads-1880260.html">Oracle JDK 7</a></li>
<li>00:00:28  <a href="http://www.jetbrains.com/idea/download/">IntelliJ IDE</a></li>
<li>00:00:43  <a href="https://github.com/bigdatagenomics/adam">ADAM Github Repository</a></li>
</ul>

]]></content>
  </entry>
  
</feed>